Mechanistic family · features from superposition
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
Look inside a language model and pick one neuron. You will often find it fires for many unrelated
things: Python code, the French word for “cat”, and closing brackets. Such a neuron is
polysemantic (many meanings). One explanation is superposition: the model wants to store
more concepts (“features”) than it has neurons, so it packs them in as overlapping
directions in activation space. That works because most features are sparse: in any one input,
only a few of them are active, so the overlaps rarely collide.
A sparse autoencoder (SAE) tries to undo the packing. It is a small, separate network trained
to rebuild the model's activation vector through a hidden layer with many units, under a penalty that
keeps only a few units active at a time. If it works, each hidden unit stands for one concept: it
is monosemantic. These units are then called the model's “features”, given names, and
used to explain and steer the model. SAEs are among the most widely used tools in interpretability
today.
How it works on a neural network
Take an activation vector \(x \in \mathbb{R}^d\) (e.g. the residual stream of a transformer at one
token). The SAE encodes and decodes it:
\[ z = \mathrm{ReLU}(W_e x + b_e), \qquad \hat x = W_d z + b_d, \qquad
\mathcal{L} = \|x - \hat x\|^2 + \lambda \|z\|_1 . \]
\(z\) is the code (one number per feature). ReLU sets negative values to zero. The first loss
term asks for a good reconstruction. The second, an L1 penalty (the sum of absolute values,
known from the lasso), pushes most entries of \(z\) to exactly zero. \(\lambda\) trades the two off.
Usually the hidden layer is wider than \(d\) (“overcomplete”), so it has room for
more features than neurons. Column \(k\) of \(W_d\) is feature \(k\)'s direction in activation
space.
Toy example. A model stores 3 features in a 2-D space, at 120° apart:
\(u_1=(1,0)\), \(u_2=(-0.5,0.87)\), \(u_3=(-0.5,-0.87)\). An input has only feature 2 on:
\(x=u_2=(-0.5,0.87)\). The two raw neurons read \(-0.5\) and \(0.87\): both respond, and each
would also respond to the other features. Now an SAE with three hidden units, encoder rows
\(u_1,u_2,u_3\) and bias \(-0.4\): the pre-activations are \((-0.5, 1.0, -0.5) - 0.4 =
(-0.9, 0.6, -0.9)\), and ReLU gives \(z=(0, 0.6, 0)\). Only unit 2 fires. Three features, cleanly
separated, from a 2-D space.
Recipe
- Record many activation vectors from the model (one layer, many inputs).
- Normalise them, then train the SAE on the reconstruction loss plus \(\lambda\cdot\) L1 of the code.
- Check reconstruction quality (fraction of variance explained) and sparsity (average number of active units, \(L_0\)).
- Interpret each unit: list the inputs where it fires most, or correlate it with known concepts.
- Test causally: set a feature to zero (or clamp it high), decode, put the result back into the model, and see whether the behaviour changes as the feature's name predicts.
From a neural network to the Atari
| Activation vector \(x\) | The 128 bytes of RIOT RAM at one video frame. A recorded run gives one row per frame. |
|---|
| Layer being decomposed | The whole RAM state. The VCS has no layers; RAM is the single place where game state lives between frames. |
|---|
| Feature (SAE hidden unit) | A learned direction over RAM bytes. We hope each one tracks one known game variable, e.g. ball x or the player score. |
|---|
| Human label for a feature | The verified concept↔cell map (candidates_<game>.json). For Pong: 8 cells, including scores, paddle and ball positions. |
|---|
| Feature steering / ablation | Zero the feature in the code, decode to bytes, write all 128 bytes into the real machine, replay 15 frames, count screen pixels that change. |
|---|
| Ground truth (never available for an LLM) | The intervention oracle: how much the screen breaks when each cell itself is set to 0 or base+17 and the ROM re-runs. |
|---|
How we apply it to the VCS
Our runner sae.jl is a complete SAE pipeline written by hand in Julia (no deep-learning
library), applied to the VCS state instead of a transformer.
- Data. We record the RAM after every frame along the shared gameplay stream (90 seeded
random-action frames plus the 15-frame horizon, continued with NOOP; 150 frames for Pong). Each byte is
z-scored (mean 0, standard deviation 1). Bytes that never change are set to zero. Every fifth frame is
held out for testing.
- Model and sweep. \(z=\mathrm{ReLU}(W_e x+b_e)\), \(\hat x = W_d z + b_d\), loss = mean
squared error + \(\lambda\cdot\)mean\(|z|\). Full-batch gradient descent, 4000 epochs, learning rate
0.5, with the gradients written out explicitly. We sweep the width \(\in\{16,32,64\}\) and
\(\lambda\in\{0.01,0.05,0.2\}\) and keep the model with the best held-out reconstruction. Note:
these widths are smaller than 128, so the SAE is not overcomplete in raw bytes. But most of the 128 bytes
are constant over a short run, so the number of bytes that actually vary is far smaller.
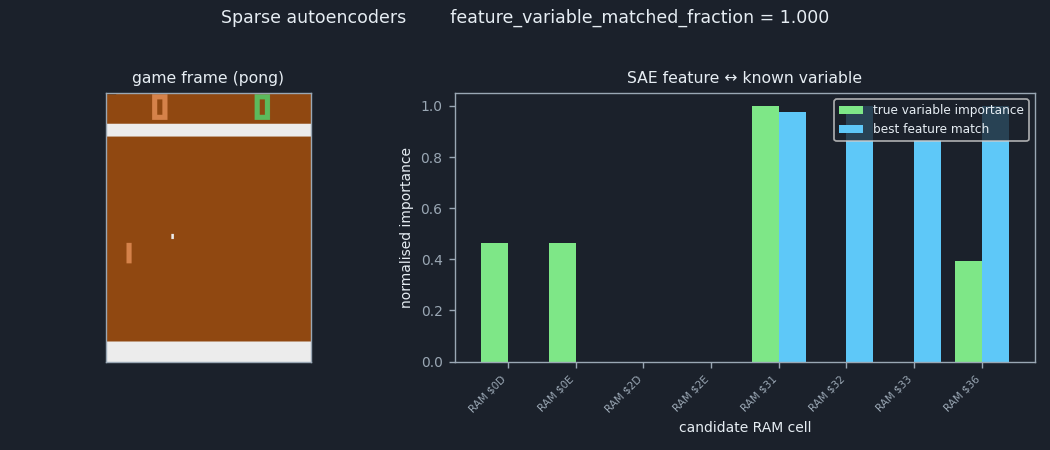
- Matching. For each known cell that varies, we find the feature whose activation has the
largest absolute Pearson correlation with the cell's value over the run. The cell is
“matched” if that correlation is at least 0.7. The match rate is the share of
varying known cells that get a match. This is the kind of evidence papers use to say “this feature
is concept X”.
- Causal use. This is the test a language model cannot give us. For each matched cell that the
oracle says is causal, we encode the RAM at \(f^*\), set its best feature to zero, decode, undo the
z-scoring, round to bytes, and write the full 128-byte vector into a copy of the machine. Then we play
the 15-frame tail. The effect is the number of screen pixels that differ from the same write
without the ablation, so reconstruction error cancels out. We also count decode leakage
(how many bytes of the ablated decode differ from the real RAM) and the share of the effect that the target cell alone
explains.
- Controls. One ablated write is replayed through an independent fresh boot and must match
the checkpoint path exactly. The oracle's own importance map, scored as if it were the method, must get
a perfect rank correlation.
The triad: F is the Spearman rank correlation between each cell's SAE “recovery
score” (best feature correlation × decoder weight mass on that cell) and the oracle's
importance. S predicts a held-out lesion (base+37) from the same score. M asks whether the
cells the SAE highlights are the cells that matter.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
sae.jl:375 — The model: encoder, decoder, L1 weight, random initialisation. - XAI
sae.jl:395 — The objective: mean squared reconstruction error + \(\lambda\cdot\)mean\(|z|\). - XAI
sae.jl:404 — Training: full-batch gradient descent with hand-written gradients through ReLU and L1. - XAI
sae.jl:472 — Naming features: best |Pearson r| between a feature and each known RAM cell, threshold 0.7. - XAI
sae.jl:612 — The causal test: zero a feature, decode, write all 128 bytes, replay, count changed pixels. - XAI
sae.jl:241 — Records the per-frame 128-byte RAM tape the SAE is trained on. - XAI
sae.jl:866 — One game: record, sweep width × \(\lambda\), match, oracle importance, causal use, triad. - substrate
jutari_oracle.jl:176 — Writes one byte into the emulated RIOT RAM; the decoded state is written with 128 of these. - substrate
StellaEnvironment.jl:350 — Exposes the live 128-byte RAM: the “activation vector” the SAE sees. - substrate
StellaEnvironment.jl:259 — One bit-exact video frame, used for recording and for every causal re-run.
Reading the result
Expect two very different pictures side by side. The reconstruction is close to perfect and the
match rate is high: almost every known cell has a feature that tracks it. By the usual standard of the
field, the SAE has “found the variables”. Then look at the causal-use bars. Ablating a
matched feature often moves the screen much less than the oracle says that cell matters, or moves it
through other bytes the decoder also touched. The lesson is the gap between named and
used: a feature can track a variable perfectly and still not be the handle by which the program's
computation runs.
Pitfalls
- Correlation is not mechanism. A feature that correlates with ball x may also correlate with a frame counter or the paddle. High correlation names a feature; it does not prove the model uses that direction.
- Decode leakage. Zeroing one feature changes the decoded value of many bytes at once. The observed effect then mixes several variables, which breaks the “one feature, one concept” story.
- Hyper-parameters shape the dictionary. Width and \(\lambda\) decide how features split or merge. A different sweep can give different “features” on the same data.
- Interpretable-looking is not evidence. Heap et al. found that standard automated interpretability scores for SAE features look similar on trained and randomly initialised transformers. On the VCS we score against the oracle instead.
- Small state, easy case. The VCS keeps variables in separate bytes, so there is little superposition to undo. A high match rate here is expected and says little about how SAEs fare on dense LLM activations.
Try it yourself
julia --project=jutari tools/xai_study/phaseC_mechanistic/sae.jl --games core
Writes sae_<game>.{json,npz} and sae_core_summary.json into tools/xai_study/phaseC_mechanistic/out/. The 9-point sweep dominates the run time; use --d-hidden-sweep 32 --l1-sweep 0.05 for a quick single model.
Original papers & further reading
Read next: NMF/PCA dictionaries · Linear probing + control tasks · Interchange interventions / DAS · A7 · Dimensionality reduction (NMF/PCA)