Phase C · mechanistic interpretability

Interchange interventions / DAS

Geiger et al. 2021, 2023

← back to the method catalogue

What it does?

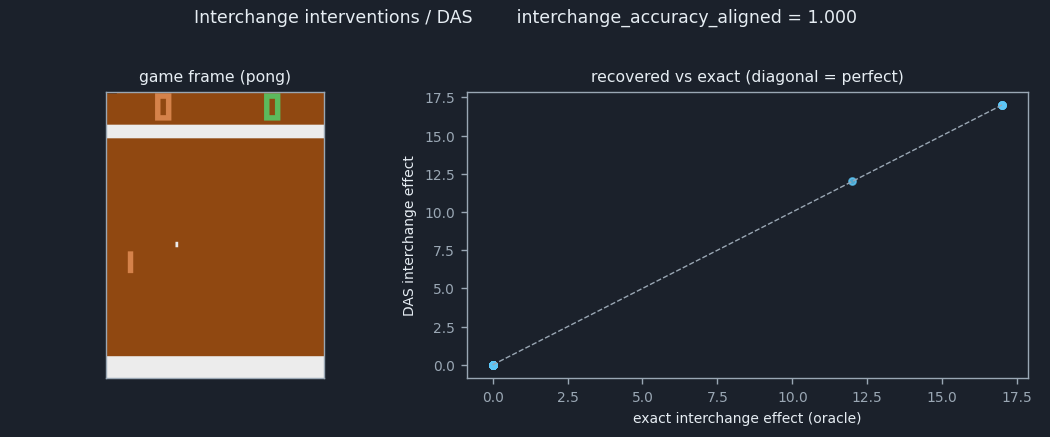
Distributed Alignment Search, or DAS, looks for a high-level concept inside the low-level state. It learns a rotation of the internal representation so that a chosen direction, or subspace, lines up with a supplied causal variable. It then tests the alignment by an interchange intervention: swap that subspace between two runs and check whether the output changes exactly as the concept would predict. The method is a leading tool for arguing that a network represents an abstract variable in a specific, possibly distributed, part of its activations. We apply it to the VCS by aligning a learned subspace of the state to a known game variable and measuring interchange accuracy against the true variable. On this transparent machine the alignment is exact: swapping the aligned subspace reproduces the concept's effect perfectly, while a mis-aligned control does not. There is an important caveat that the VCS makes explicit. The concept DAS aligns to is one we supplied from an external label, not one the method discovered. So a perfect interchange accuracy confirms an alignment to a given meaning; it does not show the method found the meaning on its own. DAS is thus a strong test of whether a supplied concept is causally real in the state, and a clean example of the difference between verifying a label and discovering one.

Interchange interventions / DAS result

Each point is one intervention site: its exact causal effect from the oracle (x) against the method's recovered/approximate effect (y). Points on the dashed diagonal mean the method recovered the true effect. interchange_accuracy_aligned = 1.000 — this example only (pong, state gameplay(seed=0,prefix=90)+15); the audit aggregate is below.

Mechanistic family · testing a hypothesis about a variable

Learn the method — a beginner's guide

New to explainable AI? This block explains the method as it is used on neural networks, then how we run the very same method on an Atari 2600, where — unlike for a network — we know the right answer. Every implementation step links to the code. See also the XAI primer for the shared vocabulary.

The idea in plain words

Suppose you believe a network solves a task with a simple algorithm. For example, to compare two numbers it first computes “which one is bigger” and then reports it. That simple algorithm is a high-level causal model: a few named variables and the arrows between them. The question is whether the network really contains a variable that plays the role of “which one is bigger”. Causal abstraction answers it with an interchange intervention: take the hidden state that should hold the variable from a source input, put it into the run on a base input, and check whether the output changes exactly as the high-level model predicts when you swap that variable.

The catch is that a network rarely stores a variable in one neuron. It may be spread across many neurons, along some direction of the activation space. That is a distributed representation. Distributed Alignment Search (DAS) therefore learns a rotation of the activation space. After rotating, the first few coordinates should hold the variable, and swapping only those coordinates should behave like swapping the variable. On the VCS we already know where every variable lives, so the method turns into a clean test of the swap logic itself, and a lesson about what a perfect score can and cannot prove.

How it works on a neural network

Let \(h(x) \in \mathbb{R}^d\) be the hidden vector at some layer for input \(x\). DAS learns an orthogonal matrix \(R\) (a rotation: \(R^\top R = I\), so no information is lost) and fixes a number \(k\) of coordinates. The interchange intervention on base \(b\) with source \(s\) is

\[ \hat h \;=\; R^\top\!\Big( (I - P_k)\,R\,h(b) \;+\; P_k\,R\,h(s) \Big), \]

where \(P_k\) keeps only the first \(k\) rotated coordinates. The rest of the network then runs on \(\hat h\). The high-level model predicts an output \(y^\ast(b, s)\): the answer you would get on \(b\) if its variable took \(s\)’s value. \(R\) is trained by gradient descent so the network’s output matches \(y^\ast\) on many \((b, s)\) pairs. The score is interchange intervention accuracy (IIA): the fraction of held-out pairs where the swapped run gives \(y^\ast\).

Toy example. Let \(h = (h_1, h_2)\) with \(h_1 = u + v\) and \(h_2 = u - v\), where the variable we care about is \(u\). No single neuron is \(u\). But rotate by 45°: \(R h = \tfrac{1}{\sqrt 2}(h_1 + h_2,\; h_1 - h_2) = \sqrt 2\,(u, v)\). Now the first rotated coordinate is exactly \(u\) (times a constant). Base \(u{=}1, v{=}3\); source \(u{=}5, v{=}0\). Swap coordinate 1: the patched state encodes \(u{=}5, v{=}3\), so \(h = (8, 2)\). That is precisely the prediction “base with source’s \(u\)”. Swapping neuron \(h_1\) alone would give \(h = (5, -2)\), which decodes to \(u{=}1.5, v{=}3.5\): the wrong \(u\) and a corrupted \(v\). This is why DAS looks for a direction, not a neuron.

Recipe

  1. Write down the high-level causal model and choose the variable \(V\) you want to locate.
  2. Choose a layer and a subspace size \(k\); initialise a rotation \(R\).
  3. Sample base/source pairs; compute the high-level prediction \(y^\ast(b,s)\) for swapping \(V\).
  4. Run the interchange intervention in the rotated basis and train \(R\) so the network output matches \(y^\ast\).
  5. Report IIA on held-out pairs, and compare it with a control (a random or wrong subspace).

From a neural network to the Atari

Hidden vector \(h\) at a layerThe VCS state at frame \(f^*\): 128 bytes of RAM plus TIA registers.
High-level variable \(V\)A named game variable from the candidate list (a position, a score digit, a timer), plus the background colour.
Learned rotation \(R\) and subspace \(P_k\)Not learned here. The aligned “subspace” is one axis-aligned byte: the program stores each variable in its own RAM cell.
Base / source inputsBase: the clean gameplay stream. Source: either a directed value (base+17) or a natural one (the same stream with RIGHT pressed before \(f^*\)).
IIAFraction of variables whose cell, after the swap, holds the source value the high-level model predicts.
Wrong-subspace controlSwap the next candidate cell instead and check variable \(V\): accuracy should collapse.

How we apply it to the VCS

The runner reads its variables from the game’s candidate file: each candidate RAM byte becomes a variable whose value is the byte itself, plus a background-colour variable read from a screen pixel. The claim being tested is that “variable \(V\) lives in byte \(i\)”. Everything runs on the shared gameplay checkpoint at \(f^*\), with a 15-frame tail.

  1. Interchange-effect matrix. For every cell \(i\), write the directed source value base+17 into a copy of the base checkpoint, run 15 frames, and read every variable \(j\). The same swap is replayed from a fresh boot; the two matrices must be identical.
  2. IIA of the true alignment. For each RAM variable, swap its own cell and read the cell back at the swap frame. It must hold the source value. This is done for the directed source and, where the natural RIGHT-press source really differs from base, for that too.
  3. Misaligned control. Swap the next candidate cell in the list and read variable \(V\). It matches the prediction only if the two cells happen to alias, so accuracy should drop to near zero. This is what makes a perfect aligned score meaningful.
  4. Alignment search. For each variable, the runner picks the cell whose swap best reproduces the variable’s own 15-frame effect, and checks whether that is the true cell. Cells the program overwrites within the horizon (transient cells) give no signal and are listed separately.

Be clear about the difference from real DAS. There is no learned rotation and no gradient training. The search space is the set of single bytes, because on the VCS the program’s variables are stored one per byte. The concept labels come from the candidate file, not from the method. So the VCS run checks that interchange logic and the IIA metric reward the right alignment and punish a wrong one; it does not show that DAS would discover the variable unaided.

Read the code

XAI the interpretability method   substrate the bit-exact emulator it runs on (jutari, Julia).

Reading the result

Expect the aligned IIA at the ceiling and the misaligned control near the floor. The gap between the two is the real content: it shows the metric discriminates. Then look at the alignment search and the transient list. Variables whose cell is rewritten every frame cannot be aligned by their downstream effect, because there is none within the horizon. A perfect score here verifies a given label; it is not evidence that the method found the label itself.

Pitfalls

Try it yourself

julia --project=jutari tools/xai_study/phaseC_mechanistic/das.jl --games core

Writes das_<game>.json/.npz and das_core_summary.json into tools/xai_study/phaseC_mechanistic/out/. One re-run (plus one fresh-boot replay) per candidate cell; minutes per game on one CPU core.

Original papers & further reading

Read next: Activation patching / causal mediation · Causal scrubbing · Linear probing + control tasks · Sparse autoencoders
How it's scored

The score is the interchange accuracy of the aligned subspace against the true variable. We align a learned subspace of the state to a supplied concept, then swap that subspace between two runs and check whether the output changes exactly as the concept predicts; the fraction of correct interchanges is the accuracy. The grading is against the intervention oracle, and on this transparent machine the alignment is exact, so interchange accuracy is at the ceiling, while a mis-aligned control scores zero. Faithfulness for this method is that interchange accuracy. There is no sprite-position hard-case here, because DAS operates by intervention rather than by a gradient. The essential caveat the audit makes explicit is that the concept DAS aligns to is one we supplied from an external label, not one the method discovered. So a perfect interchange accuracy is guaranteed in advance: it confirms an alignment to a given meaning, and does not show the method found the meaning on its own. The grading is always against the oracle, never against another method. The audit box reports the measured triad. DAS is thus a clean example of the difference between verifying a supplied concept and discovering one, which only a machine with known ground truth can separate.

The score is measured against the §1 intervention oracle — never against another interpretability method. F (faithful) is always vs the oracle; see the execution stack. How each of F / S / M is actually computed for this method (and whether it matches the paper) is in the box just below; the numbers are in the In the audit box under it.

How F, S, M are computed here

The exact formula this method uses for each score, read from its runner, and whether it matches the paper's §3 (F ∧ S ∧ M triad) definition. From the committed audit fsm_math_phaseC.json.

AxisFormula (as computed) What it measuresMatches §3?
F
faithfulness
\(F = \mathrm{interchange\ accuracy} = 1\)Interchange accuracy of the SUPPLIED alignment: for each aligned cell, does swapping its value reproduce the predicted high-level outcome; 1.0 by construction on the VCS.◐ partial das.jl (F = clamp(iia_aligned)); metric_name interchange_accuracy_aligned. It IS a causal check (each interchange is a real do(cell:=source) bit-exact re-run, so single-cell interchange == the exact patch oracle), but F verifies a SUPPLIED/known-true alignment reproduces the abstraction (Geiger IIA) rather than scoring a method-discovered claim's agreement against {Delta_y(u)} -> '1.0 by construction'. The genuine discovery signal (alignment_accuracy, whether DAS recovers the right cell) is a separate extra field, not F. Record: extra.triad.F=1.0 (battery mean F=1.0, n=42).
how it's measured — call stack:
  1. F = clamp(interchange accuracy) into the triad; each interchange is a do(cell:=source) re-run — das.jl:638
  2. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
S
sufficiency
\(S = \dfrac{\#\{\,u_{\mathrm{held}}:\ |\hat{y}-y|\le\varepsilon\,\}}{|\mathrm{held\text{-}out}|}\in[0,1]\)Shared held-out predictive sufficiency estimator over the interchange effects.✓ matches common/triad_sm.jl sufficiency_score via triad_extra_dict (das.jl, effect vs exact_effect). Paper-conform. Record: extra.triad.S=1.0 (battery mean S=1.0, n=42).
how it's measured — call stack:
  1. sufficiency_score: fit Δy=a·attr+b on a calib half, predict held-out within ε — triad_sm.jl:111
  2. assemble the triad via triad_extra_dict — das.jl:638
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
M
minimality
\(M = |U^{\star}| / |\hat{U}| \in (0,1]\quad U^{\star}=\{u:\Delta y(u)>0\},\ \hat{U}=\{u:|\mathrm{attr}(u)|>\tau\}\)True minimal cause set over method-named set.✓ matches common/triad_sm.jl minimality_score. Paper-conform. Record: extra.triad.M (pong |U*|=5/|U_hat|=5, M=1.0; battery mean M=0.890, n=42).
how it's measured — call stack:
  1. minimality_score: |U*| oracle movers / |U_hat| named cells — triad_sm.jl:57
  2. assemble the triad via triad_extra_dict — das.jl:638
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242

✓ matches = the same quantity as §3; ◐ partial = the same kind of estimator but a differing detail; ✗ does not match = a different quantity (see the note). Definitions: F = agreement with the oracle's true causal effects Δy(u); S = held-out predictive score in [−1, 1]; M = |U*|/|Û| (true-minimal-set size / named-set size).

In the audit

This is the method's entry in the actual cross-method audit — scored on the paper's correctness triad, each axis a mean over 44 of the 44 scored games (44 committed §R records), not the single example shown above. Tradition: causal. The example figure (Pong) is one of those records.

1.000F — faithfulness vs oracle (mean over 44 games, ±0.000 CI95)
1.000S — sufficiency: held-out predictive (n/a where the paper does not define this axis)
0.869M — minimality: true-minimal-set / named-set (n/a otherwise)
44committed records aggregated
0.00human-plausibility proxy

F faithfulness (scored vs the oracle for every method) · S sufficiency (held-out predictive score in [−1, 1]; a negative value means the explanation predicts held-out interventions worse than the unperturbed baseline; reported for the predictive methods across all three phases where the calibration/held-out split is defined) · M minimality (true-minimal-set / named-set; where the method names a cause set) — n/a otherwise, per the paper's F ∧ S ∧ M triad.

Source: leaderboard.json · the whole leaderboard is on the methods page and the Paper 2 audit.

Results per game

This method's faithfulness on each of the 44 scored games (all-regime F; this method has no content-vs-position split (see the note below)). Click a header to sort. Every number is read from site_data.json (methods.das.per_game).

content-F and position-F are n/a for this method. The content-vs-position split applies only to pixel-attribution methods — those that produce an attribution map over the framebuffer, whose score can be read separately on the smooth content outputs and the discrete position outputs (where the naive gradient is provably zero). This method does not attribute to a pixel output; it is graded by its own fidelity metric (interchange_accuracy_aligned), reported as the F column, so there is no content or position regime to separate.

GameF (all)content-Fposition-FSMNote
Air Raid1.000n/an/a1.0000.625recovers the true causes
Alien1.000n/an/a1.0000.857recovers the true causes
Assault1.000n/an/a1.0000.875recovers the true causes
Asterix1.000n/an/a1.0000.909recovers the true causes
Atlantis1.000n/an/a1.0000.889recovers the true causes
Bank Heist1.000n/an/a1.0001.000recovers the true causes
Berzerk1.000n/an/a1.0000.902recovers the true causes
Bowling1.000n/an/a1.0000.909recovers the true causes
Boxing1.000n/an/a1.0000.650recovers the true causes
Breakout1.000n/an/a1.0001.000recovers the true causes
Carnival1.000n/an/a1.0000.900recovers the true causes
Centipede1.000n/an/a1.0000.900recovers the true causes
Chopper Command1.000n/an/a1.0000.647recovers the true causes
Demon Attack1.000n/an/a1.0000.857recovers the true causes
Double Dunk1.000n/an/a1.0000.882recovers the true causes
Enduro1.000n/an/a1.0000.750recovers the true causes
Fishing Derby1.000n/an/a1.0001.000recovers the true causes
Freeway1.000n/an/a1.0001.000recovers the true causes
Frostbite1.000n/an/a1.0000.593recovers the true causes
Gopher1.000n/an/a1.0001.000recovers the true causes
Hero1.000n/an/a1.0000.833recovers the true causes
Ice Hockey1.000n/an/a1.0001.000recovers the true causes
Jamesbond1.000n/an/a1.0000.769recovers the true causes
Kangaroo1.000n/an/a1.0000.769recovers the true causes
Krull1.000n/an/a1.0000.929recovers the true causes
Kung-Fu Master1.000n/an/a1.0001.000recovers the true causes
Montezuma's Revenge1.000n/an/a1.0000.731recovers the true causes
Ms. Pac-Man1.000n/an/a1.0001.000recovers the true causes
Name This Game1.000n/an/a1.0001.000recovers the true causes
Pacman1.000n/an/a1.0001.000recovers the true causes
Phoenix1.000n/an/a1.0001.000recovers the true causes
Pitfall1.000n/an/a1.0000.923recovers the true causes
Pong1.000n/an/a1.0001.000recovers the true causes
Private Eye1.000n/an/a1.0000.917recovers the true causes
Q*bert1.000n/an/a1.0000.950recovers the true causes
Riverraid1.000n/an/a1.0000.774recovers the true causes
Road Runner1.000n/an/a1.0000.750recovers the true causes
Seaquest1.000n/an/a1.0000.970recovers the true causes
Skiing1.000n/an/a1.0000.727recovers the true causes
Space Invaders1.000n/an/a1.0000.867recovers the true causes
Tennis1.000n/an/a1.0000.708recovers the true causes
Venture1.000n/an/a1.0000.727recovers the true causes
Video Pinball1.000n/an/a1.0001.000recovers the true causes
Yars' Revenge1.000n/an/a1.0000.737recovers the true causes

Call stack — how it runs on jutari / jaxtari

The path from this method's runner (run_game) into the bit-exact VCS substrate, and the computation it involves. Every step links to the exact source on main. From callstack_phaseC.json.

Applied on the substrate

  1. Boot the real ROM with the xitari-parity reset (60 NOOP + 4 RESET) — env_reset!(env; boot_noop_steps = 60, boot_reset_steps = 4) jutari
  2. Deterministically step the emulator one action per env-frame — env_step!(env::StellaEnvironment, action::Integer) jutari
  3. Assemble the shared gameplay-state testbed (checkpoint at f*, causes, shared screen output, cause-density gate) — build_shared_testbed(game; ... intervene_ram = intervene_ram!, run_intervention = run_intervention, soft_ram_peek = soft_ram_peek, ...) runner
  4. Freeze byte-exact RAM + screen out of the env at a frame — snapshot(env::StellaEnvironment, frame::Integer) jutari

The computation

  1. Define the abstract variables (concept-labelled RAM cells) the DAS alignment maps onto — build_variables(cand_indices_concepts) runner
  2. Interchange intervention: write the source-run cell value(s) into a deepcopy of the base checkpoint, continue the tail, snapshot (the DAS interchange / resample re-run measuring alignment-cell effect on each variable readout) — interchange(base_ckpt, tail, kind, sites, values) -> intervene_ram!/intervene_tia!; env_step! runner intervene_ram! @ das.jl:256, intervene_tia! @ :258, env_step! @ :263

Scored against the exact intervention oracle Δy(u): run_intervention(checkpoint, actions, target_frame, horizon, cause).

Implementation
tools/xai_study/phaseC_mechanistic/das.jl
Reference
Geiger et al. 2021, 2023
Record
das_pong.json
All records
phaseC_mechanistic/out

The figure is generated from the committed record by docs/gen_method_figures.py; the game frame and each RAM cell's screen footprint are produced by render_scenes.jl / cell_footprints.jl.