Phase C · mechanistic interpretability

Linear probing + control tasks

Alain & Bengio 2017; Hewitt & Liang 2019

← back to the method catalogue

What it does?

Linear probing asks whether a concept can be read out of the state by a simple classifier. A linear probe is trained to predict a concept, say the ball's position, from the internal state; if it succeeds, the concept is said to be 'encoded' there. The well-known danger is that a probe can succeed just because the concept happens to be linearly recoverable, not because the system uses it. Hewitt and Liang's control-task fix addresses this: train a second probe to predict a random label, and report selectivity, the probe's real accuracy minus its accuracy on the random control. High selectivity means the state genuinely encodes the concept rather than the probe memorising it. We apply this on the VCS, training probes for game concepts and subtracting the control-task baseline. The VCS then adds a test no neural network allows: we check, by intervention, whether the program actually uses each decodable cell. It often does not. A cell can be decodable, and pass the control-task check, yet be provably unused when we clamp it and re-run, because the value is present in the state but never causally used within the window. Linear probing is thus our clearest illustration of the present-versus-used gap: decodability shows information is there, but only the intervention oracle shows whether the program relies on it.

Linear probing + control tasks result

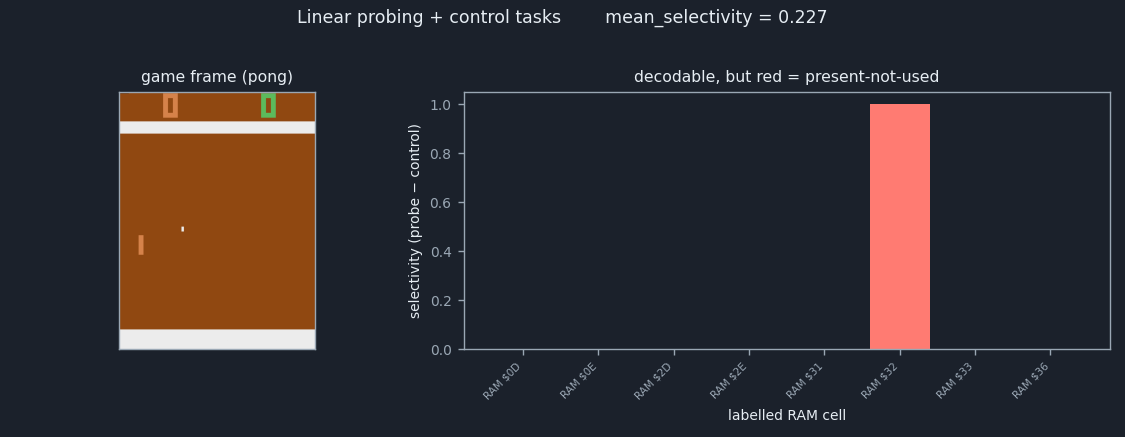
Per labelled RAM cell, the probe's selectivity (accuracy minus a control task). Red bars are cells that are decodable but not causally used — present ≠ used. probe_selectivity_vs_causal_use_correlation = -0.090 — this example only (pong, state gameplay(seed=0,prefix=90)+15, NOOP-continued to f600); the audit aggregate is below.

Mechanistic family · decoding what is represented

Learn the method — a beginner's guide

New to explainable AI? This block explains the method as it is used on neural networks, then how we run the very same method on an Atari 2600, where — unlike for a network — we know the right answer. Every implementation step links to the code. See also the XAI primer for the shared vocabulary.

The idea in plain words

Does a language model “know” the part of speech of each word? Does a chess network “know” where the king is? A probe is the simplest way to ask. You freeze the network, record its hidden activations, and train a tiny, separate classifier to predict the concept from them. If even a linear classifier succeeds, people say the concept is linearly represented at that layer. Probing is cheap, works on any layer, and has been run on almost every large model.

Two traps make the answer less clear than it looks. First, a probe that is too flexible can memorise labels instead of finding them. Hewitt and Liang's control task fixes that: give the same probe a nonsense labelling and see how well it does anyway. Second, and deeper: a probe tells you a concept is present, that is, readable from the activations. It does not tell you the network uses it. Information can sit in a layer as a by-product, read by no later computation. This page is built around that present-versus-used gap.

How it works on a neural network

Let \(h \in \mathbb{R}^d\) be the frozen activation for one input and \(c \in \{1,\dots,K\}\) the concept label. A linear probe predicts

\[ \hat c = \arg\max_k \,(W h + b)_k , \]

with \(W, b\) fit on labelled examples and accuracy measured on held-out ones. The control task keeps the inputs but replaces the labels: every distinct input type (in NLP, every word) gets a fixed random label. A probe can only score well on that by memorising. The honest number is the selectivity:

\[ \text{selectivity} = \text{acc}_{\text{real}} - \text{acc}_{\text{control}} . \]

Toy example (present but unused). A two-unit hidden layer gets an input number \(n\). Unit \(h_1 = n\) and unit \(h_2 = n \bmod 2\) (the parity). The output is \(y = 2h_1\); nothing ever reads \(h_2\). A probe on \(h_2\) predicts “is \(n\) odd?” with 100 % accuracy, and on a control task it scores only chance, so selectivity is high. A naive reading says “the network computes parity”. Yet setting \(h_2\) to any value leaves \(y\) unchanged: for \(n=3\), \(y=6\) whether \(h_2\) is 0 or 1. Decodable, selective, and causally irrelevant.

Recipe

  1. Record frozen activations and the concept label for many inputs; split into train and test.
  2. Fit a linear classifier (logistic or least-squares, usually regularised) and measure test accuracy.
  3. Build a control task: map each input type to a fixed random label of the same cardinality, and train the same probe on it.
  4. Report selectivity = real accuracy minus control accuracy, not raw accuracy.
  5. To ask whether the concept is used, intervene: remove or change it in the activations and check the output (e.g. amnesic probing).

From a neural network to the Atari

Hidden activation \(h\)The 128-byte RAM at one frame, minus the one byte being probed (127 inputs, z-scored, plus a bias).
The conceptA known game variable in its verified RAM cell, e.g. ball x in RAM[49] for Pong.
Class label \(c\)The cell's value split into up to 4 equal-width bins over the range seen in the run.
Control taskEach distinct raw byte value of the cell gets a fixed random label among the same number of classes.
“Is it used?” (rarely testable)The oracle's flag: cells whose intervention is overwritten by the program within the horizon, so it never reaches the output.

How we apply it to the VCS

Our runner linear_probing.jl needs labels, because it decodes named concepts. Per game it does this:

The headline is mean selectivity over all probeable cells, next to the count of decodable-but-not-causal cells. Note the dependency: if the DAS output is missing, the “used” cross-check is marked as unavailable rather than guessed.

Read the code

XAI the interpretability method   substrate the bit-exact emulator it runs on (jutari, Julia).

Reading the result

Each bar is one labelled cell: its selectivity (probe accuracy minus control accuracy); red bars are cells the oracle flags as not causally used. Expect most game variables to be decodable above the control. The VCS state is small and full of copies and derived values, so the rest of RAM often predicts a variable well. Then look for the red cells that are still decodable: present but not used. They are the key result: a probe would “find” these concepts, a naive reading would say the program relies on them, and the intervention shows that, within the window, it does not.

Pitfalls

Try it yourself

julia --project=jutari tools/xai_study/phaseC_mechanistic/linear_probing.jl --games core

Writes linear_probing_<game>.{json,npz} and linear_probing_core_summary.json into tools/xai_study/phaseC_mechanistic/out/. Run das.jl first so the present-vs-used cross-check has the oracle's transient-cell list.

Original papers & further reading

Read next: Logit / tuned lens · Interchange interventions / DAS · Sparse autoencoders · A3 · Tuning curves
How it's scored

The score is the mean selectivity: the probe's accuracy minus the accuracy of a control-task probe trained on a random label, averaged over the labelled cells. The control task follows Hewitt and Liang and guards against a probe succeeding merely because a concept is linearly recoverable. The grading is always against the intervention oracle. Faithfulness for this method is that selectivity, and it is modest, but the deeper finding comes from crossing the probe against the oracle. Concepts are decodable above the control, so the information is present in the state, yet the oracle flags cells that are decodable but never causally used within the window. That is the present-versus-used gap: a value can be read out without the program relying on it. There is no sprite-position hard-case here; the output is a decodability judgement. The grading is always against the oracle, which is strictly stronger than the probe, because the probe asks whether a value can be read while the oracle asks whether changing it changes the output. The audit box reports the measured triad. Linear probing earns a high plausibility proxy on a low faithfulness, which places it in the danger zone and makes it the clearest illustration of decodable-but-unused information.

The score is measured against the §1 intervention oracle — never against another interpretability method. F (faithful) is always vs the oracle; see the execution stack. How each of F / S / M is actually computed for this method (and whether it matches the paper) is in the box just below; the numbers are in the In the audit box under it.

How F, S, M are computed here

The exact formula this method uses for each score, read from its runner, and whether it matches the paper's §3 (F ∧ S ∧ M triad) definition. From the committed audit fsm_math_phaseC.json.

AxisFormula (as computed) What it measuresMatches §3?
F
faithfulness
\(F = \rho_{\mathrm{pb}}\!\left(\mathrm{attr}_{\mathrm{sel}},\ \mathbb{1}[\text{causally used}]\right)\)Point-biserial correlation between per-cell probe selectivity and the oracle causally-used indicator: does selectivity track causal use (not mere presence)?✓ matches linear_probing.jl now emits top-level metric_name=probe_selectivity_vs_causal_use_correlation with extra.triad.F = point-biserial rho(selectivity, oracle causally-used indicator); it replaced the mean control-task selectivity (a decodability/presence stat). This is §3's correlation between the attribution and the true causal effect. Record: linear_probing_pong.json extra.triad.F=-0.090 (present-but-unused => low/negative).
how it's measured — call stack:
  1. record: metric = probe selectivity vs causal-use correlation — linear_probing.jl:594
  2. F_note: point-biserial ρ(selectivity, oracle causally-used indicator) — linear_probing.jl:626
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
S
sufficiency
S = null (undefined)Not scored: a probe reads presence, not causal use; it emits no held-out do(u) output prediction.— n/a linear_probing.jl (S = nothing). Deliberately n/a per paper (present != used, Hewitt & Liang 2019). Record: extra.triad.S = null.
M
minimality
\(M = |U^{\star}| / |\hat{U}| \in (0,1]\quad U^{\star}=\{u:\Delta y(u)>0\},\ \hat{U}=\{u:|\mathrm{attr}(u)|>\tau\}\)Oracle causally-used cells over the number of cells the probe names by selectivity.✓ matches linear_probing.jl now emits M = |U*|/|U_hat| in extra.triad.M (M_note '|U*|=3 (oracle movers) / |U_hat|=5 (method above-threshold)'), the paper's set-size ratio. Record: linear_probing_pong.json extra.triad.M=0.6.
how it's measured — call stack:
  1. minimality_score(selectivity, oracle causal-use) when the xref is available — linear_probing.jl:622
  2. minimality_score: |U*| causally-used cells / |U_hat| probe-named cells — triad_sm.jl:57
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242

✓ matches = the same quantity as §3; ◐ partial = the same kind of estimator but a differing detail; ✗ does not match = a different quantity (see the note). Definitions: F = agreement with the oracle's true causal effects Δy(u); S = held-out predictive score in [−1, 1]; M = |U*|/|Û| (true-minimal-set size / named-set size).

In the audit

This is the method's entry in the actual cross-method audit — scored on the paper's correctness triad, each axis a mean over 44 of the 44 scored games (44 committed §R records), not the single example shown above. Tradition: probing. The example figure (Pong) is one of those records.

0.211F — faithfulness vs oracle (mean over 44 games, ±0.083 CI95)
n/aS — sufficiency: held-out predictive (n/a where the paper does not define this axis)
0.944M — minimality: true-minimal-set / named-set (n/a otherwise)
44committed records aggregated
0.00human-plausibility proxy

F faithfulness (scored vs the oracle for every method) · S sufficiency (held-out predictive score in [−1, 1]; a negative value means the explanation predicts held-out interventions worse than the unperturbed baseline; reported for the predictive methods across all three phases where the calibration/held-out split is defined) · M minimality (true-minimal-set / named-set; where the method names a cause set) — n/a otherwise, per the paper's F ∧ S ∧ M triad.

Source: leaderboard.json · the whole leaderboard is on the methods page and the Paper 2 audit.

Results per game

This method's faithfulness on each of the 26 scored games (all-regime F; this method has no content-vs-position split (see the note below)). Click a header to sort. Every number is read from site_data.json (methods.linear_probing.per_game).

content-F and position-F are n/a for this method. The content-vs-position split applies only to pixel-attribution methods — those that produce an attribution map over the framebuffer, whose score can be read separately on the smooth content outputs and the discrete position outputs (where the naive gradient is provably zero). This method does not attribute to a pixel output; it is graded by its own fidelity metric (probe_selectivity_vs_causal_use_correlation), reported as the F column, so there is no content or position regime to separate.

M is n/a on 1 of these games. Minimality is M = |U*|/|Û|, the size of the true minimal cause set over the size of the set the method actually names. On a game where the method names nothing (|Û| = 0 — it discovers no circuit, its attribution map is all-zero, or it decodes no cell), that ratio is undefined, so M is left blank rather than scored. The aggregate M is the mean over the 25 games where the method did name a cause set.

GameF (all)content-Fposition-FSMNote
Q*bert1.000n/an/an/an/arecovers the true causes
Carnival0.419n/an/an/a1.000
Ms. Pac-Man0.410n/an/an/a1.000
Jamesbond0.362n/an/an/a0.800
Breakout0.354n/an/an/a1.000
Centipede0.341n/an/an/a1.000
Montezuma's Revenge0.336n/an/an/a1.000
Kangaroo0.328n/an/an/a1.000
Assault0.288n/an/an/a1.000
Road Runner0.288n/an/an/a1.000
Frostbite0.275n/an/an/a1.000
Pitfall0.184n/an/an/a1.000
Space Invaders0.145n/an/an/a0.500
Fishing Derby0.143n/an/an/a0.667
Demon Attack0.123n/an/an/a1.000
Riverraid0.118n/an/an/a1.000
Phoenix0.116n/an/an/a1.000
Private Eye0.088n/an/an/a1.000
Yars' Revenge0.072n/an/an/a1.000
Chopper Command0.064n/an/an/a0.571
Berzerk0.043n/an/an/a1.000no true-cause signal
Atlantis0.000n/an/an/a1.000no true-cause signal
Boxing0.000n/an/an/a0.625no true-cause signal
Ice Hockey0.000n/an/an/a1.000no true-cause signal
Pong0.000n/an/an/a0.600no true-cause signal
Tennis0.000n/an/an/a1.000no true-cause signal

Call stack — how it runs on jutari / jaxtari

The path from this method's runner (run_game) into the bit-exact VCS substrate, and the computation it involves. Every step links to the exact source on main. From callstack_phaseC.json.

Applied on the substrate

  1. Boot the real ROM with the xitari-parity reset (60 NOOP + 4 RESET) — env_reset!(env; boot_noop_steps = 60, boot_reset_steps = 4) jutari
  2. Deterministically step the emulator one action per env-frame (drives the RAM-tape recording) — env_step!(env::StellaEnvironment, action::Integer) jutari
  3. Assemble the shared gameplay-state testbed via build_linear_probing_shared_state — build_shared_testbed(game; ... intervene_ram = J.intervene_ram!, run_intervention = O.run_intervention, soft_ram_peek = soft_ram_peek, ...) runner
  4. Freeze byte-exact RAM + screen out of the env at a frame — snapshot(env::StellaEnvironment, frame::Integer) jutari

The computation

  1. Record the per-frame RAM tape (128-byte activations) the probes are trained on — record_ram_tape(game, actions) -> env_step! runner
  2. Train a linear (ridge) probe per RAM cell + control-task selectivity: probe accuracy on the real label vs a random control label — probe_accuracy(Xtr, ytr, Xte, yte, nclass; lambda = RIDGE_LAMBDA) runner
  3. Cross-reference each probed cell with the oracle causal flag (transient/causal cells) so selectivity is scored against real causal use — oracle_transient_cells(game::AbstractString) runner

Scored against the exact intervention oracle Δy(u): run_intervention(checkpoint, actions, target_frame, horizon, cause).

Implementation
tools/xai_study/phaseC_mechanistic/linear_probing.jl
Reference
Alain & Bengio 2017; Hewitt & Liang 2019
Record
linear_probing_pong.json
All records
phaseC_mechanistic/out

The figure is generated from the committed record by docs/gen_method_figures.py; the game frame and each RAM cell's screen footprint are produced by render_scenes.jl / cell_footprints.jl.