Mechanistic family · reading intermediate states
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
A transformer language model is a stack of layers. Each layer reads a shared vector, the
residual stream, and adds its contribution back to it. Only at the very end does an
unembedding matrix turn that vector into one score per word in the vocabulary. Those scores are
the logits; a softmax turns them into probabilities for the next word.
The logit lens asks a cheeky question: what if we applied that final unembedding to the
residual stream halfway up the stack, as if the model stopped there? Because every layer writes
into the same stream, this often gives sensible words. You can watch the prediction form layer by layer:
vague at first, then sharpening into the final answer. The tuned lens improves on it. It learns a
small linear correction for each layer, so that earlier layers, whose “language” drifts a
little from the last layer's, are translated before decoding. Both are cheap, popular ways to trace how
information develops through depth.
How it works on a neural network
Let \(h_\ell\) be the residual stream after layer \(\ell\), \(W_U\) the unembedding and
\(\mathrm{LN}\) the final layer normalisation. Then
\[ \text{logits}_L = W_U\,\mathrm{LN}(h_L), \qquad
\text{logit lens: } W_U\,\mathrm{LN}(h_\ell), \qquad
\text{tuned lens: } W_U\,\mathrm{LN}(A_\ell h_\ell + b_\ell). \]
The tuned-lens translator \((A_\ell, b_\ell)\) is trained so its output distribution matches the
model's final one (by minimising a KL divergence). No new information is created: the lens only reads
what is already linearly there.
Toy example. A vocabulary of two words, “Paris” and “Rome”, and
\(W_U = I\) (identity). The residual stream after layers 1, 2 and 3 is \((0.2, 0.1)\),
\((1.5, 0.3)\) and \((3.0, 0.2)\). The softmax probability of “Paris” is
\(1/(1+e^{-(z_1-z_2)})\): 0.52 after layer 1, 0.77 after layer 2, 0.94 after layer 3. The logit lens
shows the answer “Paris” forming gradually. If layer 1 stored the answer in a rotated
basis, the raw lens would read nonsense there, and a learned \(A_1\) would undo the rotation: that is the
tuned lens.
Recipe
- Run the model and save the residual stream \(h_\ell\) at every layer.
- Logit lens: apply the final norm and unembedding to each \(h_\ell\) and read the decoded prediction.
- Tuned lens: for each layer, fit an affine map \(A_\ell h_\ell + b_\ell\) on training data so the decoded output matches the final output.
- Evaluate on held-out data: how well does each layer's readout match the final answer, and from which layer on?
- Check what the readout relies on: are its weights on components that actually drive the output?
From a neural network to the Atari
| Layers \(\ell\) | The frames of the 15-frame horizon after \(f^*\): step 0 (the checkpoint) to step 15. |
|---|
| Residual stream \(h_\ell\) | The full 128-byte RAM at that step. RAM is the one state every frame reads and writes, like the residual stream. |
|---|
| Final logit | The value of a target variable's RAM cell at the end of the horizon (one per candidate cell; 8 for Pong). |
|---|
| Unembedding \(W_U\) (logit lens) | The identity readout: read the target's own cell at step \(t\). There is no learned matrix on the VCS. |
|---|
| Tuned-lens translator \(A_\ell, b_\ell\) | A ridge-regression readout from all 128 bytes at step \(t\) to the final value. |
|---|
| True intermediate value (unknown in an LLM) | The actual byte at that step on the bit-exact run, plus the oracle's mask of which cells causally drive each final value. |
|---|
How we apply it to the VCS
Our runner logit_lens.jl builds both lenses on the VCS and scores them against values
we can measure directly.
- A set of runs to fit on. A lens needs many examples. From the shared gameplay checkpoint at
\(f^*\) we record 48 runs of 16 steps each: the clean run, a source run whose last prefix action is
RIGHT, and 46 runs that each start with one candidate cell shifted by 17, 34, 64, 128 or 200. Every run is
a genuine bit-exact replay of the ROM, so every row is a real machine state.
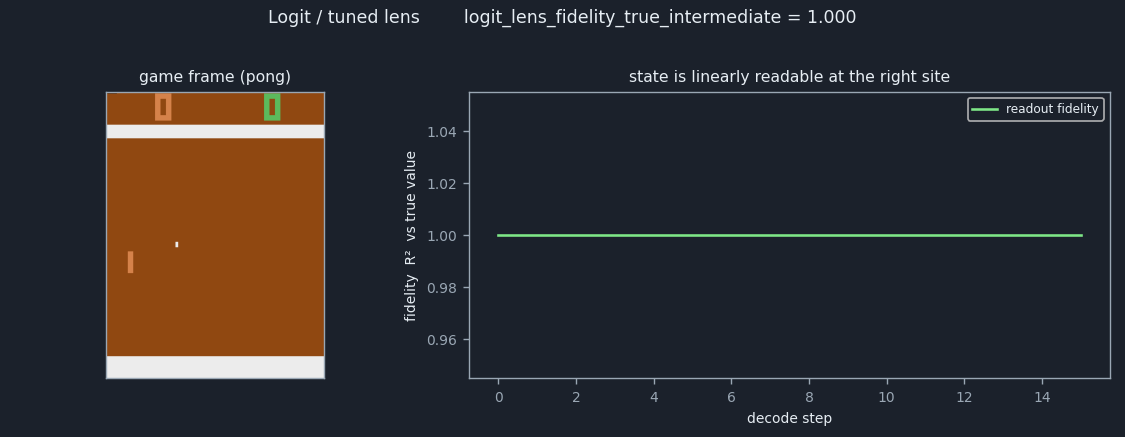
- Logit lens. For each target variable and step \(t\), read its own cell. Against the true
intermediate value this has fidelity (\(R^2\)) of exactly 1, because the readout is the cell. It
is a positive control that the readout site is right, not a discovery. Against the
final value it shows how early the cell already holds its end-of-horizon value.
- Tuned lens. For each variable and step, fit a ridge regression (\(\lambda = 10^{-3}\)) from
all 128 bytes to the final value on 70 % of the runs, and score \(R^2\) on the other 30 %.
The earliest step with \(R^2 \ge 0.9\) is when the answer is “already there”.
- Faithful or spurious? The oracle sets each candidate cell to its value + 17 at \(f^*\),
replays, and marks which final values change. At the tuned lens's earliest decoding step we measure what
share of its weight magnitude sits on those truly causal cells. A high share means the lens reads the
mechanism. A low share means it found a correlate, for example a counter that happens to predict the
answer.
Where we differ from the original. A transformer has one shared unembedding; on the VCS each
variable lives in its own address, so the “unembedding” is just “look at that
address”. Our layers are time steps, not stacked modules. And the training runs are mostly
deliberate pokes, not a natural data distribution. Readout fidelity reaching the ceiling is
therefore expected: the machine keeps its variables in plain, addressable memory. The more
informative numbers are the tuned-lens curves and the faithful-weight share, which is the record's
scored faithfulness.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
logit_lens.jl:258 — Builds the 48 real runs (clean, source, and single-cell pokes) the lenses are fit on. - XAI
logit_lens.jl:213 — Records the “residual stream over layers”: the RAM at steps 0 to 15. - XAI
logit_lens.jl:290 — The tuned-lens translator: a closed-form ridge regression per variable and step. - XAI
logit_lens.jl:300 — Readout fidelity: the coefficient of determination \(R^2\). - XAI
logit_lens.jl:371 — The oracle mask: which cells, poked by +17, change each variable's final value. - XAI
logit_lens.jl:455 — Per variable and step: logit lens, tuned lens, earliest decoding step, faithful-weight share. - substrate
shared_testbed_impl.jl:115 — The shared gameplay checkpoint at \(f^*\) and the 15-frame action tail. - substrate
jutari_oracle.jl:176 — The single-byte RAM write behind every poked run and the causal mask. - substrate
StellaEnvironment.jl:259 — One bit-exact frame: one “layer” of the VCS lens. - substrate
StellaEnvironment.jl:350 — The 128-byte RAM read at each step: the residual-stream analogue.
Reading the result
The figure plots readout fidelity against the true intermediate value, step by step, and it sits at
the ceiling on every game. Read that as a sanity check: the variable is stored at the site we read, in plain form.
The richer story is in the per-step curves. The logit lens reaches the final value only once the cell
stops changing. The tuned lens can sometimes predict it earlier by combining other bytes. Then check the
faithful-weight share: an early prediction built on causal cells is the mechanism showing through; one
built on non-causal cells is a correlation, the same present-versus-used trap as in probing.
Pitfalls
- Readable is not explained. Reading the right value at the right place confirms it is represented. It says nothing about how it is computed or what role it plays later.
- Representation drift. In a transformer, early layers may use a different basis than the last one, so the raw logit lens reads nonsense there. That is why Belrose et al. propose the tuned lens.
- A tuned lens can learn too much. A flexible translator fit per layer can find correlates that the model never uses. Check which inputs carry its weight, as we do with the oracle mask.
- Off-distribution fitting. Our training runs are mostly deliberate single-cell pokes. Readouts fit on them may not transfer to ordinary gameplay states.
Try it yourself
julia --project=jutari tools/xai_study/phaseC_mechanistic/logit_lens.jl --games core
Writes logit_lens_<game>.{json,npz} and logit_lens_core_summary.json into tools/xai_study/phaseC_mechanistic/out/. --n-traj K changes the number of runs the lenses are fit on (default 48).
Original papers & further reading
Read next: Linear probing + control tasks · Activation patching / causal mediation · Interchange interventions / DAS · A8 · Whole-state recording