Mechanistic family · classical dictionary learning
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
Suppose you record a network's activations for thousands of inputs and stack them into one big
table: one row per input, one column per neuron. A dictionary is a short list of
“building-block” patterns, called atoms or components, such that every row can
be written as a weighted sum of a few atoms. If the atoms line up with real concepts, you have found the
concepts without any labels. This is dictionary learning, and it is much older than deep
learning: neuroscientists used it in the 1990s to explain how the visual cortex codes images.
Two classical recipes are fast and need no training loop. PCA (principal component analysis)
finds the directions along which the data varies most; they are orthogonal and may have negative
entries. NMF (non-negative matrix factorisation) only allows non-negative atoms and weights, so
everything is built by adding parts, never by cancelling them. That often gives “parts”
a human can recognise. The sparse autoencoder is the modern, learned, sparse member of the same family.
Running the classical ones first shows how much the extra machinery buys.
How it works on a neural network
Put the data in a matrix \(X\) with \(T\) rows (samples) and \(n\) columns (neurons). Both methods
approximate it by a product of a thin matrix of activations \(A\) (\(T\times r\)) and a short
matrix of atoms \(H\) (\(r\times n\)), with \(r \ll n\):
\[ X \;\approx\; \mu + A H \quad(\text{PCA, } H H^\top = I), \qquad
X \;\approx\; A H \quad(\text{NMF, } A \ge 0,\ H \ge 0). \]
PCA takes \(\mu\) = the column means and \(H\) = the top \(r\) right singular vectors of the centred
data. NMF minimises \(\|X - AH\|^2\) with the Lee–Seung multiplicative updates, which keep every
entry non-negative. An SAE is the same picture with a learned, non-linear, sparse encoder for \(A\).
Toy example. Three RAM-like cells \((a, b, c)\). Cells \(a, b\) move together (a ball's x and
a copy of it); cell \(c\) is a score. Four frames: \((4,2,0)\), \((2,1,0)\), \((0,0,5)\),
\((4,2,5)\). NMF with \(r=2\) finds the exact answer \(H_1=(2,1,0)\) (“ball”),
\(H_2=(0,0,1)\) (“score”), with weights \((2,0), (1,0), (0,5), (2,5)\). Each atom is one
variable. PCA on the same data gives a first component of roughly \(0.92\cdot\)score \(-\,0.38\cdot\)ball:
both variables vary a lot, so the direction of largest variance mixes them, with a sign. Same data,
same rank; only the constraint differs.
Recipe
- Record many activation vectors and stack them into a samples × units matrix.
- Choose the number of atoms \(r\) (try several).
- Fit PCA (singular value decomposition of the centred matrix) and NMF (multiplicative updates on the raw, non-negative matrix).
- Inspect each atom's loadings: which units does it weigh, and do they belong to one concept?
- Count the share of atoms that match a known concept (the matched fraction).
- Test causally: remove one atom from the reconstruction, put the state back into the model, and measure the change in output.
From a neural network to the Atari
| Activation table \(X\) | The RAM tape: one row per video frame, 128 columns (one per RAM byte). |
|---|
| Atom / component | A pattern over the 128 bytes. A clean atom loads on the bytes of one game variable. |
|---|
| Concept label | The verified concept↔cell map (for Pong: scores, paddle and ball positions), grouped into families such as “ball” or “score”. |
|---|
| Structural signals (no network analogue) | Known machine-level signals: the frame clock, how many bytes change per frame, and a fitted periodic phase. |
|---|
| Removing an atom | Zero its weight, rebuild the 128 bytes, round them, write them into the real machine, replay 15 frames. |
|---|
| Ground truth | The bit-exact re-run itself: an atom is causally used only if removing it changes the screen. |
|---|
How we apply it to the VCS
Our runner dictionaries.jl applies PCA, NMF and a small sparse autoencoder to the
same RAM tape and scores all three with the same tests. That makes it a fair three-way
comparison.
- Data. The RAM after each frame along the shared gameplay stream (90 seeded random-action
frames, the 15-frame horizon, then NOOP; 150 frames for Pong). PCA uses the centred bytes. NMF uses the
raw bytes, which are naturally non-negative (0–255). The SAE uses z-scored bytes.
- Models. PCA is one singular value decomposition. NMF runs 300 Lee–Seung updates. The
SAE has as many hidden units as the rank, L1 weight 0.05, and 3000 epochs of gradient descent. All three
are run at ranks 8, 4 and 12; rank 8 is the headline.
- Matching. An atom counts as matched to a game variable if at least a quarter of its squared
loading mass sits on candidate cells and at least half of that mass sits on one concept family.
Otherwise it can still be matched to a structural signal if its activation over time correlates with the
frame clock, the per-frame change count, or the periodic phase at \(|r|\ge 0.5\). The matched
fraction is matched atoms over all atoms.
- Causal use. The RAM at \(f^*\) is projected onto the dictionary. For each atom we zero its
weight, decode, round and clamp to bytes, write all 128 bytes into a copy of the machine, and play the
15-frame tail. The effect is the number of screen pixels that differ from the same write without
the ablation, so the lossy reconstruction does not count as an effect. The same ablation is also played
under a different, held-out action tail.
- Positive control. Zeroing all atoms must break the screen. Otherwise the causal test
would be blind.
The triad: F is the Spearman correlation between how strongly each atom matches a variable
and its causal effect (“are the named atoms the used ones?”). S correlates the effect
with the held-out-tail effect. M is one minus the share of matched atoms whose removal does
nothing: naming a causally dead atom is an over-claim.
Why NMF tends to win on the VCS: RAM is literally a list of separate bytes that the program adds to
and overwrites. That is an additive, non-negative “parts” structure, which is what NMF
assumes. PCA's orthogonality has no reason to hold, so its components blend variables that happen to vary
together.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
dictionaries.jl:409 — PCA: SVD of the centred RAM tape; rows of \(V^\top\) are the atoms. - XAI
dictionaries.jl:430 — NMF: Lee–Seung multiplicative updates that keep both factors non-negative. - XAI
dictionaries.jl:487 — The small L1 sparse autoencoder used as the third, learned dictionary. - XAI
dictionaries.jl:599 — Matched fraction: loading purity on one concept family, or correlation with a structural signal. - XAI
dictionaries.jl:680 — Ablate one atom, decode, write the state, replay, count pixels against the reconstruction control. - XAI
dictionaries.jl:671 — Writes a full 128-byte state into a copy of the machine and replays the tail. - XAI
dictionaries.jl:842 — One game: record the tape, then PCA / NMF / SAE at each rank, matching, causal use, triad. - substrate
jutari_oracle.jl:176 — The single-byte write into emulated RIOT RAM that the decoded state is built from. - substrate
StellaEnvironment.jl:220 — Boots the cartridge with the xitari-parity reset before any recording. - substrate
StellaEnvironment.jl:259 — One bit-exact video frame: the step behind every recorded row and every re-run.
Reading the result
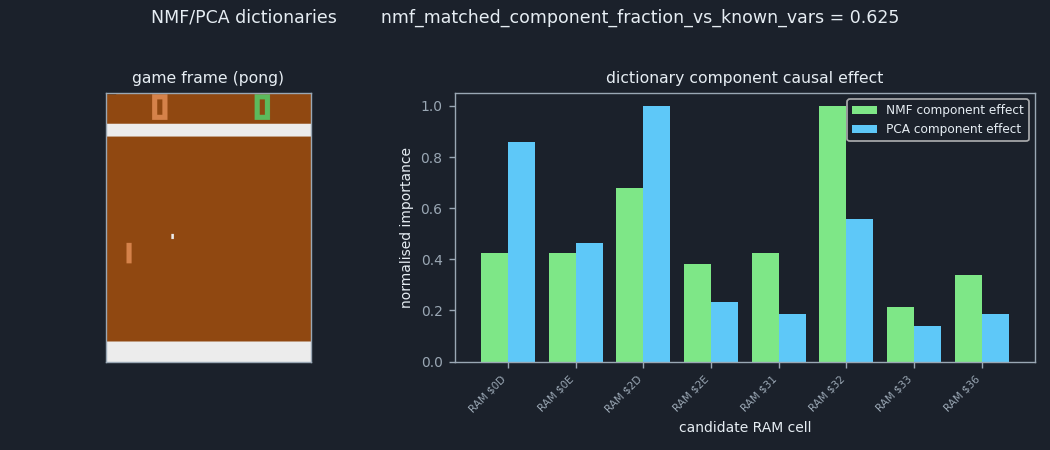
The figure compares the matched fraction of PCA, NMF and the SAE. Expect a partial result: NMF
recovers more cleanly named atoms than PCA, because its atoms are additive parts, while PCA folds
several variables into one signed direction. Then look at causal use. Several matched atoms do little
or nothing when removed, while some unmatched ones matter. So a good matched fraction is evidence that a
variable is present in the data, not that the program uses that atom. This is the same
gap the SAE page shows.
Pitfalls
- Variance is not importance. PCA ranks directions by how much they vary. A busy frame counter can dominate the first component while a rarely changing but crucial byte is buried.
- The rank is a choice. Too few atoms merge variables; too many split one variable over several atoms. We sweep ranks 4, 8 and 12 for this reason.
- Unsupervised factors are not unique. Locatello et al. proved that, without extra assumptions, many different factorisations explain the data equally well. A matching atom may be luck of the initialisation.
- Rounding to bytes. On the VCS a decoded state must be rounded to integers before it can be written. Small atoms can vanish in the rounding, which reads as “no causal effect”.
Try it yourself
julia --project=jutari tools/xai_study/phaseC_mechanistic/dictionaries.jl --games core
Writes dictionaries_<game>.{json,npz} and dictionaries_core_summary.json into tools/xai_study/phaseC_mechanistic/out/. Use --rank 8 for the headline rank only.
Original papers & further reading
- Lee & Seung (1999). Learning the parts of objects by non-negative matrix factorization. Nature 401. — doi.org/10.1038/44565
- Olshausen & Field (1996). Emergence of simple-cell receptive field properties by learning a sparse code for natural images. Nature 381. — doi.org/10.1038/381607a0
- Locatello et al. (2019). Challenging Common Assumptions in the Unsupervised Learning of Disentangled Representations. ICML. (critique: unsupervised factors are not identifiable without extra assumptions) — arxiv.org/abs/1811.12359
Read next: Sparse autoencoders · A7 · Dimensionality reduction (NMF/PCA) · Linear probing + control tasks · Interchange interventions / DAS