Neuroscience battery · latent factors of population activity
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
Modern recordings are huge: hundreds of neurons, or thousands of hidden units, over thousands of
time steps. Nobody can stare at that table. Dimensionality reduction compresses it. It looks
for a few components: patterns of joint activity that, added together, rebuild most of the
table. Each component has a loading (how strongly each unit takes part) and an
activation over time (how strongly the pattern is “on” at each step). The hope is that
these few latent factors are the system's real internal variables: “arm direction”,
“choice”, “ball position”.
Two classic tools are used. PCA (principal component analysis) finds the directions along which the
data vary most. NMF (non-negative matrix factorisation) instead rebuilds the data as a sum of
non-negative “parts”, which often look more like separate objects. Both are
unsupervised: they need no labels. That is their charm and their risk. They find what is
large in the data, and large is not the same as important. On the Atari we can check
which components match real signals, and whether the bytes they highlight are the ones that
actually cause what appears on screen.
How it works on a neural network
Neuroscience origin. PCA, factor analysis and NMF are staples of population analysis
(Cunningham & Yu 2014): reduce a recording to a few latent trajectories, then interpret them. Jonas
& Kording ran NMF on the transistor activity of a simulated 6502 and found components that tracked the
clock and bus activity, not the program's logic.
Deep-learning analogue. Dimensionality reduction of activations: PCA of a layer's
activations over a dataset, NMF of CNN feature maps into “concept” parts, or the top
singular directions of a residual stream. Arrange the recording as a matrix \(X\) of size \(T\times n\)
(time steps × units).
PCA centres each column (subtracts its mean, giving \(X_c\)) and takes the singular value
decomposition \(X_c = U S V^\top\). Column \(j\) of \(V\) is component \(j\)'s loading over the \(n\)
units; \(X_c V\) gives the activations; the share of variance explained is \(s_j^2/\sum_k s_k^2\).
NMF requires \(X\ge 0\) and finds \(W\ge 0\) (\(T\times r\), activations) and \(H\ge 0\)
(\(r\times n\), loadings) that minimise \(\lVert X - WH\rVert_F\). The Lee–Seung multiplicative
updates keep everything non-negative:
\[ H \leftarrow H \odot \frac{W^\top X}{W^\top W H}, \qquad
W \leftarrow W \odot \frac{X H^\top}{W H H^\top} . \]
Toy example. Record two bytes over four frames. Byte A is a frame counter:
\((0, 64, 128, 192)\). Byte B is the score: \((0, 0, 1, 1)\). Byte A has variance 5120; byte B has
variance 0.25. PCA's first component points almost entirely at A and explains more than 99.99 % of
the variance. The score barely registers. Now suppose the score is what the screen shows and the counter
only drives a blink. The top component has picked the loudest byte, not the causal one.
Variance is a statement about the data, not about cause.
Recipe
- Record the population as a \(T\times n\) matrix \(X\) (here: 128 RAM bytes over \(T\) frames).
- PCA: centre the columns, take the SVD, keep the variance fraction of each component.
- NMF: pick a rank \(r\), run multiplicative updates from a seeded random start, and order components by energy.
- For each leading component, ask whether it matches a known variable (its loading sits on one variable) or a known signal (its activation tracks it).
- Turn the loadings into a per-unit “recovery” score: how strongly the leading components load on each unit.
- On the VCS, compare that score with the oracle's true causal importance of each unit.
From a neural network to the Atari
| Population recording / layer activations | The \(T\times128\) RAM tape: every byte of the VCS's working memory, once per frame. Bytes are 0–255, so the tape is non-negative and NMF applies directly. |
|---|
| Latent factors | The top-5 PCA components and the top-5 of a rank-8 NMF, each with a loading over the 128 bytes and an activation over frames. |
|---|
| Known task variables | The game's candidate bytes, grouped into variable families (score, ball, enemy, …), plus three structural signals: a frame clock ramp, the population write activity (bytes changed per frame), and a periodic frame-phase wave. |
|---|
| “This component is the choice variable” | A matched component: at least half of its candidate-byte loading lies on one family (and candidates carry a real share of the loading), or its activation correlates \(|r|\ge0.5\) with one structural signal. |
|---|
| Importance of a unit (unknown in a brain) | The intervention oracle: set the byte to 0 or base+17 at frame \(f^*\), re-run the real ROM for the horizon, count changed screen pixels. |
|---|
How we apply it to the VCS
The runner A7_dimred.jl does two things: a descriptive match of components to
known signals, and an oracle-scored test of whether the components point at causal bytes.
- The recording. From the shared gameplay state (seeded random actions, checkpoint at frame
\(f^*=90\), 15-frame horizon),
a7_record_ram steps the real ROM with
env_step! and stores the RAM each frame. The trajectory is 150 frames for most games,
continued with NOOP after the gameplay window.
- Decompositions.
run_pca centres the raw byte values and takes an SVD.
run_nmf runs 300 Lee–Seung updates at rank 8 from a seeded random start, then sorts
components by energy (the size of each rank-one part \(W_{:,k}H_{k,:}\)). No package is added; both are
written out in the file.
- Matching.
known_signals builds the clock ramp, the write-activity count, and a
sinusoid at the dominant autocorrelation period of that count. match_components then
labels each of the top-5 components as a game variable, a known signal, or unmatched (purity threshold
0.5). The headline record value is the NMF matched-component fraction.
- Causal check.
recovery_scores gives each candidate byte a score: its squared
loading on the top-5 components, weighted by variance (PCA) or energy (NMF).
oracle_importance pokes each candidate byte to 0 and to base+17, re-runs the horizon and
counts changed pixels. A third value, base+37, is held out. score_triad gives F (Spearman
rank correlation of recovery vs importance), S (Pearson against the held-out effect) and M (the true
cause set's size over the named set's size).
Read the match metric carefully. A component that tracks the frame clock counts as
“matched”. That is honest bookkeeping (the component is a real signal), but it is
the epiphenomenal signal A5 warns about. The triad is what asks whether the components point at
causes. Note also that the “frame-phase” wave is a stand-in: per-frame sampling cannot see the real
VSYNC pulse, so it is a periodic proxy derived from the data.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
A7_dimred.jl:382 — PCA by SVD of the centred RAM tape: loadings and variance fractions. - XAI
A7_dimred.jl:418 — Lee–Seung multiplicative-update NMF, seeded and dependency-free. - XAI
A7_dimred.jl:489 — The structural signals a component may match: clock ramp, write activity, frame-phase wave. - XAI
A7_dimred.jl:576 — Labels each leading component as a game variable, a known signal, or unmatched. - XAI
A7_dimred.jl:651 — Per-byte recovery score: variance- or energy-weighted squared loading on the top components. - XAI
A7_dimred.jl:688 — Ground truth per byte: poke it, re-run the ROM, count changed pixels. - XAI
A7_dimred.jl:749 — F (Spearman), S (held-out Pearson) and M (minimality) against the oracle. - substrate
triad_sm.jl:57 — The shared minimality scorer \(M=|U^*|/|\hat U|\) used across the study. - substrate
jutari_oracle.jl:176 — The intervention: write one value into one RAM byte. - substrate
StellaEnvironment.jl:259 — One video frame of the real, bit-exact machine.
Reading the result
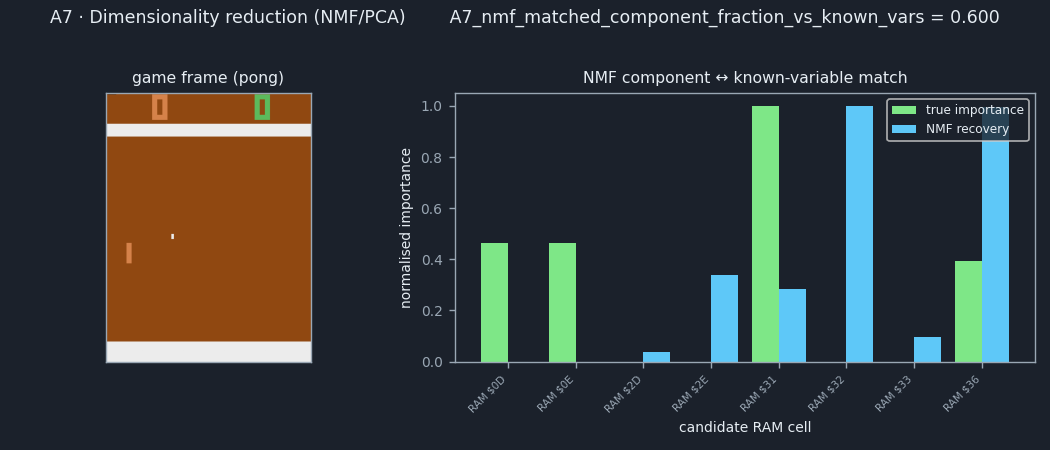
The figure shows two bars per candidate byte (Pong): the oracle's true causal importance and the
byte's NMF recovery score, both scaled so the largest is 1. A faithful decomposition would give bars
of matching height. Expect them not to match. The leading components favour the bytes that vary most,
such as a paddle position the oracle calls inert, while bytes that matter but barely change, such as
the scores, get almost no recovery. The match metric in the record tells a kinder story: a good share
of the leading components match a game variable or a known signal, for PCA and NMF alike. The
structure is real; it is just not the same thing as the program's causal story.
Pitfalls
- Variance is not importance. A wide-ranging counter dominates PCA while a one-bit flag that decides the game barely moves it (the toy example). Raw byte values are not rescaled here, so wide-range bytes weigh more.
- Components mix variables. Nothing forces one component per true variable. PCA's orthogonality constraint and NMF's additivity both produce blends when variables co-vary.
- A match is not an explanation. Matching the clock is a correct label for a causally inert signal. Matching a game variable says the variable varies a lot, not that the program uses it here.
- Arbitrary choices. Rank, number of components kept, purity threshold and NMF seed all change the answer. NMF also has no unique solution.
- Correlational. Like every recording-only method, it never intervenes. Only the oracle comparison tells you whether a component points at causes.
Try it yourself
julia --project=jutari tools/xai_study/phaseA_kording/A7_dimred.jl --games core
Writes A7_<game>.json/.npz (variance curves, loadings, matches, recovery scores, oracle importance, PCA and NMF triads) plus A7_dimred_all.json into tools/xai_study/phaseA_kording/out/. Flags --nmf-rank, --topk and --purity let you test the sensitivity. Minutes per game.
Original papers & further reading
- Lee & Seung (1999). Learning the parts of objects by non-negative matrix factorization. Nature 401: 788–791. — doi.org/10.1038/44565
- Cunningham & Yu (2014). Dimensionality reduction for large-scale neural recordings. Nature Neuroscience 17: 1500–1509. — doi.org/10.1038/nn.3776
- Jonas & Kording (2017). Could a Neuroscientist Understand a Microprocessor? PLoS Computational Biology 13(1): e1005268. — doi.org/10.1371/journal.pcbi.1005268
Read next: A5 · Local field potentials · A3 · Tuning curves · Sparse autoencoders · Linear probing + control tasks