RISE explains a black box by random masking. It generates many random masks, applies each to the input, records the output for each masked version, and then forms an importance map as the output-weighted average of the masks. Inputs that tend to be present when the output is high receive high importance. The method needs no gradients and no access to the model's internals; it only needs to query the output, which is why it is popular for truly opaque systems. The intuition is a Monte-Carlo estimate of each input's marginal effect. We apply it to the VCS by drawing hundreds of random masks over the candidate causes, re-running the program for each, and averaging. Because it perturbs and re-runs the real machine, it works on a sprite's position where gradients are dead, unlike the gradient family. Its accuracy depends on the number of masks and on how informative random masking is for a given output. On smooth content outputs it does reasonably well. On a discrete position output, masking a single discrete cause is less informative, so the estimate is noisier and its faithfulness drops. RISE is a clean example of a perturbation method that is genuinely causal in its mechanism but pays for using random rather than targeted interventions.
Top row (image domain, as in Paper 1): the game frame, then the oracle's true causal region and this method's attributed region — each painted onto the frame through the screen footprint of the RAM cells it implicates (brighter = more important). A faithful method's heat matches the oracle's. Bottom: per-cell importance — oracle (green) vs method (blue) — and the deletion/insertion faithfulness curves (perturb the ranked causes and watch the output move). Note: the image-domain overlay footprints are illustrative, computed on the pre-redesign boot frame; the bars, curves and all reported numbers come from the re-run records on the shared gameplay states. pearson_corr_with_oracle = 0.610 — this example only (pong, state f90+15); the audit aggregate is below.
This example explains the content of RAM $36 (byte 54) — the most causally-active concept byte at this state. Its strongest true-causes are: RAM $36 (the play area — ball / paddles); RAM $31 (17% of its footprint sits in the score band, the rest in the play area). The score digits appear in the region because RAM $31 reaches them: perturbing it over the 30-frame NOOP window changes the game outcome, and hence the score — a downstream effect, not direct rendering.
New to explainable AI? This block explains the method as it is used on neural networks, then how we run the very same method on an Atari 2600, where — unlike for a network — we know the right answer. Every implementation step links to the code. See also the XAI primer for the shared vocabulary.
Occlusion hides one part at a time. RISE hides many parts at once, at random. Throw a random pattern of holes over the photo (about half the pixels hidden), run the network, write down the dog score. Repeat a few hundred times with fresh random patterns. Now ask, for each pixel: when this pixel happened to be visible, how high was the score on average? Pixels the network needs will be visible mostly in the high-scoring runs. Pixels it ignores will be visible in high and low runs alike.
This is a Monte-Carlo estimate: instead of trying every possible pattern (there are \(2^n\)), you average over random samples, and the estimate gets better as you draw more. RISE is a black-box method like occlusion. Because many parts are hidden together, it can notice parts that only matter in combination, which occlusion cannot. The price is noise: with few masks, the map is grainy.
Draw \(N\) random binary masks \(m_1,\dots,m_N \in \{0,1\}^n\). Each entry is an independent coin flip: kept (\(1\)) with probability \(p\), hidden (\(0\)) otherwise (a Bernoulli variable). Run the model on each masked input, \(y_k = f(x \odot m_k)\). The importance of input \(i\) is
\[ S_i \;=\; \frac{1}{N\,p}\sum_{k=1}^{N} y_k \, m_{k,i} \;\;\approx\;\; \mathbb{E}\big[\,y \mid m_i = 1\,\big] . \]That is the average output over the masks that kept input \(i\): a conditional expectation. The \(1/(Np)\) factor turns the sum into that average, because about \(Np\) masks keep \(i\). On images, RISE draws small grids, upsamples them smoothly and shifts them randomly, so the holes are blobs rather than single pixels.
Toy example. \(f(x) = 4x_1x_2 + x_3\) at \(x=(1,1,1,1)\) (\(x_4\) unused), \(p = 0.5\). Enumerate all 16 masks instead of sampling. When \(x_1\) is kept, \(x_2\) is kept half the time and \(x_3\) half the time, so \(\mathbb{E}[y\mid m_1{=}1] = 4\cdot0.5 + 0.5 = 2.5\). Likewise \(S_2 = 2.5\), \(S_3 = 4\cdot 0.25 + 1 = 2\), \(S_4 = 1.5\). The unused \(x_4\) gets exactly the overall mean \(\mathbb{E}[y] = 1.5\). Subtract it and you get \((1, 1, 0.5, 0)\): the interaction pair ranks first, \(x_3\) second, \(x_4\) is zero. With \(p = 0.5\) this centred score is half the average change caused by switching \(x_i\) on (the Banzhaf value, a close relative of the Shapley value). Note: occlusion on the same toy gives \((4,4,1,0)\), and both agree on the ranking here.
| The network \(f\) | The cartridge program on the bit-exact emulated Atari 2600 VCS (jutari). |
|---|---|
| The pixels \(x_i\) | The candidate RAM cells (the bytes the oracle scores), de-duplicated: 8 to 23 per core game. TIA and joystick causes are not in RISE's universe. |
| Masked input \(x\odot m\) | deepcopy the checkpoint, intervene_ram!(env, i, 0) for every dropped cell, run 15 frames of the real ROM. |
| \(N\) masks, keep-prob \(p\) | \(N = 500\) masks, \(p = 0.5\), from a seeded random generator, so the run is reproducible. |
| The output \(y\) | A content RAM byte at \(f^*{+}15\), or the number of screen pixels that differ from the un-intervened frame. |
| “Ground-truth importance” | The oracle's per-cause |Δy|, from single-cause re-runs (+17 and →0 per byte, plus a TIA and a joystick do). |
The VCS version follows the paper's formula one-to-one; only the “image” changes.
The universe is the list of candidate RAM cells. Each of the \(N = 500\) masks keeps every cell with
probability \(p = 0.5\). For each mask, masked_read_y copies the checkpoint, zeroes the
dropped cells with intervene_ram!, plays the recorded 15 actions with
env_step!, and reads \(y\). Those 500 real-emulator runs are the whole cost of the
method. rise_importance then computes \(\frac{1}{Np}\sum_k y_k m_{k,i}\).
From cells to causes. The oracle scores causes, not cells.
rise_attr_per_cause centres the cell scores by subtracting their mean across
cells, takes the absolute value, and gives each RAM cause the score of its cell (so a byte's
:set and :occlude causes get the same value). TIA and joystick causes get
0, because RISE never touches them.
Convergence. RISE is a Monte-Carlo estimate, so the runner also rescores the map using only the first \(N/8\), \(N/4\), \(N/2\) masks of the same pool. That shows how the agreement with the oracle grows with compute, without drawing new masks.
How is this different from the oracle? Three ways. (1) Joint masks: in every run about half the cells are zeroed at once, so each \(y_k\) mixes many effects; the oracle changes one cause at a time. (2) Averaging: RISE reports an average over random contexts, the oracle a single exact difference at the real state. (3) One direction: RISE only ever sets cells to 0. On a content byte that responds smoothly to many cells, the average is informative. On the position output, the effect of one cell is often an all-or-nothing jump that depends on which other cells are zeroed with it, so the average is noisier.
XAI the interpretability method substrate the bit-exact emulator it runs on (jutari, Julia).
rise.jl:147 — Draws \(N\) Bernoulli(\(p\)) masks and re-runs the real ROM once per mask.rise.jl:128 — One masked run: deepcopy, zero every dropped cell, 15 × env_step!, read y.rise.jl:172 — Petsiuk's estimator \(\frac{1}{Np}\sum_k y_k m_{k,i}\).rise.jl:193 — Centre across cells, take |·|, map cells to the oracle's causes; TIA/joystick get 0.rise.jl:305 — The convergence sweep: rescoring from prefixes of the same mask pool.rise.jl:647 — The defaults: 500 masks, keep-probability 0.5.jutari_oracle.jl:176 — The poke that zeroes a dropped cell in the emulated RAM.StellaEnvironment.jl:259 — One frame of the real machine; each mask costs 15 of them.oracle_intervene.jl:242 — The oracle's single-cause re-run, which RISE's joint masks are compared with.shared_testbed_impl.jl:115 — The shared gameplay checkpoint and the position output.Bars are RISE scores per cause, next to the oracle's true effect. Two features are built in: TIA and joystick causes are always zero for RISE, and the two causes of one byte always share a height. Beyond that, compare the tallest bars. On content outputs expect reasonable agreement; on position outputs expect a noisier map with a weaker match. The convergence numbers in the record show whether more masks would still help: if agreement is still rising from \(N/2\) to \(N\), the estimate has not settled.
julia --project=jutari tools/xai_study/phaseB_attribution/rise.jl --games core
Writes rise_<game>_{content,ball_pixel}.json/.npz into tools/xai_study/phaseB_attribution/out/, including the convergence sweep. Change the budget with --n-masks and --keep-prob.
Read next: KernelSHAP / Shapley · LIME · Occlusion · Extremal / meaningful perturbation
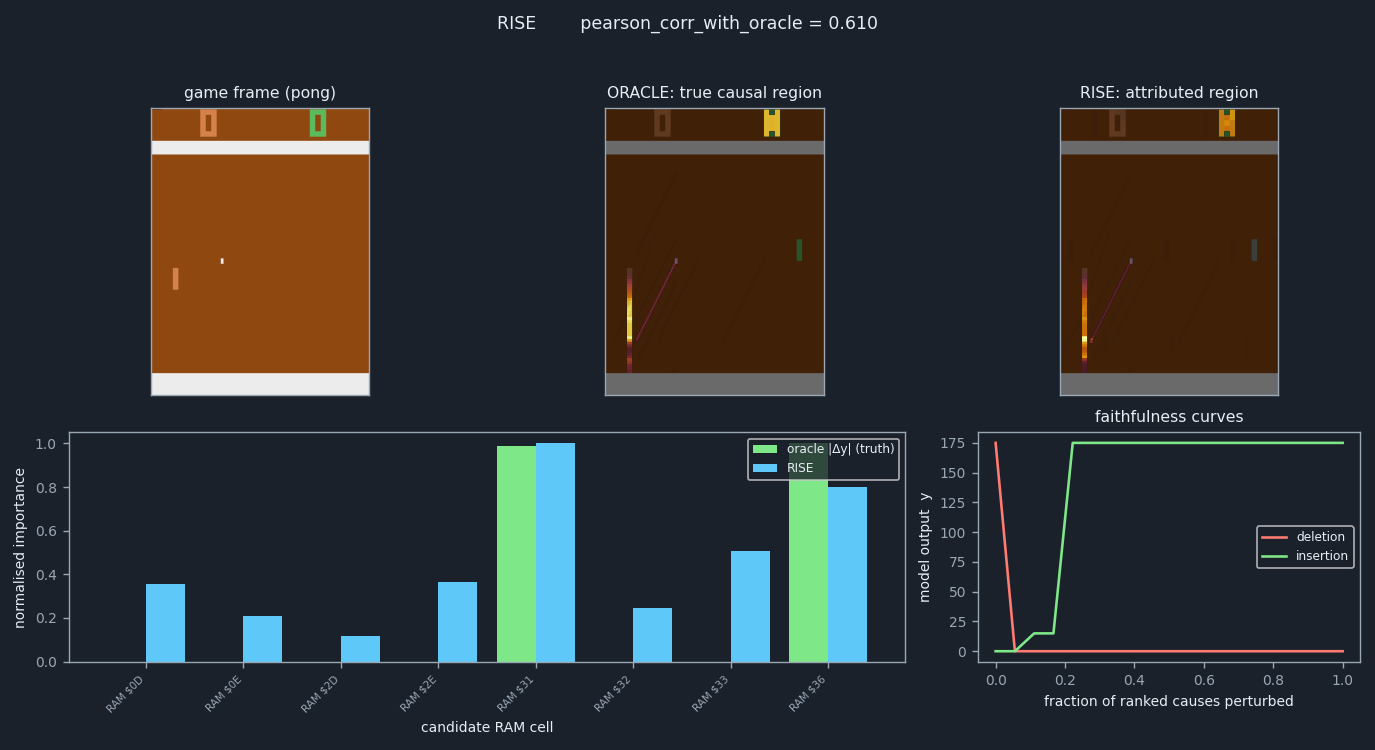
The score is the Pearson correlation of the RISE importance map with the oracle's exact causal map, reported raw, and the grading is always against the intervention oracle. RISE forms its map by averaging the output over hundreds of random masks, each a real re-run of the machine, so it is a genuine perturbation method and works on a sprite's position where the gradient family scores zero. That is why it does not collapse on the position regime. Its faithfulness is moderate: on smooth content outputs the random-mask average recovers the true causes reasonably well, but on a discrete position output masking a single discrete cause is less informative, so the estimate is noisier and the position score drops below the content score. The accuracy also depends on how many masks are drawn, since RISE is a Monte-Carlo estimate. The grading is always against the oracle, never against another method. The audit box reports the measured all-regime faithfulness across the 44 scored games, which averages the stronger content result and the weaker position result. RISE shows that a truly perturbation-based method can beat the gradient family on discrete outputs while still paying for using random rather than targeted interventions.
The score is measured against the §1 intervention oracle — never against another interpretability method. F (faithful) is always vs the oracle; see the execution stack. How each of F / S / M is actually computed for this method (and whether it matches the paper) is in the box just below; the numbers are in the In the audit box under it.
The exact formula this method uses for each score, read from its runner, and
whether it matches the paper's §3 (F ∧ S ∧ M triad) definition.
From the committed audit
fsm_math_phaseB.json.
| Axis | Formula (as computed) | What it measures | Matches §3? |
|---|---|---|---|
| F faithfulness | \(F = \rho_{\mathrm{Pearson}}\!\left(\mathrm{attr},\ |\Delta y(u)|\right)\) | Raw Pearson correlation between the method's per-cause attribution magnitudes and the oracle's true absolute causal effects |Delta_y(u)|, scored separately for the content and position output regimes. | ✓ matches rise.jl: pr = pearson(attr, odelta); triad_extra_dict(f.pearson, f.rise_attr_per_cause, f.oracle_abs_delta). Record: out/rise_air_raid_content.json (value=0.76); note M=0.077 there (|U_hat|=26 named vs |U*|=2 movers) illustrating the dense-mask minimality penalty. Scorer pilot_ig_vs_oracle.jl pearson() (raw Statistics.cor, zero-variance->0); F = pearson(attr, oracle_abs_delta) where oracle_abs_delta = abs.(cmap.delta) (true |Delta_y| per cause). Also reports spearman, precision@k, deletion/insertion AUC (paper's auxiliary F metrics). Per-regime split: separate *_content.json and *_position.json records, each carrying its own extra.triad.{F,S,M}. how it's measured — call stack:
|
| S sufficiency | \(S = \dfrac{\#\{\,u_{\mathrm{held}}:\ |\hat{y}-y|\le\varepsilon\,\}}{|\mathrm{held\text{-}out}|}\in[0,1]\) | Fit Delta_y = a*attr + b on a calibration half of the do(u) causes, predict the disjoint held-out half, and report the fraction of held-out causes whose predicted output lands within an epsilon band of the oracle's bit-exact re-run. | ✓ matches common/triad_sm.jl sufficiency_score() (interleaved calib/held split by seed, least-squares 1-D fit Delta_y~a*attr+b on calib, epsilon = max(0.5, 0.10*heldout_spread)); assembled in triad_extra_dict(). The new §3 (sec:triad) admits the fraction-within-tolerance [0,1] special case of the held-out predictive test, which this held-out do(u) fit-then-predict estimator satisfies, so it matches. (Detail: epsilon is a self-scaled band 0.10*spread; the [-1,1] correlation form is available but this method reports the [0,1] hit fraction.) how it's measured — call stack:
|
| M minimality | \(M = |U^{\star}| / |\hat{U}| \in (0,1]\quad U^{\star}=\{u:\Delta y(u)>0\},\ \hat{U}=\{u:|\mathrm{attr}(u)|>\tau\}\) | Ratio of the number of oracle causal movers (causes with nonzero true Delta_y) to the number of cells the method names above 1e-6 of its own max attribution; null when the oracle finds no mover or the method names nothing. | ✓ matches common/triad_sm.jl minimality_score() with name_frac=1e-6, mover_floor=0.0; the above-threshold named set is used (topk kept but not passed), see triad_extra_dict(). RISE names a dense mask, so |U_hat| >> |U*| and M is small (e.g. 2/26=0.077 in the air_raid content record) -- the intended discrimination of the above-threshold reading. This is the paper's M = |U*|/|U_hat| in (0,1] (standardized everywhere), so it matches the new §3. (Detail: |U*| is taken as all oracle movers with Delta_y>0, an upper bound on the strictly-smallest reproducing subset, so M can be optimistic.) how it's measured — call stack:
|
✓ matches = the same quantity as §3; ◐ partial = the same kind of estimator but a differing detail; ✗ does not match = a different quantity (see the note). Definitions: F = agreement with the oracle's true causal effects Δy(u); S = held-out predictive score in [−1, 1]; M = |U*|/|Û| (true-minimal-set size / named-set size).
This is the method's entry in the actual cross-method audit — scored on the paper's correctness triad, each axis a mean over 44 of the 44 scored games (88 committed §R records), not the single example shown above. Tradition: gradient. The example figure (Pong) is one of those records.
F faithfulness (scored vs the oracle for every method) · S sufficiency (held-out predictive score in [−1, 1]; a negative value means the explanation predicts held-out interventions worse than the unperturbed baseline; reported for the predictive methods across all three phases where the calibration/held-out split is defined) · M minimality (true-minimal-set / named-set; where the method names a cause set) — n/a otherwise, per the paper's F ∧ S ∧ M triad.
Source: leaderboard.json · the whole leaderboard is on the
methods page and the
Paper 2 audit.
This method's faithfulness on each of the 44 scored games (all-regime F, and the content vs position split). Click a header to
sort. Every number is read from site_data.json
(methods.rise.per_game).
| Game | F (all) | content-F | position-F | S | M | Note |
|---|---|---|---|---|---|---|
| Montezuma's Revenge | 0.875 | 0.964 | 0.787 | 0.781 | 0.400 | recovers the true causes |
| Fishing Derby | 0.867 | 0.920 | 0.815 | 0.600 | 0.278 | recovers the true causes |
| Space Invaders | 0.831 | 0.966 | 0.695 | 0.778 | 0.294 | |
| Bowling | 0.790 | 0.774 | 0.806 | 0.857 | 0.225 | holds up on position |
| Gopher | 0.765 | 0.746 | 0.785 | 0.929 | 0.287 | holds up on position |
| Private Eye | 0.718 | 0.713 | 0.723 | 0.960 | 0.230 | holds up on position |
| Skiing | 0.700 | 0.781 | 0.620 | 0.600 | 0.417 | |
| Phoenix | 0.684 | 0.847 | 0.520 | 0.192 | 0.292 | |
| Krull | 0.661 | 0.958 | 0.364 | 0.538 | 0.190 | |
| Bank Heist | 0.648 | 0.852 | 0.443 | 0.833 | 0.500 | |
| Pacman | 0.645 | 0.758 | 0.532 | 0.444 | 0.344 | |
| Jamesbond | 0.644 | 0.685 | 0.603 | 0.893 | 0.288 | |
| Riverraid | 0.629 | 0.973 | 0.286 | 0.565 | 0.432 | |
| Ice Hockey | 0.628 | 0.720 | 0.536 | 0.591 | 0.500 | |
| Q*bert | 0.620 | 0.976 | 0.264 | 0.452 | 0.188 | |
| Frostbite | 0.619 | 0.534 | 0.704 | 0.250 | 0.395 | holds up on position |
| Boxing | 0.611 | 0.798 | 0.424 | 0.583 | 0.341 | |
| Alien | 0.611 | 0.743 | 0.479 | 0.571 | 0.333 | |
| Demon Attack | 0.608 | 0.575 | 0.641 | 0.812 | 0.350 | holds up on position |
| Pitfall | 0.601 | 0.552 | 0.649 | 0.882 | 0.344 | holds up on position |
| Atlantis | 0.594 | 0.528 | 0.660 | 0.450 | 0.417 | holds up on position |
| Video Pinball | 0.569 | 0.731 | 0.406 | 0.500 | 0.500 | |
| Breakout | 0.565 | 0.727 | 0.403 | 0.550 | 0.361 | |
| Kung-Fu Master | 0.563 | 0.721 | 0.405 | 0.800 | 0.361 | |
| Pong | 0.534 | 0.610 | 0.458 | 0.389 | 0.281 | |
| Road Runner | 0.510 | 0.171 | 0.849 | 0.368 | 0.167 | holds up on position |
| Asterix | 0.505 | 0.507 | 0.503 | 0.500 | 0.417 | |
| Kangaroo | 0.490 | 0.979 | 0.000 | 0.500 | 0.300 | position gradient vanishes |
| Tennis | 0.477 | 0.954 | 0.000 | 0.406 | 0.350 | position gradient vanishes |
| Double Dunk | 0.472 | 0.698 | 0.246 | 0.538 | 0.500 | |
| Air Raid | 0.441 | 0.381 | 0.501 | 0.607 | 0.423 | holds up on position |
| Name This Game | 0.408 | 0.749 | 0.067 | 0.417 | 0.450 | |
| Enduro | 0.405 | 0.795 | 0.015 | 0.000 | 0.500 | position gradient vanishes |
| Ms. Pac-Man | 0.395 | 0.790 | 0.000 | 0.475 | 0.342 | position gradient vanishes |
| Assault | 0.393 | 0.100 | 0.686 | 0.905 | 0.263 | holds up on position |
| Yars' Revenge | 0.378 | 0.756 | 0.000 | 0.464 | 0.211 | position gradient vanishes |
| Seaquest | 0.346 | 0.000 | 0.693 | 0.479 | 0.413 | holds up on position |
| Centipede | 0.339 | 0.678 | 0.000 | 0.450 | 0.472 | position gradient vanishes |
| Berzerk | 0.335 | 0.670 | 0.000 | 0.481 | 0.260 | position gradient vanishes |
| Carnival | 0.330 | 0.661 | 0.000 | 0.474 | 0.417 | position gradient vanishes |
| Chopper Command | 0.318 | 0.000 | 0.636 | 0.452 | 0.400 | holds up on position |
| Hero | 0.291 | 0.091 | 0.491 | 0.417 | 0.265 | |
| Freeway | 0.259 | 0.471 | 0.047 | 0.567 | 0.500 | |
| Venture | 0.243 | 0.487 | 0.000 | 0.474 | 0.500 | position gradient vanishes |
The path from this method's runner (main) into the bit-exact VCS substrate, and the
computation it involves. Every step links to the exact source on main. From
callstack_phaseB.json.
env_reset! / env_step! jutaribuild_shared_testbed jutarimasked_read_y -> intervene_ram! jutari intervene_ram! call at rise.jl:131 -> jutari_oracle.jl:174rise_sample runnerrise_importance runnersnapshot jutariScored against the exact intervention oracle Δy(u): run_intervention.
The figure is generated from the committed record by
docs/gen_method_figures.py; the game frame
and each RAM cell's screen footprint are produced by
render_scenes.jl /
cell_footprints.jl.