LIME explains one prediction by fitting a simple model nearby. Around the input of interest it generates many perturbed versions, records the output for each, and then fits a sparse linear surrogate to that local data. The weights of the surrogate are read as the explanation: which inputs, locally, push the output up or down. The idea is that even a complicated system is roughly linear in a small neighbourhood, so a linear fit there is both faithful and easy to read. LIME is model-agnostic and one of the most cited attribution methods. We apply it to the VCS by perturbing the candidate causes around the live state, re-running the program to get outputs, and fitting a local linear model whose weights we correlate with the true causal map. Because the perturbations are real re-runs, LIME works on a sprite's position where gradients fail. It fits both content and position structure reasonably well, so it lands among the more faithful attribution methods. Its main caveats are the usual ones: the explanation depends on how the neighbourhood is sampled and on the surrogate's fit quality, so it can be unstable across runs. On the VCS we can check its surrogate against the exact answer, which is a test the method never gets on a real network.
Top row (image domain, as in Paper 1): the game frame, then the oracle's true causal region and this method's attributed region — each painted onto the frame through the screen footprint of the RAM cells it implicates (brighter = more important). A faithful method's heat matches the oracle's. Bottom: per-cell importance — oracle (green) vs method (blue) — and the deletion/insertion faithfulness curves (perturb the ranked causes and watch the output move). Note: the image-domain overlay footprints are illustrative, computed on the pre-redesign boot frame; the bars, curves and all reported numbers come from the re-run records on the shared gameplay states. pearson_corr_with_oracle = 0.686 — this example only (pong, state f90+15); the audit aggregate is below.
This example explains the content of RAM $36 (byte 54) — the most causally-active concept byte at this state. Its strongest true-causes are: RAM $36 (the play area — ball / paddles); RAM $31 (17% of its footprint sits in the score band, the rest in the play area). The score digits appear in the region because RAM $31 reaches them: perturbing it over the 30-frame NOOP window changes the game outcome, and hence the score — a downstream effect, not direct rendering.
New to explainable AI? This block explains the method as it is used on neural networks, then how we run the very same method on an Atari 2600, where — unlike for a network — we know the right answer. Every implementation step links to the code. See also the XAI primer for the shared vocabulary.
A deep network is a very curvy function. But zoom in far enough on any smooth curve and it looks like a straight line. LIME uses this idea. To explain one prediction, it builds a simple model (a straight-line, i.e. linear, model) that imitates the network only near this one input. Such a stand-in model is called a surrogate. The weights of the surrogate are the explanation: a large positive weight means “this part pushes the output up, around here”.
How do you get data to fit the surrogate? You make it. Switch random parts of the input off (for an image: grey out random superpixels, patches of similar colour), run the network on each version, and record the outputs. Versions that are close to the original get a high weight in the fit, far-away versions a low one. Then fit the line. LIME is model-agnostic: it treats the model as a black box, so it works for networks, random forests, or, as here, a game console.
Describe each perturbed version by a binary vector \(z \in \{0,1\}^d\): \(z_j = 1\) if part \(j\) is present, \(0\) if it was switched off. The original input is \(z = \mathbf 1\) (all present). Sample \(z_1,\dots,z_N\), run the model on each, \(y_k = f(h(z_k))\), where \(h\) maps \(z\) back to a real input. Weight each sample by its closeness to the original, \(\pi_k = \exp(-D(z_k,\mathbf 1)^2/\sigma^2)\), with distance \(D\) and kernel width \(\sigma\). Then solve the weighted least-squares problem
\[ (w, b) \;=\; \arg\min_{w,b}\; \sum_{k=1}^{N} \pi_k\,\big(y_k - w\cdot z_k - b\big)^2 . \]The coefficients \(w_j\) are the attribution. The library version also keeps only the top few features (a sparse fit) and adds a small ridge penalty. The fit's \(R^2\) (the share of the output variation the line explains) tells you how linear the neighbourhood really is.
Toy example. Two parts, \(f(z) = 3z_1 + 2z_1z_2\). The four possible samples are \(f(1,1)=5\), \(f(1,0)=3\), \(f(0,1)=0\), \(f(0,0)=0\). Give the original weight 1, the two one-off samples weight 0.5, the all-off sample 0.25. Solving the \(3\times3\) normal equations gives \(w_1 = 13/3 \approx 4.33\), \(w_2 = 4/3 \approx 1.33\), \(b = -8/9\). Compare with the truth at the original: switching off \(z_1\) costs 5, switching off \(z_2\) costs 2. With equal weights the fit would give \(w_1 = 4\), \(w_2 = 1\), \(b = -0.5\). The locality weights pull the line toward the original, so \(w_2\) moves from 1 toward the local value 2. No line can fit the interaction term \(2z_1z_2\) exactly; the surrogate spreads it over both coefficients, and \(R^2 < 1\) shows it.
| The black-box model \(f\) | The cartridge program on the bit-exact emulated Atari 2600 VCS (jutari). |
|---|---|
| Superpixels (interpretable parts) | The candidate RAM cells, de-duplicated (8 to 23 per core game). TIA and joystick causes are not in the interpretable space. |
| \(h(z)\): switch parts off | deepcopy the checkpoint and intervene_ram!(env, j, 0) for every absent cell; then 15 frames of the real ROM. |
| Samples \(N\), kernel \(\pi\) | \(N = 300\), keep-prob 0.5, the first sample is the all-present original; cosine-distance kernel with \(\sigma = 0.75\sqrt{d}\). |
| Surrogate \(g(z)=w\cdot z+b\) | Weighted least squares with a tiny ridge (\(10^{-6}\)) on the coefficients; all cells kept (no sparsity step). |
| “Ground-truth importance” | The oracle's single-cause |Δy| per cause, from real re-runs. |
Sampling. lime_sample draws \(N = 300\) present/absent vectors over the
candidate RAM cells. Row 1 is forced to the original (all present); every other cell is present with
probability 0.5. For each row, masked_read_y copies the checkpoint, zeroes the absent
cells with intervene_ram!, plays the recorded 15 actions with env_step!,
and reads \(y\). These 300 real-emulator runs are the whole cost of one fit.
Weights. lime_weights uses the cosine distance between \(z\) and
\(\mathbf 1\) and the kernel \(\exp(-D^2/\sigma^2)\) with the LIME library's default width
\(\sigma = 0.75\sqrt{d}\) (\(d\) = number of cells). Cosine distance here lies between 0 and 1, while
\(\sigma\) is above 2 for 8 or more cells, so all weights stay between roughly 0.8 and 1. In practice
the fit is close to an unweighted least-squares fit over a broad neighbourhood (about half the
cells zeroed per sample), not a tight local one.
Fit. fit_weighted_linear solves the ridge-regularised normal equations and
returns the coefficients, the intercept and the weighted \(R^2\). Each RAM cause gets \(|w_j|\) of its
cell; TIA and joystick causes get 0. The sign is dropped because the oracle column is a magnitude.
Stability. LIME depends on its random samples, so the runner refits from 5 independent seeds (5 × 300 re-runs per output) and records the spread of the oracle correlation, of \(R^2\), and the average cosine similarity between the coefficient vectors.
How is this different from the oracle? The oracle asks one exact question per cause: “change only this, at the real state, what happens?” LIME asks many joint questions (half the cells zeroed at once) and then compresses the answers into one line. If the game logic were additive, the line's coefficients would equal the zeroing effects. Where it is not (thresholds, AND-like interactions, sprite timing), the line averages the effect over damaged contexts, and the \(R^2\) tells you how much it missed.
XAI the interpretability method substrate the bit-exact emulator it runs on (jutari, Julia).
lime.jl:163 — Draws the present/absent design matrix (row 1 = the original) and re-runs the ROM once per row.lime.jl:142 — One perturbed run: deepcopy, zero the absent cells, 15 × env_step!, read y.lime.jl:188 — The locality kernel \(\exp(-D^2/\sigma^2)\) with cosine distance to the original.lime.jl:211 — The surrogate: ridge-regularised weighted least squares, plus the weighted \(R^2\).lime.jl:775 — Default kernel width \(0.75\sqrt{d}\), the LIME library's choice.lime.jl:390 — The stability sweep: refits from fresh seeds and compares them.jutari_oracle.jl:176 — The poke that switches a cell “off” in the emulated RAM.StellaEnvironment.jl:259 — One frame of the real machine; each sample costs 15 of them.oracle_intervene.jl:242 — The oracle's single-cause re-run, the ground truth for the surrogate's weights.shared_testbed_impl.jl:115 — The shared gameplay checkpoint and the position output.Bars are \(|w_j|\) per cause next to the oracle's true effect; TIA and joystick causes are zero for LIME by construction, and both causes of a byte share a height. Read the record's surrogate \(R^2\) before trusting the bars: a low value is LIME admitting that a line is a poor model of the game near this state. Also read the stability block: if refits with other seeds disagree, the ranking is partly sampling luck. Expect LIME to track the main structure on both content and position outputs reasonably well.
julia --project=jutari tools/xai_study/phaseB_attribution/lime.jl --games core
Writes lime_<game>_{content,ball_pixel}.json/.npz into tools/xai_study/phaseB_attribution/out/, with the surrogate \(R^2\) and the stability block. Knobs: --n-samples, --kernel-width, --stability-seeds.
Read next: KernelSHAP / Shapley · RISE · Occlusion · Linear probing + control tasks
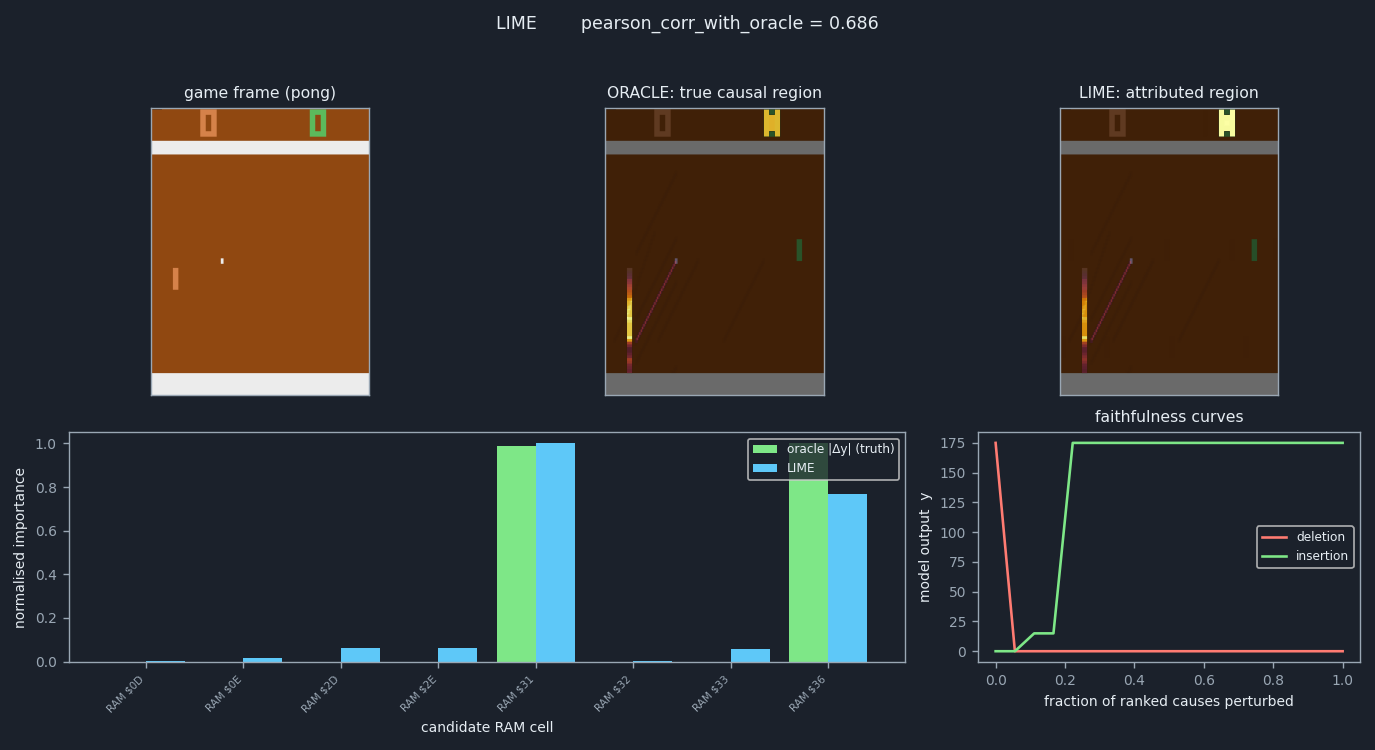
The score is the Pearson correlation of the local linear surrogate's weights with the oracle's exact causal map, reported raw, and the grading is always against the intervention oracle. LIME fits a sparse linear model to real re-runs of the machine around the live state, so its perturbations are valid interventions and it works on a sprite's position where the gradient family scores zero. That is why there is no position collapse here. It fits both content and position structure reasonably well, so it lands among the more faithful attribution methods. The surrogate also reports its own fit quality, the local R-squared, which acts as an internal check on how linear the neighbourhood really is. The main caveats the score reflects are the usual ones for LIME: the explanation depends on how the neighbourhood is sampled and on the surrogate's fit, so it can vary across runs, and we report that stability alongside the correlation. The grading never compares LIME to another method, only to the oracle. The audit box reports the measured all-regime faithfulness across the 44 scored games, so the number reflects the whole scored set. On the VCS we can test the surrogate against the exact answer, which a real network never allows.
The score is measured against the §1 intervention oracle — never against another interpretability method. F (faithful) is always vs the oracle; see the execution stack. How each of F / S / M is actually computed for this method (and whether it matches the paper) is in the box just below; the numbers are in the In the audit box under it.
The exact formula this method uses for each score, read from its runner, and
whether it matches the paper's §3 (F ∧ S ∧ M triad) definition.
From the committed audit
fsm_math_phaseB.json.
| Axis | Formula (as computed) | What it measures | Matches §3? |
|---|---|---|---|
| F faithfulness | \(F = \rho_{\mathrm{Pearson}}\!\left(\mathrm{attr},\ |\Delta y(u)|\right)\) | Raw Pearson correlation between the method's per-cause attribution magnitudes and the oracle's true absolute causal effects |Delta_y(u)|, scored separately for the content and position output regimes. | ✓ matches lime.jl: pr = pearson(attr, odelta); a stability sweep over K seeds reports corr mean/std but the headline F is the single-run pearson; triad_extra_dict(f.pearson, attr, f.oracle_abs_delta). Record: out/lime_air_raid_content.json (value=0.79). Scorer pilot_ig_vs_oracle.jl pearson() (raw Statistics.cor, zero-variance->0); F = pearson(attr, oracle_abs_delta) where oracle_abs_delta = abs.(cmap.delta) (true |Delta_y| per cause). Also reports spearman, precision@k, deletion/insertion AUC (paper's auxiliary F metrics). Per-regime split: separate *_content.json and *_position.json records, each carrying its own extra.triad.{F,S,M}. how it's measured — call stack:
|
| S sufficiency | \(S = \dfrac{\#\{\,u_{\mathrm{held}}:\ |\hat{y}-y|\le\varepsilon\,\}}{|\mathrm{held\text{-}out}|}\in[0,1]\) | Fit Delta_y = a*attr + b on a calibration half of the do(u) causes, predict the disjoint held-out half, and report the fraction of held-out causes whose predicted output lands within an epsilon band of the oracle's bit-exact re-run. | ✓ matches common/triad_sm.jl sufficiency_score() (interleaved calib/held split by seed, least-squares 1-D fit Delta_y~a*attr+b on calib, epsilon = max(0.5, 0.10*heldout_spread)); assembled in triad_extra_dict(). The new §3 (sec:triad) admits the fraction-within-tolerance [0,1] special case of the held-out predictive test, which this held-out do(u) fit-then-predict estimator satisfies, so it matches. (Detail: epsilon is a self-scaled band 0.10*spread; the [-1,1] correlation form is available but this method reports the [0,1] hit fraction.) how it's measured — call stack:
|
| M minimality | \(M = |U^{\star}| / |\hat{U}| \in (0,1]\quad U^{\star}=\{u:\Delta y(u)>0\},\ \hat{U}=\{u:|\mathrm{attr}(u)|>\tau\}\) | Ratio of the number of oracle causal movers (causes with nonzero true Delta_y) to the number of cells the method names above 1e-6 of its own max attribution; null when the oracle finds no mover or the method names nothing. | ✓ matches common/triad_sm.jl minimality_score() with name_frac=1e-6, mover_floor=0.0; the above-threshold named set is used (topk kept but not passed), see triad_extra_dict(). This is the paper's M = |U*|/|U_hat| in (0,1] (standardized everywhere), so it matches the new §3. (Detail: |U*| is taken as all oracle movers with Delta_y>0, an upper bound on the strictly-smallest reproducing subset, so M can be optimistic.) how it's measured — call stack:
|
✓ matches = the same quantity as §3; ◐ partial = the same kind of estimator but a differing detail; ✗ does not match = a different quantity (see the note). Definitions: F = agreement with the oracle's true causal effects Δy(u); S = held-out predictive score in [−1, 1]; M = |U*|/|Û| (true-minimal-set size / named-set size).
This is the method's entry in the actual cross-method audit — scored on the paper's correctness triad, each axis a mean over 44 of the 44 scored games (88 committed §R records), not the single example shown above. Tradition: gradient. The example figure (Pong) is one of those records.
F faithfulness (scored vs the oracle for every method) · S sufficiency (held-out predictive score in [−1, 1]; a negative value means the explanation predicts held-out interventions worse than the unperturbed baseline; reported for the predictive methods across all three phases where the calibration/held-out split is defined) · M minimality (true-minimal-set / named-set; where the method names a cause set) — n/a otherwise, per the paper's F ∧ S ∧ M triad.
Source: leaderboard.json · the whole leaderboard is on the
methods page and the
Paper 2 audit.
This method's faithfulness on each of the 44 scored games (all-regime F, and the content vs position split). Click a header to
sort. Every number is read from site_data.json
(methods.lime.per_game).
| Game | F (all) | content-F | position-F | S | M | Note |
|---|---|---|---|---|---|---|
| Enduro | 0.985 | 1.000 | 0.970 | 0.875 | 0.833 | recovers the true causes |
| Fishing Derby | 0.958 | 0.948 | 0.968 | 0.950 | 0.722 | recovers the true causes |
| Riverraid | 0.933 | 1.000 | 0.867 | 0.870 | 0.432 | recovers the true causes |
| Krull | 0.930 | 0.999 | 0.860 | 0.846 | 0.190 | recovers the true causes |
| Montezuma's Revenge | 0.923 | 0.975 | 0.871 | 0.875 | 0.400 | recovers the true causes |
| Name This Game | 0.894 | 0.788 | 1.000 | 0.917 | 1.000 | recovers the true causes |
| Space Invaders | 0.878 | 1.000 | 0.756 | 0.917 | 0.294 | recovers the true causes |
| Bowling | 0.873 | 0.904 | 0.843 | 0.881 | 0.225 | recovers the true causes |
| Boxing | 0.844 | 0.817 | 0.870 | 0.667 | 0.795 | holds up on position |
| Alien | 0.843 | 0.779 | 0.907 | 0.714 | 0.750 | holds up on position |
| Gopher | 0.804 | 0.776 | 0.833 | 0.929 | 0.762 | holds up on position |
| Ice Hockey | 0.783 | 0.737 | 0.829 | 0.636 | 0.500 | holds up on position |
| Phoenix | 0.765 | 0.909 | 0.622 | 0.462 | 1.000 | |
| Pacman | 0.750 | 0.776 | 0.725 | 0.444 | 1.000 | |
| Private Eye | 0.734 | 0.731 | 0.737 | 0.960 | 0.229 | holds up on position |
| Demon Attack | 0.732 | 0.767 | 0.698 | 0.875 | 0.350 | |
| Kung-Fu Master | 0.710 | 0.745 | 0.676 | 0.800 | 0.806 | |
| Frostbite | 0.702 | 0.580 | 0.824 | 0.500 | 0.395 | holds up on position |
| Pitfall | 0.700 | 0.693 | 0.706 | 0.882 | 0.344 | holds up on position |
| Skiing | 0.699 | 0.810 | 0.588 | 0.450 | 0.833 | |
| Q*bert | 0.693 | 0.999 | 0.387 | 0.500 | 1.000 | |
| Jamesbond | 0.684 | 0.727 | 0.640 | 0.893 | 0.288 | |
| Freeway | 0.668 | 0.458 | 0.879 | 0.600 | 0.536 | holds up on position |
| Bank Heist | 0.663 | 0.900 | 0.427 | 0.833 | 0.900 | |
| Atlantis | 0.640 | 0.632 | 0.648 | 0.450 | 0.417 | holds up on position |
| Breakout | 0.632 | 0.750 | 0.515 | 0.550 | 0.806 | |
| Pong | 0.620 | 0.686 | 0.554 | 0.389 | 0.281 | |
| Ms. Pac-Man | 0.582 | 0.810 | 0.352 | 0.475 | 0.816 | |
| Video Pinball | 0.543 | 0.770 | 0.315 | 0.500 | 0.500 | |
| Asterix | 0.506 | 0.525 | 0.487 | 0.500 | 0.417 | |
| Tennis | 0.500 | 1.000 | 0.000 | 0.500 | 0.817 | position gradient vanishes |
| Kangaroo | 0.500 | 0.999 | 0.000 | 0.500 | 0.767 | position gradient vanishes |
| Road Runner | 0.471 | 0.000 | 0.941 | 0.474 | 0.167 | holds up on position |
| Double Dunk | 0.454 | 0.797 | 0.111 | 0.538 | 0.500 | |
| Air Raid | 0.437 | 0.383 | 0.490 | 0.714 | 0.423 | |
| Yars' Revenge | 0.406 | 0.771 | 0.041 | 0.464 | 0.673 | |
| Assault | 0.396 | 0.092 | 0.699 | 0.905 | 0.263 | holds up on position |
| Centipede | 0.379 | 0.757 | 0.000 | 0.450 | 0.472 | position gradient vanishes |
| Seaquest | 0.357 | 0.000 | 0.714 | 0.479 | 0.413 | holds up on position |
| Berzerk | 0.352 | 0.695 | 0.010 | 0.481 | 0.260 | position gradient vanishes |
| Chopper Command | 0.343 | 0.000 | 0.687 | 0.452 | 0.400 | holds up on position |
| Hero | 0.334 | 0.136 | 0.532 | 0.417 | 0.280 | holds up on position |
| Carnival | 0.331 | 0.661 | 0.000 | 0.447 | 0.417 | position gradient vanishes |
| Venture | 0.226 | 0.451 | 0.000 | 0.474 | 0.500 | position gradient vanishes |
The path from this method's runner (main) into the bit-exact VCS substrate, and the
computation it involves. Every step links to the exact source on main. From
callstack_phaseB.json.
env_reset! / env_step! jutaribuild_shared_testbed jutarimasked_read_y -> intervene_ram! jutari intervene_ram! call at lime.jl:145 -> jutari_oracle.jl:174lime_sample runnerlime_weights runnerfit_weighted_linear runnersnapshot jutariScored against the exact intervention oracle Δy(u): run_intervention.
The figure is generated from the committed record by
docs/gen_method_figures.py; the game frame
and each RAM cell's screen footprint are produced by
render_scenes.jl /
cell_footprints.jl.