Perturbation family · fair shares from game theory
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
Three friends share a taxi and the fare is 30 euros. How should they split it fairly, if each lives
at a different distance? Game theory has a famous answer: the Shapley value. Imagine the
friends joining the ride one after another, in every possible order. Each time someone joins, note
how much the fare goes up. A person's fair share is the average increase they cause, over all
orders. Lloyd Shapley proved this is the only split that obeys a few fairness rules, for
example: the shares add up to the total, and two people who always contribute the same pay the same.
For a neural network, the “players” are the input features and the “total” is
the output minus a baseline output. A feature's Shapley value is its fair share of the prediction.
Unlike occlusion, which removes one feature at a time, Shapley values look at every
coalition (subset) of features, so backups and interactions are shared out correctly. The
catch: \(n\) features have \(2^n\) coalitions. KernelSHAP estimates the values from a random
sample of coalitions by solving one cleverly weighted linear regression.
How it works on a neural network
Let \(N\) be the set of \(n\) features and \(v(S)\) the model output when only the features in
\(S\) are present (the others replaced by a baseline). The Shapley value of feature \(i\) is
\[ \phi_i \;=\; \sum_{S \subseteq N\setminus\{i\}} \frac{|S|!\,(n-|S|-1)!}{n!}\,\big[v(S\cup\{i\}) - v(S)\big] , \]
the order-averaged marginal contribution. The values always satisfy efficiency:
\(\sum_i \phi_i = v(N) - v(\varnothing)\). Lundberg and Lee showed that the same \(\phi\) solves a
weighted least-squares problem over coalitions \(z\in\{0,1\}^n\):
\[ \min_{\phi}\; \sum_{z} \pi(z)\Big(v(z) - v(\varnothing) - \textstyle\sum_i z_i\phi_i\Big)^2
\quad\text{s.t.}\;\; \sum_i\phi_i = v(N)-v(\varnothing),\qquad
\pi(z) = \frac{n-1}{\binom{n}{|z|}\,|z|\,(n-|z|)} . \]
The Shapley kernel \(\pi\) puts most weight on very small and very large coalitions.
KernelSHAP samples coalitions instead of enumerating all \(2^n\), and solves this regression.
Toy example: exact Shapley values of a 3-player game. \(f(x) = 4x_1x_2 + 2x_3\) at
\(x = (1,1,1)\), baseline 0. The coalition values are \(v(\varnothing)=0\), \(v(1)=v(2)=0\),
\(v(3)=2\), \(v(12)=4\), \(v(13)=v(23)=2\), \(v(123)=6\). Walk through the 6 orders and record
what each player adds:
| order | \(x_1\) adds | \(x_2\) adds | \(x_3\) adds |
|---|
| 1,2,3 | 0 | 4 | 2 |
| 1,3,2 | 0 | 4 | 2 |
| 2,1,3 | 4 | 0 | 2 |
| 2,3,1 | 4 | 0 | 2 |
| 3,1,2 | 0 | 4 | 2 |
| 3,2,1 | 4 | 0 | 2 |
Averages: \(\phi = (2, 2, 2)\), and \(2+2+2 = 6 = v(123)-v(\varnothing)\). The product term
\(4x_1x_2\) is split evenly between its two players. Occlusion on the same toy gives \((4, 4, 2)\),
which sums to 10: it counts the shared term twice. With \(n = 3\) the kernel gives every
coalition of size 1 or 2 the same weight \(\pi = 1/3\), and the constrained regression over those
6 coalitions returns exactly \((2,2,2)\).
Recipe
- Choose the output \(y\), the features, and the “absent” baseline (a fixed value or a background dataset).
- Evaluate the two endpoints: all features present, \(v(N)\), and all absent, \(v(\varnothing)\).
- Sample coalitions \(z\): draw a size \(s\) with probability proportional to the kernel mass of that size, then a random subset of that size.
- Run the model once per distinct coalition (absent features set to the baseline), recording \(v(z)\).
- Solve the kernel-weighted least squares for \(\phi\) under the efficiency constraint \(\sum_i\phi_i = v(N)-v(\varnothing)\).
- Check convergence: re-solve with fewer coalitions and see whether \(\phi\) has settled.
From a neural network to the Atari
| The model \(f\) | The cartridge program on the bit-exact emulated Atari 2600 VCS (jutari). |
|---|
| The players (features) | The candidate RAM cells, de-duplicated (8 to 23 per core game). TIA and joystick causes are not players. |
|---|
| Feature absent / background | One fixed baseline: the cell is set to 0 with intervene_ram!. No background dataset is averaged over. |
|---|
| Value \(v(z)\) of a coalition | deepcopy the checkpoint, zero the absent cells, run 15 frames of the real ROM, read \(y\). No surrogate model of \(f\) is trained. |
|---|
| Sampling budget | 512 sampled coalitions plus the two endpoints; repeated draws are merged, so each distinct coalition costs one re-run. |
|---|
| “Ground-truth importance” | The oracle's single-cause |Δy| per cause, from real re-runs. |
|---|
How we apply it to the VCS
The value function is the real machine. In textbook SHAP, \(v(S)\) is often approximated
(e.g. by averaging over a background dataset). Here coalition_value computes it exactly:
copy the checkpoint, zero every absent candidate cell with intervene_ram!, play the
recorded 15 actions with env_step!, read the output. The only approximations left are
the coalition sampling and the additive form of the explanation.
- Endpoints. \(f_0 = v(\varnothing)\) (all candidate cells zeroed) and \(f_1 = v(N)\)
(intact) are each one real run.
- Sampling.
sample_coalitions draws 512 coalitions: a size \(s\in\{1,\dots,C-1\}\)
with probability \(\propto (C-1)/(s(C-s))\), then a uniform random subset of that size. Identical
draws are merged by dedup_coalitions; their kernel weights are summed.
- Solve.
kernelshap_solve solves the weighted least squares (tiny ridge
\(10^{-8}\)) and projects the answer onto \(\sum_i\phi_i = f_1 - f_0\) with a
Lagrange multiplier. The runner records the remaining completeness residual as a check.
- To causes. Each RAM cause gets \(|\phi|\) of its cell (the signed \(\phi\) are kept in the
record); TIA and joystick causes get 0.
- Convergence. The solve is repeated on the first \(N/8\), \(N/4\), \(N/2\) draws of the same
pool, so the record shows faithfulness versus compute at no extra re-runs.
An implementation detail worth knowing. The coalitions are drawn in proportion to the
kernel and then also weighted by the kernel \(\pi(s)\) in the solve. Textbook KernelSHAP does
one or the other, not both. Our estimate therefore leans even more on near-empty and near-full
coalitions (“only this cell kept”, “only this cell zeroed”) than exact Shapley
values would. Efficiency still holds exactly, by the constraint.
How is this different from the oracle? The oracle measures each cause alone at the
real state, in two directions (+17 and →0). Shapley values average a cell's effect over many
coalitions of other cells being zeroed, and split shared effects fairly. So when two cells form an
AND-like pair, the oracle (like occlusion) gives each one the full effect, while SHAP gives each half.
Agreement in ranking is what we score.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
kernelshap.jl:156 — The value function \(v(z)\): deepcopy, zero the absent cells, 15 × env_step!, read y. - XAI
kernelshap.jl:176 — The Shapley kernel \(\pi(s) = (C-1)/(\binom{C}{s}s(C-s))\); endpoints handled by the constraint. - XAI
kernelshap.jl:189 — Draws coalition sizes from the kernel's size distribution, then a uniform subset. - XAI
kernelshap.jl:256 — Merges repeated draws (one re-run each) and sums their kernel weights. - XAI
kernelshap.jl:230 — Weighted least squares plus the Lagrange projection onto \(\sum\phi = f_1-f_0\). - XAI
kernelshap.jl:368 — One experiment: oracle, endpoints, 512 coalitions, solve, scoring, convergence sweep. - substrate
jutari_oracle.jl:176 — The poke that makes a cell “absent” in the emulated RAM. - substrate
StellaEnvironment.jl:259 — One frame of the real machine; each coalition costs 15 of them. - substrate
oracle_intervene.jl:242 — The oracle's single-cause re-run, the ground truth the Shapley values are compared with. - substrate
shared_testbed_impl.jl:115 — The shared gameplay checkpoint and the position output.
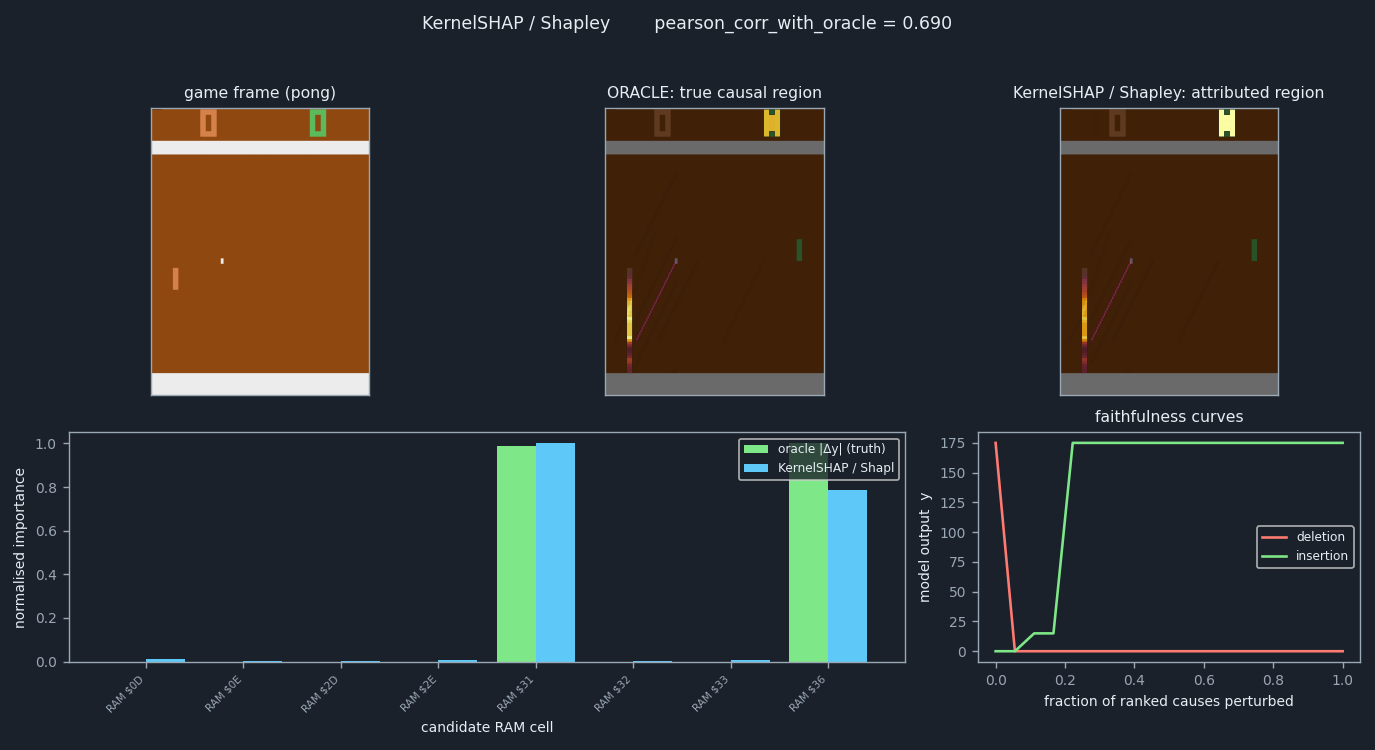
Reading the result
Bars are \(|\phi|\) per cause next to the oracle's true effect. TIA and joystick causes are zero
for SHAP by construction, and both causes of a byte share a height. Where the oracle shows two cells
with large, similar effects, SHAP may show them at about half height each: that is fair sharing, not
an error. Check the completeness residual (should be near zero) and the convergence block: if
agreement still changes between \(N/2\) and \(N\), more coalitions would help. Expect SHAP to recover
much of the true structure on both content and position outputs.
Pitfalls
- “Absent” must be defined. Shapley values depend completely on the baseline. Zero is one choice; a background dataset of real states would give different values.
- Fair share is not causal effect. Kumar et al. show Shapley values can credit features in ways that do not match the question you care about. Splitting an interaction in half is a convention, not a fact about the game.
- Sampling error. With many features, a few hundred coalitions cover a tiny fraction of the \(2^n\). Covert & Lee analyse the estimator's variance; we report a convergence sweep instead of assuming it has converged.
- Our weighting differs from the textbook. Drawing and weighting by the kernel both emphasise extreme coalitions, so our values are a Shapley-like estimate, not the exact Shapley values even at infinite budget.
- Off-distribution coalitions. Zeroing many cells creates machine states the game never reaches. The VCS runs them faithfully, but they may say little about normal play.
Try it yourself
julia --project=jutari tools/xai_study/phaseB_attribution/kernelshap.jl --games core
Writes kernelshap_<game>_{content,ball_pixel}.json/.npz into tools/xai_study/phaseB_attribution/out/, with the signed \(\phi\), the completeness residual and the convergence sweep. Change the budget with --n-coalitions.
Original papers & further reading
- Lundberg & Lee (2017). A Unified Approach to Interpreting Model Predictions. NeurIPS. — arxiv.org/abs/1705.07874
- Covert & Lee (2021). Improving KernelSHAP: Practical Shapley Value Estimation via Linear Regression. AISTATS. — arxiv.org/abs/2012.01536
- Kumar, Venkatasubramanian, Scheidegger & Friedler (2020). Problems with Shapley-value-based explanations as feature importance measures. ICML. — arxiv.org/abs/2002.11097
Read next: LIME · RISE · Occlusion · Integrated Gradients