Phase B · attribution / XAI

Occlusion

Zeiler & Fergus 2014

← back to the method catalogue

What it does?

Occlusion is the most direct attribution method. It hides part of the input, re-runs the system, and measures how much the output changes. A region whose removal changes the output a lot is judged important; a region whose removal does nothing is judged irrelevant. Sliding the occluder over the whole input produces an importance map. For images this means graying out a patch and watching the class score drop. The reason occlusion is powerful is that it is really a coarse intervention: it does not model sensitivity, it actually changes the input and observes the real response. We apply it to the VCS by setting each candidate cause, a RAM cell or register, to an occluded value, re-running the bit-exact program, and recording the change in the output. Because this is a genuine do-operation on the real machine, it tracks the intervention oracle closely, and it works even on a sprite's position where every gradient method fails. Its only weakness relative to the exact oracle is that it perturbs at the granularity of the occluder and can miss fine or joint effects. Occlusion is therefore the bridge between the gradient family and the truly causal methods, and it is among the most faithful attribution methods precisely because it perturbs the real system.

Occlusion result

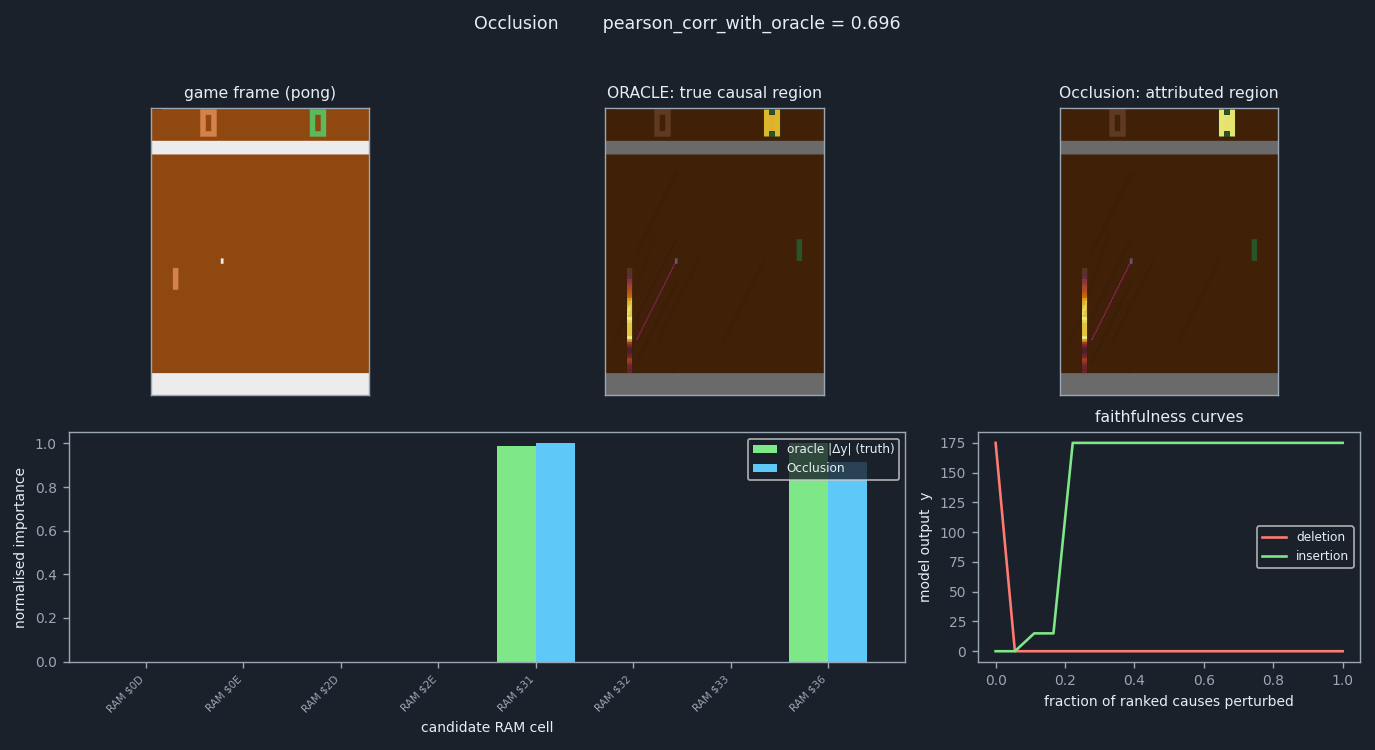
Top row (image domain, as in Paper 1): the game frame, then the oracle's true causal region and this method's attributed region — each painted onto the frame through the screen footprint of the RAM cells it implicates (brighter = more important). A faithful method's heat matches the oracle's. Bottom: per-cell importance — oracle (green) vs method (blue) — and the deletion/insertion faithfulness curves (perturb the ranked causes and watch the output move). Note: the image-domain overlay footprints are illustrative, computed on the pre-redesign boot frame; the bars, curves and all reported numbers come from the re-run records on the shared gameplay states. pearson_corr_with_oracle = 0.696 — this example only (pong, state f90+15); the audit aggregate is below.

Reading this example's causal region

This example explains the content of RAM $36 (byte 54) — the most causally-active concept byte at this state. Its strongest true-causes are: RAM $36 (the play area — ball / paddles); RAM $31 (17% of its footprint sits in the score band, the rest in the play area). The score digits appear in the region because RAM $31 reaches them: perturbing it over the 30-frame NOOP window changes the game outcome, and hence the score — a downstream effect, not direct rendering.

Perturbation family · the starting point

Learn the method — a beginner's guide

New to explainable AI? This block explains the method as it is used on neural networks, then how we run the very same method on an Atari 2600, where — unlike for a network — we know the right answer. Every implementation step links to the code. See also the XAI primer for the shared vocabulary.

The idea in plain words

A network looks at a photo and says “dog: 92 %”. Instead of asking calculus questions, you can simply cover part of the photo with a grey square and run the network again. If the dog score drops to 30 %, the covered patch mattered. If it stays at 92 %, it did not. Slide the square across the whole photo, write down the drop at every position, and you get a heat-map. That is occlusion: hide one part, re-run, measure the change.

Occlusion is a black-box method. It never opens the network. It needs no gradients and no weights, only the ability to feed in an input and read the output. That makes it slow (one full forward pass per patch) but very honest: it measures what the model actually does when a part is removed, not a local approximation of it. It is the simplest member of the perturbation family (RISE, LIME, KernelSHAP, extremal perturbation), which all work by changing the input and re-running the model.

How it works on a neural network

Write the network as \(y = f(x)\) with input \(x = (x_1,\dots,x_n)\). Pick a baseline value \(b\) that stands for “absent” (grey, black, zero, the dataset mean). Let \(x_{[i \leftarrow b]}\) be the input with part \(i\) replaced by the baseline. Occlusion gives part \(i\) the score

\[ O_i(x) \;=\; \big|\, f(x) - f(x_{[i \leftarrow b]}) \,\big| . \]

For images, “part \(i\)” is a square patch, and the square slides with some stride. The patch size and the baseline are both choices; the map changes when you change them. Cost: one forward pass for the intact input plus one per part.

Toy example 1 (it works). Let \(f(x_1,x_2,x_3) = 4x_1 + x_3\) at \(x = (1,1,1)\), baseline 0. Then \(f(x) = 5\). Occluding \(x_1\) gives 1 (score 4), occluding \(x_2\) gives 5 (score 0), occluding \(x_3\) gives 4 (score 1). The map \((4,0,1)\) is exactly right.

Toy example 2 (redundancy). Now let \(f = \max(x_1, x_2) + x_3\) at \(x=(1,1,1)\), so \(f(x)=2\). Occlude \(x_1\): \(\max(0,1)+1 = 2\), score 0. Occlude \(x_2\): also score 0. Occlude \(x_3\): score 1. Occlusion says \(x_1\) and \(x_2\) are irrelevant. Yet occluding both gives \(f = 1\): together they matter as much as \(x_3\). Each one is a backup for the other, and a one-at-a-time probe cannot see a backup. Remember this blind spot; KernelSHAP fixes it.

Recipe

  1. Choose the output \(y\) to explain and a baseline value that means “absent”.
  2. Run the model once on the intact input and record \(y(x)\).
  3. For each part \(i\): copy the input, set part \(i\) to the baseline, run the model, record \(y(x_{[i\leftarrow b]})\).
  4. Score part \(i\) by \(|y(x) - y(x_{[i\leftarrow b]})|\).
  5. Display the scores as a heat-map (or, here, as one bar per candidate cause).

From a neural network to the Atari

The trained network \(f\)The cartridge program running on the emulated Atari 2600 VCS (6507 CPU + TIA video chip + RIOT), bit-exact in jutari.
The input parts \(x_i\)The candidate causes at the intervention frame \(f^*\): RAM bytes the game uses (score, positions, …), one TIA colour register, and the joystick input.
Grey patch / baseline \(b\)Write 0 into the RAM byte or TIA register (occlude!). For the joystick cause, “absent” means “no extra action”: the recorded action stream is left unchanged.
One forward passRestore a deepcopy of the checkpoint, poke the value, and run the real ROM for the 15-frame horizon with env_step!.
The output \(y\)A content output (one RAM byte at \(f^*{+}15\)) or a position output (how many screen pixels differ from the un-intervened frame).
“Ground-truth importance”The intervention oracle: the same re-run machinery, but each RAM byte is probed twice (set to base+17, and set to 0), plus a TIA colour and a joystick do.

How we apply it to the VCS

On the VCS, occlusion is almost embarrassingly direct. The game is stopped at frame \(f^*\) (after 90 frames of seeded random play) and the machine is saved as a checkpoint. Then, for each candidate cause \(u\):

  1. deepcopy the checkpoint (a full copy of CPU, RAM, TIA and RIOT state);
  2. occlude! the cause: intervene_ram!(env, idx, 0) for a RAM byte, intervene_tia!(env, reg, 0) for a TIA register, nothing for the joystick;
  3. replay the same recorded 15 actions on the real ROM with env_step!;
  4. read \(y\) and store \(|y(\text{occluded}) - y(\text{intact})|\).

That is one real-emulator re-run per cause, plus one intact run. No surrogate, no gradient, no learned model. Because it only reads the output after a real run, it works just as well on the position output, where the VCS places sprites by timing and every gradient is exactly zero.

How is this different from the oracle? Occlusion is a coarse oracle. The oracle's cause list contains, for every candidate RAM byte, two interventions: ram[i]:set (base value + 17) and ram[i]:occlude (value 0). For the occlude-mode entries, occlusion runs exactly the same experiment as the oracle and gets exactly the same number. The disagreements come from the rest: occlusion gives the set entry of a byte the same score as its occlude twin (it only knows one direction, “to zero”); it sets the background-colour register to 0 where the oracle sets it to white; and it gives the joystick cause zero, because “absent” leaves the action stream untouched while the oracle forces a RIGHT press. So we expect a high but not perfect agreement, and that is what the runner checks (it asserts a positive correlation on the core games, never a perfect one).

The scoring then ranks causes by their occlusion score and runs deletion/insertion curves on the real machine: occlude the top-1, top-2, … causes together and watch \(y\) move.

Read the code

XAI the interpretability method   substrate the bit-exact emulator it runs on (jutari, Julia).

Reading the result

Each cause has two bars: the occlusion score and the oracle's true effect. Look at the pairs of :set / :occlude causes of the same byte. Occlusion always gives the twins the same height, while the oracle may not. The :occlude bars should match the oracle exactly. The joystick bar is zero for occlusion by construction. Expect the tallest bars to line up with the oracle on both the content and the position output. This is the clearest contrast with the gradient family, whose position-output maps are flat.

Pitfalls

Try it yourself

julia --project=jutari tools/xai_study/phaseB_attribution/occlusion.jl --games core

Writes occlusion_<game>_{content,position}.json/.npz into tools/xai_study/phaseB_attribution/out/. Cost per output: one intact run plus one re-run per cause, plus about twice that again for the deletion/insertion curves. Pass --game pong to run a single game.

Original papers & further reading

Read next: KernelSHAP / Shapley · RISE · Extremal / meaningful perturbation · Vanilla gradient (saliency)
How it's scored

The score is the Pearson correlation of the occlusion map with the oracle's exact causal map, reported raw, and the grading is always against the intervention oracle. Occlusion is itself a coarse intervention: we set each candidate cause to an occluded value, re-run the bit-exact program, and record the change in the output. Because that is a genuine do-operation on the real machine, its map tracks the oracle closely, and it is among the most faithful attribution methods. Crucially, there is no sprite-position collapse here. Where the gradient family scores zero on a discrete position output, occlusion still works, because perturbing and re-running does not depend on a derivative. So its position-regime faithfulness stays well above the gradient methods', and its all-regime faithfulness is the highest among the attribution methods. Its only shortfall relative to the exact oracle is granularity: it perturbs at the size of the occluder and can miss fine or joint effects that the oracle captures exactly. The audit box reports the measured all-regime faithfulness across the 44 scored games. Occlusion is the clearest attribution-side evidence that a method is faithful exactly when its mechanism is a valid intervention on the real system.

The score is measured against the §1 intervention oracle — never against another interpretability method. F (faithful) is always vs the oracle; see the execution stack. How each of F / S / M is actually computed for this method (and whether it matches the paper) is in the box just below; the numbers are in the In the audit box under it.

How F, S, M are computed here

The exact formula this method uses for each score, read from its runner, and whether it matches the paper's §3 (F ∧ S ∧ M triad) definition. From the committed audit fsm_math_phaseB.json.

AxisFormula (as computed) What it measuresMatches §3?
F
faithfulness
\(F = \rho_{\mathrm{Pearson}}\!\left(\mathrm{attr},\ |\Delta y(u)|\right)\)Raw Pearson correlation between the method's per-cause attribution magnitudes and the oracle's true absolute causal effects |Delta_y(u)|, scored separately for the content and position output regimes.✓ matches occlusion.jl: pr = pearson(occ_attr, odelta); triad_extra_dict(f.pearson, f.occ_attr, f.oracle_abs_delta). Record: out/occlusion_air_raid_content.json (value=0.79). Scorer pilot_ig_vs_oracle.jl pearson() (raw Statistics.cor, zero-variance->0); F = pearson(attr, oracle_abs_delta) where oracle_abs_delta = abs.(cmap.delta) (true |Delta_y| per cause). Also reports spearman, precision@k, deletion/insertion AUC (paper's auxiliary F metrics). Per-regime split: separate *_content.json and *_position.json records, each carrying its own extra.triad.{F,S,M}.
how it's measured — call stack:
  1. per-cause occlusion attribution — occlusion.jl:204
  2. raw Pearson of attribution vs oracle |Δy(u)| — pilot_ig_vs_oracle.jl:173
  3. assemble the F∧S∧M triad record — occlusion.jl:450
  4. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
S
sufficiency
\(S = \dfrac{\#\{\,u_{\mathrm{held}}:\ |\hat{y}-y|\le\varepsilon\,\}}{|\mathrm{held\text{-}out}|}\in[0,1]\)Fit Delta_y = a*attr + b on a calibration half of the do(u) causes, predict the disjoint held-out half, and report the fraction of held-out causes whose predicted output lands within an epsilon band of the oracle's bit-exact re-run.✓ matches common/triad_sm.jl sufficiency_score() (interleaved calib/held split by seed, least-squares 1-D fit Delta_y~a*attr+b on calib, epsilon = max(0.5, 0.10*heldout_spread)); assembled in triad_extra_dict(). The new §3 (sec:triad) admits the fraction-within-tolerance [0,1] special case of the held-out predictive test, which this held-out do(u) fit-then-predict estimator satisfies, so it matches. (Detail: epsilon is a self-scaled band 0.10*spread; the [-1,1] correlation form is available but this method reports the [0,1] hit fraction.)
how it's measured — call stack:
  1. sufficiency_score: fit Δy=a·attr+b on a calib half, predict held-out within ε — triad_sm.jl:111
  2. assemble the F∧S∧M triad record (calls sufficiency_score) — triad_sm.jl:173
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
M
minimality
\(M = |U^{\star}| / |\hat{U}| \in (0,1]\quad U^{\star}=\{u:\Delta y(u)>0\},\ \hat{U}=\{u:|\mathrm{attr}(u)|>\tau\}\)Ratio of the number of oracle causal movers (causes with nonzero true Delta_y) to the number of cells the method names above 1e-6 of its own max attribution; null when the oracle finds no mover or the method names nothing.✓ matches common/triad_sm.jl minimality_score() with name_frac=1e-6, mover_floor=0.0; the above-threshold named set is used (topk kept but not passed), see triad_extra_dict(). This is the paper's M = |U*|/|U_hat| in (0,1] (standardized everywhere), so it matches the new §3. (Detail: |U*| is taken as all oracle movers with Delta_y>0, an upper bound on the strictly-smallest reproducing subset, so M can be optimistic.)
how it's measured — call stack:
  1. minimality_score: |U*| oracle movers / |U_hat| named cells — triad_sm.jl:57
  2. assemble the triad record (calls minimality_score) — triad_sm.jl:178
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242

✓ matches = the same quantity as §3; ◐ partial = the same kind of estimator but a differing detail; ✗ does not match = a different quantity (see the note). Definitions: F = agreement with the oracle's true causal effects Δy(u); S = held-out predictive score in [−1, 1]; M = |U*|/|Û| (true-minimal-set size / named-set size).

In the audit

This is the method's entry in the actual cross-method audit — scored on the paper's correctness triad, each axis a mean over 44 of the 44 scored games (88 committed §R records), not the single example shown above. Tradition: intervention. The example figure (Pong) is one of those records.

0.685F — faithfulness vs oracle (mean over 44 games, ±0.062 CI95)
0.654S — sufficiency: held-out predictive (n/a where the paper does not define this axis)
0.972M — minimality: true-minimal-set / named-set (n/a otherwise)
88committed records aggregated
0.00human-plausibility proxy

F faithfulness (scored vs the oracle for every method) · S sufficiency (held-out predictive score in [−1, 1]; a negative value means the explanation predicts held-out interventions worse than the unperturbed baseline; reported for the predictive methods across all three phases where the calibration/held-out split is defined) · M minimality (true-minimal-set / named-set; where the method names a cause set) — n/a otherwise, per the paper's F ∧ S ∧ M triad.

Source: leaderboard.json · the whole leaderboard is on the methods page and the Paper 2 audit.

Results per game

This method's faithfulness on each of the 44 scored games (all-regime F, and the content vs position split). Click a header to sort. Every number is read from site_data.json (methods.occlusion.per_game).

GameF (all)content-Fposition-FSMNote
Enduro0.9931.0000.9870.8751.000recovers the true causes
Fishing Derby0.9580.9480.9680.9501.000recovers the true causes
Krull0.9501.0000.9010.9231.000recovers the true causes
Montezuma's Revenge0.9331.0000.8660.9381.000recovers the true causes
Space Invaders0.9191.0000.8380.9441.000recovers the true causes
Riverraid0.9161.0000.8320.9131.000recovers the true causes
Bowling0.8970.9330.8610.8811.000recovers the true causes
Name This Game0.8940.7881.0000.9171.000recovers the true causes
Alien0.8810.7790.9840.7861.000recovers the true causes
Boxing0.8470.8170.8770.7921.000holds up on position
Double Dunk0.8360.7970.8740.6151.000holds up on position
Demon Attack0.8280.9450.7120.9060.875
Ice Hockey0.8160.7670.8650.6820.875holds up on position
Freeway0.8130.7470.8790.6001.000holds up on position
Gopher0.8020.7760.8270.9291.000holds up on position
Frostbite0.7910.7240.8570.5001.000holds up on position
Bank Heist0.7880.9000.6760.8331.000
Phoenix0.7650.9090.6220.4621.000
Pacman0.7500.7760.7250.4441.000
Private Eye0.7480.7580.7390.9601.000
Pitfall0.7350.7520.7170.8820.875
Kung-Fu Master0.7270.7450.7100.8000.958
Jamesbond0.7240.7470.7000.8930.964
Atlantis0.7150.7780.6520.4000.875
Assault0.7040.7100.6990.9050.917
Skiing0.6950.8100.5810.4501.000
Q*bert0.6930.9990.3870.5001.000
Air Raid0.6780.6560.6990.7860.917holds up on position
Pong0.6410.6960.5860.3890.875
Breakout0.6170.7500.4830.5501.000
Ms. Pac-Man0.6060.8100.4010.4751.000
Video Pinball0.5290.7700.2870.5001.000
Tennis0.5001.0000.0000.5001.000position gradient vanishes
Kangaroo0.5000.9990.0000.5001.000position gradient vanishes
Carnival0.4990.9990.0000.5261.000position gradient vanishes
Road Runner0.4750.0000.9510.5001.000holds up on position
Asterix0.4630.4330.4920.1501.000
Centipede0.4250.8510.0000.4500.875position gradient vanishes
Yars' Revenge0.4050.7710.0400.4641.000
Venture0.3720.7430.0000.4741.000position gradient vanishes
Seaquest0.3570.0000.7140.4791.000holds up on position
Berzerk0.3470.6940.0010.4810.833position gradient vanishes
Chopper Command0.3450.0000.6900.4521.000holds up on position
Hero0.2680.0000.5360.4171.000holds up on position

Call stack — how it runs on jutari / jaxtari

The path from this method's runner (main) into the bit-exact VCS substrate, and the computation it involves. Every step links to the exact source on main. From callstack_phaseB.json.

Applied on the substrate

  1. env reset + per-frame step of the bit-exact VCS (the masked re-runs step the horizon here) — env_reset! / env_step! jutari
  2. shared gameplay-state testbed — build_shared_testbed jutari

The computation (intervention path)

  1. occlusion attribution: for each cause, occlude to baseline, step the horizon, read the |screen/output delta| vs intact — occlusion_attr runner
  2. the intervention operator: set the masked cause to its baseline (RAM cell / TIA reg -> 0, joystick -> NOOP) — occlude! -> intervene_ram! / intervene_tia! jutari intervene_ram! jutari_oracle.jl:174, intervene_tia! jutari_oracle.jl:185
  3. snapshot the RAM+screen (byte-exact) after the re-run to read the output — snapshot jutari

Scored against the exact intervention oracle Δy(u): run_intervention.

Implementation
tools/xai_study/phaseB_attribution/occlusion.jl
Reference
Zeiler & Fergus 2014
Record
occlusion_pong_content.json
All records
phaseB_attribution/out

The figure is generated from the committed record by docs/gen_method_figures.py; the game frame and each RAM cell's screen footprint are produced by render_scenes.jl / cell_footprints.jl.