Gradient family · the starting point
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
Imagine a network that looks at a photo and says “dog: 92 %”. You want to know
which pixels it looked at. The simplest question you can ask is: if I change this one
pixel a tiny bit, how much does the dog score move? A pixel whose small change moves the score
a lot is a pixel the network is sensitive to. Ask that question for every pixel at once and
paint the answers as a heat-map: that picture is the saliency map.
The “how much does the output move per tiny change of the input” number has a name
from calculus: the partial derivative. Collected over all inputs it is the
gradient. Deep-learning frameworks already compute gradients for training (that is what
backpropagation does), so a saliency map costs just one backward pass. That is why it is
the first attribution method everyone learns, and the baseline every other gradient method
(Grad×Input, SmoothGrad, Integrated Gradients, …) tries to improve.
How it works on a neural network
Write the network as a function \(y = f(x)\): the input \(x = (x_1,\dots,x_n)\) is e.g. the
pixel vector, the output \(y\) is one scalar (the logit of the class you care about). Saliency
assigns input \(i\) the score
\[ S_i(x) \;=\; \left|\,\frac{\partial f}{\partial x_i}(x)\,\right| . \]
The derivative is evaluated at the actual input \(x\). It is a local, first-order
statement: it says how \(f\) behaves for infinitesimally small changes around \(x\), via the Taylor
approximation \(f(x+\delta) \approx f(x) + \nabla f(x)\cdot\delta\). Nothing more.
Toy example. Let \(f(x_1,x_2) = 3x_1 + x_2^2\) at \(x = (1, 0)\). Then
\(\partial f/\partial x_1 = 3\) and \(\partial f/\partial x_2 = 2x_2 = 0\). Saliency says
“only \(x_1\) matters”. Yet setting \(x_2 = 5\) changes the output by 25, far more than
any reasonable change of \(x_1\). The gradient is blind to \(x_2\) because, at this point, the
curve is flat in that direction. Keep this example in mind: it is exactly what happens on the
Atari.
Recipe
- Pick the input \(x\) you want explained and the scalar output \(y\) (one logit, one pixel, one RAM byte).
- Run the forward pass and record it on an autodiff tape (PyTorch
requires_grad, JAX grad, Julia Zygote.gradient). - Run one backward pass from \(y\): this yields \(\partial y/\partial x_i\) for every input \(i\) at once.
- Take the absolute value (sign is usually dropped) and display it as a heat-map over the inputs.
From a neural network to the Atari
| The trained network \(f\) | The game cartridge's program (the ROM), run by the 6507 CPU, together with the TIA video chip and RIOT timer: the whole Atari 2600 VCS, emulated bit-exactly by jutari. |
|---|
| The input \(x\) | The machine's internal state at the intervention frame \(f^*\): the 128 bytes of RAM (plus registers). This is the “activation vector” we explain. |
|---|
| The output \(y\) | Two outputs per game: a content output (the value of one candidate RAM byte, the one the oracle finds most causally active) and a position output (how many screen pixels differ from the un-intervened frame 15 frames later). |
|---|
| Backpropagation | The differentiable SOFT path of jutari (JuTari.Diff): the same computation, written so Julia's Zygote can differentiate it. Its forward pass is bit-identical to the real machine (Theorem 1 of Paper 1). |
|---|
| “Ground-truth importance” | Something you never have for a real network. Here we do: the intervention oracle sets each candidate cause to a new value, re-runs the real ROM, and measures how much \(y\) actually changed: \(|\Delta y(u)|\). |
|---|
How we apply it to the VCS
On a neural net we never know whether a saliency map is right. On the VCS we do, because
we can simply re-run the machine. The experiment therefore has two halves:
- The method. We stop the game at frame \(f^*\) (after 90 frames of seeded random play), take
the RAM vector there and compute \(|\partial y/\partial \mathrm{ram}_u|\) with Zygote through the
differentiable read of the output. Each candidate cause \(u\) (a RAM byte the game is known to
use for a score, a position, …) gets that number as its attribution; the oracle's one TIA colour
register and joystick cause, which the RAM gradient cannot see, get 0.
- The truth. For every cause \(u\) we poke a new value into the real emulator, play the same
15 frames, and measure the true effect \(|\Delta y(u)|\). That is 1 re-run per cause, no
approximations.
The score is how well the two agree: Pearson / Spearman correlation, precision@3 (are the top-3
causes the same?) and deletion/insertion curves run on the real machine.
Content output. \(y\) is a RAM byte read through soft_ram_peek, a
one-hot dot product \(y = e_{\text{idx}}\cdot \mathrm{ram}\). Its gradient is exactly the one-hot
vector \(e_{\text{idx}}\): saliency points at the byte itself and nothing else. That is
correct for “which byte holds the score”, but it says nothing about which other
bytes will change the score over the next 15 frames.
Position output. This is the toy example's \(x_2\) for real. The VCS places a sprite
by when the program writes a strobe register during the scanline: a discrete event. Moving
the position byte by 0.001 moves the sprite by zero pixels, so the honest derivative is
exactly zero everywhere: the vanishing gradient. We report that naive zero and, side by
side, a gradient through a bilinear sampler that draws the sprite at a continuous column.
This is the same trick spatial-transformer networks use, and it restores a non-zero gradient.
The end-to-end arm. The two reads above differentiate one line of code at \(f^*\). The
e2e_gradient.jl runner instead differentiates the content byte at \(f^*{+}15\)
back through every CPU instruction of the 15 frames (about 105 instructions,
checkpointed every 200). That is the analogue of backpropagating through a very deep, very
discrete network. The renderer (TIA) is still not differentiated.
What it found (all 44 scored games, forward pass bit-exact in every one, 8–23 hours
of backward pass per game on one core). On most games the answer is the same map as the one-line read.
On the content byte the per-cause map is unchanged in 35 of the 44 games, and in the position output in
35 as well. The six core games show the patterns one by one:
- Content: in five games the gradient through 65 000–81 000 instructions is
exactly the one-hot vector \(e_{\text{idx}}\) again (\(\lVert g\rVert_1 = 1\), one non-zero
entry), so its scores equal the one-line read's to the last digit (Breakout 0.750, Space Invaders 1.000,
Seaquest 0.017, Ms. Pac-Man 0.811, Q*bert 0.999). The byte simply persists or is incremented.
Every other way the oracle's causes reach it goes through a branch (“if the ball hit the
paddle…”), an indexed load or a hardware read, and none of those carries a gradient.
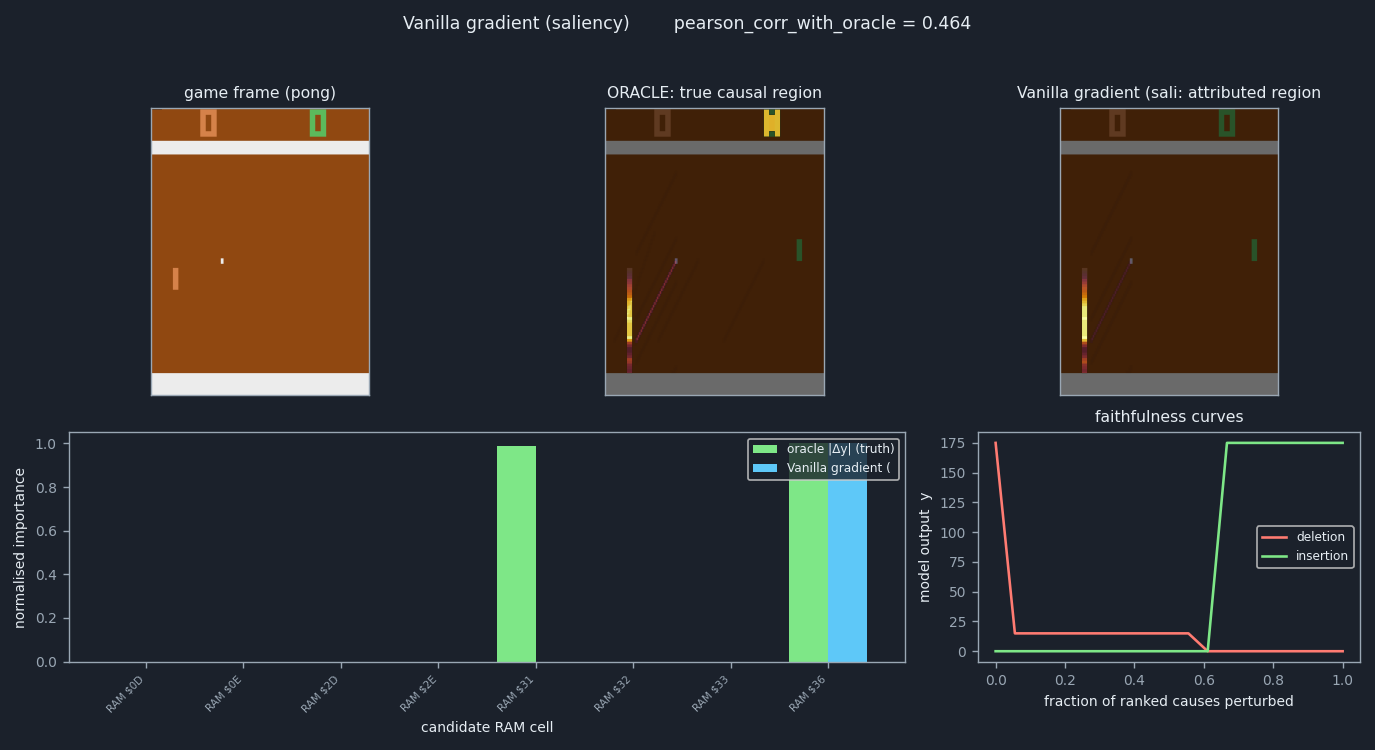
- Pong, the instructive exception: the gradient also lands on RAM[56] with
\(\partial y/\partial \mathrm{ram}_{56} = 15\), the horizon length. That is the signature of a
velocity being added to a position once per frame: \(x_{t+15} = x_t + 15\,v\), so
\(\partial x_{t+15}/\partial v = 15\). Backpropagation through time has discovered the game's
physics. RAM[56] is not among the candidate causes, though, so the scores again equal the one-line
read's (0.464), and the oracle's strongest cause still gets zero. Atlantis shows the same signature.
- Position: in Breakout and Space Invaders the gradient arriving at \(f^*\) is
exactly zero, although the sampler's gradient at \(f^*{+}15\) is non-zero (checked). Breakout
recomputes its paddle position every frame from the paddle controller, a hardware input the gradient
treats as a constant. The vanishing gradient, measured.
- Across all games: the gradient vanishes completely on 8 games' content byte and on 8 games'
position output. Three games lose a good content score that way (Enduro 1.000 to 0, Phoenix 0.909 to 0,
Air Raid 0.360 to 0). One game gains: in Centipede the content byte at \(f^*{+}15\) is carried over
from RAM[111] at \(f^*\), the oracle's strongest cause, and the score jumps from −0.10 to 0.85.
On average the deep gradient is slightly less faithful than the one-line read (content 0.631 to
0.598, position 0.092 to 0.086).
The lesson for neural networks: a deeper, more “honest” gradient is not automatically a
more faithful explanation. Through a computation made of decisions rather than smooth arithmetic,
backpropagation sees only the smooth sliver.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
saliency.jl:334 — The method itself, in four lines: abs.(Zygote.gradient(readf, ram)). - XAI
saliency.jl:316 — The differentiable content output: a one-hot read of RAM byte idx. - XAI
saliency.jl:325 — The naive position output: no differentiable path exists, so the gradient is identically zero. - XAI
shared_testbed_impl.jl:357 — The bilinear sampler that gives the position output a non-zero gradient. - XAI
saliency.jl:395 — One experiment: oracle → saliency → correlation / precision@k → deletion/insertion on the real VCS → positive control. - substrate
SoftStep.jl:106 — The differentiable RAM read the gradient flows through (forward value exact, gradient one-hot). - substrate
StellaEnvironment.jl:259 — One video frame of the real, bit-exact machine (used by the oracle and the deletion curves). - substrate
oracle_intervene.jl:242 — The ground truth: poke a cause, re-run the ROM, read the output. - XAI
e2e_gradient.jl:165 — The true end-to-end gradient: checkpointed reverse mode through every instruction of the horizon. - substrate
SoftSystem.jl:79 — One differentiable CPU instruction on the full machine (TIA/RIOT reads replayed as constants).
Reading the result
In the figure, the bars are saliency per cause and the dots/bars beside them are the oracle's true
effect. A faithful method puts its tall bars where the oracle's tall bars are. For the
content output you will see one spike, at the byte that is the output. For the
naive position output you will see nothing at all, because the gradient is zero. With the
sampler you see a single spike at the position byte. The oracle, meanwhile, usually lights up several
causes: the gradient is local, the oracle is global.
Pitfalls
- Local is not global. A gradient describes an infinitesimal neighbourhood. Real interventions are finite (here: set a byte to a new value), and on a discrete machine the two can disagree completely.
- Vanishing / zero gradients wherever the computation is piecewise constant (thresholds, comparisons, table look-ups, sprite positioning by timing). ReLU networks have the same problem in their flat regions; the VCS has it everywhere.
- Saturation. If a byte is already at a value where the output no longer responds (think of a saturated sigmoid), its gradient is ~0 even though it matters a lot.
- Visual plausibility is not faithfulness. Adebayo et al. showed saliency maps can look sensible even for a network with randomised weights. Here we never judge a map by looks: every score is against the oracle.
Try it yourself
julia --project=jutari tools/xai_study/phaseB_attribution/saliency.jl --games core
Writes saliency_<game>_{content,position}.json/.npz into tools/xai_study/phaseB_attribution/out/. For the end-to-end variant run e2e_gradient.jl --game pong (8–23 hours per game on one CPU core; records e2e_{saliency,gradxinput}_<game>_* and e2e_core_summary.json).
Original papers & further reading
- Simonyan, Vedaldi & Zisserman (2014). Deep Inside Convolutional Networks: Visualising Image Classification Models and Saliency Maps. ICLR workshop. — arxiv.org/abs/1312.6034
- Adebayo et al. (2018). Sanity Checks for Saliency Maps. NeurIPS. — arxiv.org/abs/1810.03292
Read next: Grad×Input / DeepLIFT · SmoothGrad · Integrated Gradients · Occlusion