Gradient family · saliency averaged over noise
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
Vanilla saliency maps of image networks look speckled. Neighbouring pixels get wildly different
values. Smilkov et al. argued that this is not what the network “thinks”. It is because
the gradient of a deep ReLU network jumps around from point to point: move the input a hair and
the gradient changes a lot. The map is accurate for that exact point, but noisy as a summary.
SmoothGrad fixes the look with a simple trick: make many copies of the input, add a little
random noise to each, compute the saliency map of every copy, and average them. The random
jumps cancel out; what is consistently there survives. In the authors' words, it removes noise by
adding noise. It works as a wrapper around any gradient method. The catch is in the word
look. Smoothing makes maps cleaner to the eye, and whether it makes them more faithful
is a separate question. On the VCS we can answer that question exactly.
How it works on a neural network
With \(y = f(x)\) as in vanilla saliency, SmoothGrad averages the gradient over Gaussian
(normal-distribution) noise of standard deviation \(\sigma\):
\[ \mathrm{SG}_i(x) \;=\; \frac{1}{N}\sum_{k=1}^{N}
\left|\frac{\partial f}{\partial x_i}\big(x + \varepsilon_k\big)\right|,
\qquad \varepsilon_k \sim \mathcal{N}(0, \sigma^2 I). \]
This is a Monte Carlo estimate (an average over random samples) of the expected gradient
in a fuzzy neighbourhood of \(x\). Smilkov et al. recommend \(\sigma\) at 10–20 % of the
input range and \(N\) around 50. Some variants average the signed gradient; ours averages
absolute values.
Toy example: smoothing can wake up a dead gradient… Take a single ReLU,
\(f(x) = \max(0, x)\), at \(x = -0.1\). The vanilla gradient is 0: saliency says the input
does not matter. Now draw \(N = 4\) noise values \(\varepsilon = (-0.8, 0.3, 1.2, -0.2)\). The noisy inputs are
\((-0.9, 0.2, 1.1, -0.3)\), with gradients \((0, 1, 1, 0)\). SmoothGrad gives \(0.5\). With many samples and
\(\sigma = 1\) it converges to \(P(x + \varepsilon > 0) \approx 0.46\). Because the kink is within
reach of the noise, some samples land where the slope is non-zero.
…but not a flat one. Now take a step, \(f(x) = \mathbb{1}[x > 0]\). Its derivative
is 0 on both sides of the jump. Every noisy sample also has gradient 0, and the average of zeros is
zero. And for a straight line, \(f(x) = 3x\), every sample has gradient 3: smoothing changes
nothing. Remember both cases: the VCS gives us exactly these two.
Recipe
- Choose the noise level \(\sigma\) (relative to the input range) and the sample count \(N\).
- Draw \(N\) noise vectors \(\varepsilon_k \sim \mathcal{N}(0, \sigma^2 I)\), one value per input.
- For each noisy copy \(x + \varepsilon_k\), run one forward and one backward pass and take \(|\partial y/\partial x_i|\).
- Average the \(N\) maps. Optionally also keep the noise-free map for comparison.
- Display the averaged map. Cost: \(N\) backward passes instead of one.
From a neural network to the Atari
| The network \(f\) | The Atari 2600 VCS running the ROM, emulated bit-exactly by jutari; its differentiable twin is JuTari.Diff. |
|---|
| The input \(x\) | The 128 RAM bytes at the intervention frame \(f^*\) (after 90 frames of seeded random play). |
|---|
| Input noise | Gaussian noise with \(\sigma = 8\) raw byte units (about 3 % of the 0–255 range) added to every RAM byte, \(N = 50\) copies, fixed seed. |
|---|
| The output \(y\) | A content output (one RAM byte read one-hot) and a position output (screen pixels changed versus the un-intervened frame, made differentiable by the bilinear sampler). |
|---|
| “Is the smoothed map right?” | The intervention oracle: poke each cause, re-run the real ROM, measure \(|\Delta y|\). |
|---|
How we apply it to the VCS
The runner computes \(\mathrm{SG}(u) = \frac1N\sum_k |\partial y/\partial u|_{u+\varepsilon_k}\) over
the RAM vector \(u\) with Zygote, and returns the noise-free vanilla \(|\partial y/\partial u|\) next to it.
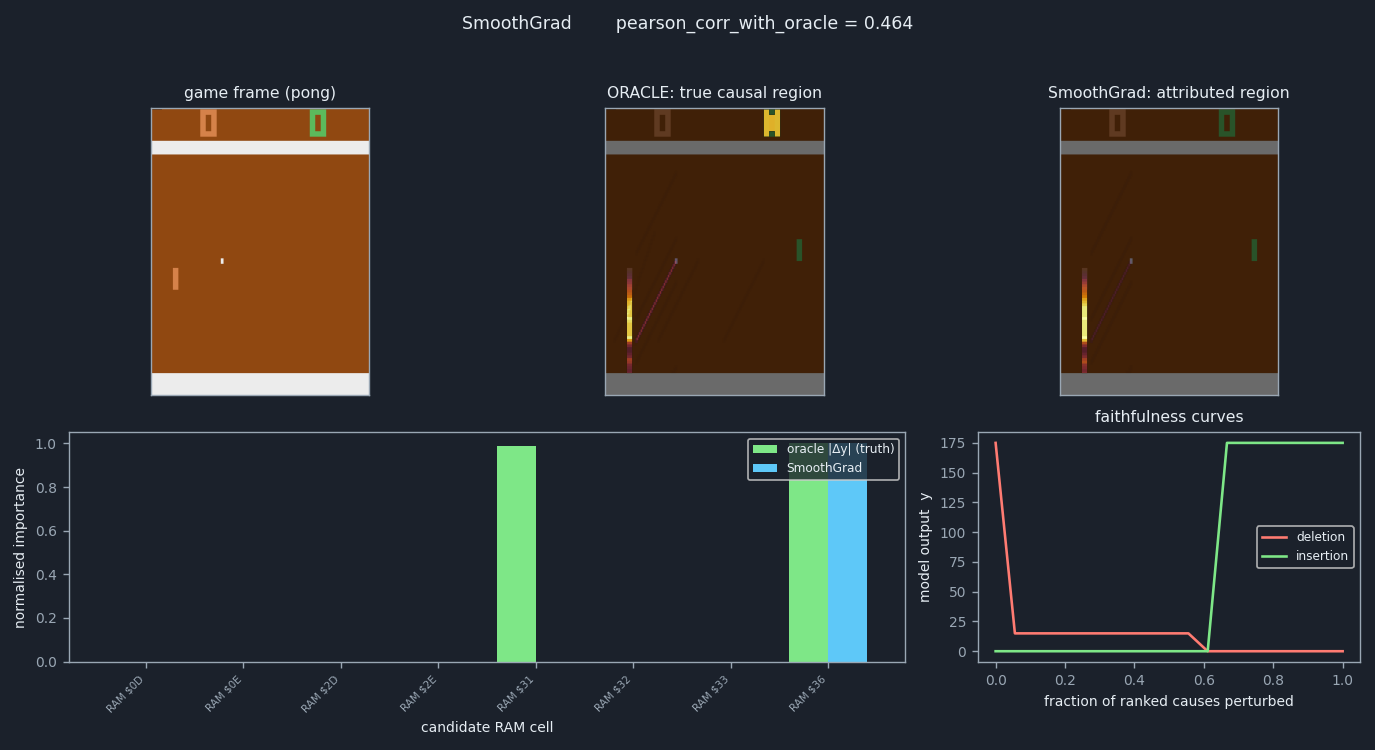
Both are scored against the oracle, so the effect of smoothing on faithfulness is measured
directly, not just its effect on looks.
- Noisy RAM is never executed. A noisy copy holds values like 117.4 or −3.1, which no real
RAM byte can take. That is fine here because the gradient is evaluated only on the differentiable
read of the output, not on the machine. The real VCS only ever sees integer pokes made by the
oracle and the deletion/insertion curves.
- Content output = the straight line. \(y\) is
soft_ram_peek(ram, idx), a linear
one-hot read. Its gradient is \(e_{\text{idx}}\) at every input, noisy or not. So SmoothGrad returns
exactly the vanilla map. The runner's --sigma-sweep option confirms this over five
\((\sigma, N)\) settings, from \((0, 1)\) to \((32, 100)\): the content-path correlation does not
move. The byte idx is the candidate the oracle shows to be most causally active.
- Naive position output = the step. The honest position gradient is zero everywhere (sprites are
placed by strobe timing). Averaging 50 zeros gives zero. Noise cannot manufacture a gradient the
machine does not have.
- Sampler position output = the ReLU case. The bilinear sampler draws the sprite at a continuous
column driven by one RAM byte, using a triangular kernel one pixel wide. Noise of 8 byte units
moves that column by several pixels, so many samples land where the kernel is flat or the
occupancy is clamped. The averaged gradient can therefore be weaker than the un-smoothed one, and
sometimes nearly zero. The runner records the raw sampler gradient and the smoothed one side by
side, and treats a smoothed-away gradient as an honest smoothing effect, not as a vanishing.
- Scoring follows the shared contract: correlation and precision@3 against the oracle,
deletion/insertion curves on the real ROM, and an oracle-vs-itself positive control.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
smoothgrad.jl:327 — The method: average \(|\nabla|\) over \(N\) noisy RAM copies; also returns the noise-free map. - XAI
smoothgrad.jl:334 — The noise: \(\sigma\) in raw byte units, one Gaussian draw per RAM byte, seeded. - XAI
smoothgrad.jl:814 — Robustness grid over \(\sigma\) and \(N\): does smoothing change faithfulness, or only looks? - XAI
smoothgrad.jl:394 — Picks the content byte the oracle shows to be most causally active. - XAI
smoothgrad.jl:493 — One game: shared testbed → content and sampler-position outputs → naive vs sampler side by side. - substrate
SoftStep.jl:106 — The linear one-hot RAM read: its gradient is the same at every noisy input. - substrate
shared_testbed_impl.jl:357 — The bilinear sampler for the position output, clamped to \([0,1]\). - substrate
shared_testbed_impl.jl:67 — The one-pixel triangular kernel: flat outside \(|t|<1\), which is why large noise smooths its slope away. - substrate
oracle_intervene.jl:242 — The ground truth: poke a cause, re-run the real ROM, read the output. - substrate
StellaEnvironment.jl:259 — One frame of the bit-exact machine, used by the oracle and the deletion/insertion curves.
Reading the result
Put this page next to vanilla saliency. On the content output the two maps are the same, and
so is their agreement with the oracle: a single spike at the read byte, against an oracle that
usually lights up several causes. On the position output, the smoothed sampler map is often
fainter than the raw sampler map, and its agreement with the oracle stays weak. The lesson is
general. SmoothGrad changes how a map looks, but here it does not change how faithful the map is.
It cannot add causal information the gradient never carried.
Pitfalls
- Denoising is not faithfulness. A cleaner map can be exactly as wrong as the noisy one. Hooker et al. found that SmoothGrad did not beat a random ranking under retraining-based evaluation (ROAR).
- Averaging zeros gives zero. Where the function is flat over the whole noise neighbourhood (a step, a table look-up, sprite timing), SmoothGrad stays blind.
- \(\sigma\) is a free knob. Too small and nothing is smoothed; too large and the map describes a different region of input space. On the VCS, 8 byte units already moves a sprite by several pixels.
- Off-distribution inputs. Noisy copies are not valid inputs (non-integer, possibly negative bytes; for images, grainy photos). The method explains the model on inputs it would never see.
Try it yourself
julia --project=jutari tools/xai_study/phaseB_attribution/smoothgrad.jl --games core
Writes smoothgrad_<game>_{content,ball_pixel}.json/.npz and smoothgrad_core_summary.json into tools/xai_study/phaseB_attribution/out/. Defaults: --sigma 8 --n-samples 50. Add --sigma-sweep to reproduce the \(\sigma/N\) robustness grid (it re-runs every game per grid point).
Original papers & further reading
- Smilkov, Thorat, Kim, Viégas & Wattenberg (2017). SmoothGrad: removing noise by adding noise. ICML workshop. — arxiv.org/abs/1706.03825
- Hooker, Erhan, Kindermans & Kim (2019). A Benchmark for Interpretability Methods in Deep Neural Networks (ROAR). NeurIPS. — arxiv.org/abs/1806.10758
Read next: Vanilla gradient (saliency) · Integrated Gradients · Guided Backprop · RISE