Phase B · attribution / XAI

Expected Gradients

Erion et al. 2021 (NMI)

← back to the method catalogue

What it does?

Expected Gradients removes the single-baseline choice from Integrated Gradients by averaging over many baselines. Instead of one reference, it draws references from a distribution of real states and averages the integrated-gradient attribution across them. This makes the result stable: it no longer depends on one arbitrary baseline, and the attributions are provably consistent across reference draws. The method was introduced to fix the perennial worry that Integrated Gradients can be gamed by picking a convenient baseline. We apply it to the VCS by averaging integrated gradients over a pool of recorded machine states. The result is very stable but not more accurate. Each integrated-gradient term contains the factor input-minus-baseline. When the reference pool holds bytes that are constant across states, that factor is zero and the attribution collapses. Even on a varied gameplay reference pool, and with the sampler restoring a position gradient, the method carries almost no true causal signal, and on a sprite's position it still vanishes for the usual reason. It is the clearest case in the study of a method that is more careful and more expensive, yet buys stability without buying faithfulness. That trade-off is exactly what makes it worth measuring here.

Expected Gradients result

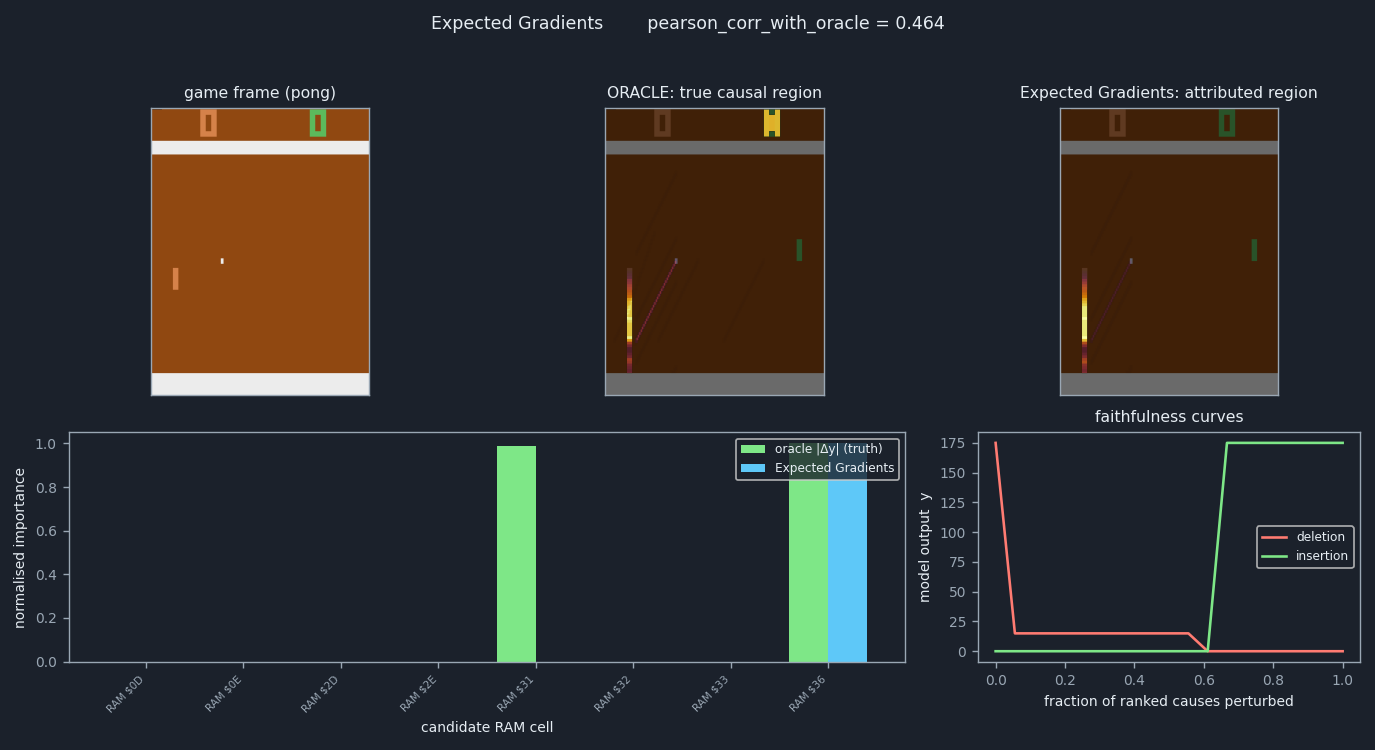
Top row (image domain, as in Paper 1): the game frame, then the oracle's true causal region and this method's attributed region — each painted onto the frame through the screen footprint of the RAM cells it implicates (brighter = more important). A faithful method's heat matches the oracle's. Bottom: per-cell importance — oracle (green) vs method (blue) — and the deletion/insertion faithfulness curves (perturb the ranked causes and watch the output move). Note: the image-domain overlay footprints are illustrative, computed on the pre-redesign boot frame; the bars, curves and all reported numbers come from the re-run records on the shared gameplay states. pearson_corr_with_oracle = 0.464 — this example only (pong, state f90+15); the audit aggregate is below.

Reading this example's causal region

This example explains the content of RAM $36 (byte 54) — the most causally-active concept byte at this state. Its strongest true-causes are: RAM $36 (the play area — ball / paddles); RAM $31 (17% of its footprint sits in the score band, the rest in the play area). The score digits appear in the region because RAM $31 reaches them: perturbing it over the 30-frame NOOP window changes the game outcome, and hence the score — a downstream effect, not direct rendering.

Gradient family · Integrated Gradients averaged over baselines

Learn the method — a beginner's guide

New to explainable AI? This block explains the method as it is used on neural networks, then how we run the very same method on an Atari 2600, where — unlike for a network — we know the right answer. Every implementation step links to the code. See also the XAI primer for the shared vocabulary.

The idea in plain words

Integrated Gradients (IG) needs a baseline, an input that means “nothing”. As the IG guide showed, the answer depends heavily on that choice: a black image, a blurred image and random noise each give a different map. There is rarely a single right “nothing”.

Expected Gradients (EG) sidesteps the choice. Instead of one hand-picked baseline it uses a whole reference distribution: a pool of real inputs, for example images from the training set. It runs IG from many randomly drawn references and averages the results. The attribution then answers “how does this input differ from a typical input, and which features carry the difference?” This links EG to Shapley values from game theory, which also average a feature's contribution over many reference situations. EG is stable and keeps completeness in expectation. But stable does not mean faithful, and averaging differences can cancel them.

How it works on a neural network

With \(y = f(x)\) and a reference distribution \(D\), EG assigns input \(i\) the expected value (average) of the IG integrand over references \(x'\) and path positions \(\alpha\):

\[ \mathrm{EG}_i(x) \;=\; \mathbb{E}_{x' \sim D,\;\alpha \sim U(0,1)} \Big[(x_i - x'_i)\,\frac{\partial f}{\partial x_i}\big(x' + \alpha(x - x')\big)\Big]. \]

Erion et al. estimate it by Monte Carlo integration: draw \(M\) pairs \((x'^{(m)}, \alpha_m)\), one gradient each, and average. There is no inner Riemann sum; the random \(\alpha\) does the path integral. Summing over \(i\) gives completeness in expectation: \(\sum_i \mathrm{EG}_i = f(x) - \mathbb{E}_{x'}[f(x')]\).

Toy example: averaging over baselines. \(f(x_1, x_2) = x_1 x_2\) at \(x = (2, 3)\), with \(D = \{(0,0),\,(2,0)\}\), each drawn half the time. From the IG guide: IG from \((0,0)\) is \((3, 3)\); IG from \((2,0)\) is \((0, 6)\). EG is the average, \((1.5,\ 4.5)\). Check: \(1.5 + 4.5 = 6 = f(x) - \tfrac12\big(f(0,0) + f(2,0)\big) = 6 - 0\). The baseline choice is no longer a single arbitrary pick, but the result now depends on the pool \(D\).

Toy example: cancellation. Let \(f(x) = x\) at \(x = 3\), with references \(\{1, 5\}\). The two IG terms are \(3 - 1 = 2\) and \(3 - 5 = -2\). EG \(= 0\). Yet \(f\) depends on \(x\) one-for-one. EG measures how far \(x\) is from the average reference. An input sitting at the typical value gets no credit, however much the output depends on it.

Recipe

  1. Build a reference pool \(D\) of real inputs (on a network: training examples).
  2. Draw \(M\) references \(x'^{(m)}\) from \(D\) (with replacement) and one \(\alpha_m \sim U(0,1)\) for each.
  3. For each pair, form \(x' + \alpha (x - x')\), run one backward pass, and multiply the gradient by \((x - x')\).
  4. Average the \(M\) products: that is the EG attribution.
  5. Optionally check completeness against \(f(x) - \overline{f(x')}\), and repeat with other seeds to measure stability.

From a neural network to the Atari

The network \(f\)The Atari 2600 VCS running the ROM, emulated bit-exactly by jutari; its differentiable twin is JuTari.Diff.
The input \(x\)The 128 RAM bytes at the intervention frame \(f^*\) (frame 90 of seeded random play).
The reference distribution \(D\)The 90 genuine RAM states at frames 1–90 of the same seeded gameplay run: every row is a reachable machine state.
Monte Carlo samples\(M = 64\) (reference, \(\alpha\)) draws per run, five independent seeds for the stability estimate.
The output \(y\)A content output (one RAM byte read one-hot) and a position output (screen pixels changed versus the un-intervened frame, made differentiable by the bilinear sampler).
“Is the attribution right?”The intervention oracle: poke each cause, re-run the real ROM, measure \(|\Delta y|\).

How we apply it to the VCS

The runner implements Erion's single-\(\alpha\)-per-reference estimator over the RAM vector: 64 draws per run, each a uniformly sampled row of \(D\) and a uniform \(\alpha\). It repeats this with five seeds, reports the mean pairwise cosine similarity between the seeds' maps (stability), and also scores single-baseline IG with the zeros baseline on the same output for a head-to-head comparison.

Read the code

XAI the interpretability method   substrate the bit-exact emulator it runs on (jutari, Julia).

Reading the result

The stability score is high: different seeds give nearly the same map. That is EG's promise, and it keeps it. But look at agreement with the oracle. On the content output the map is still a single spike at the read byte, now sized by its distance from the average reference, and that spike can shrink to almost nothing. On the position output agreement stays low. Overall EG is among the least faithful attribution methods in the study while producing tidy, plausible-looking maps. That combination, high plausibility and low faithfulness, is exactly what the intervention oracle is designed to expose.

Pitfalls

Try it yourself

julia --project=jutari tools/xai_study/phaseB_attribution/expected_gradients.jl --games core

Writes expected_gradients_<game>_{content,ball_pixel}.json/.npz and expected_gradients_core_summary.json into tools/xai_study/phaseB_attribution/out/. Defaults: --eg-samples 64 --eg-stability-seeds 5; the IG head-to-head uses --ig-steps 64.

Original papers & further reading

Read next: Integrated Gradients · KernelSHAP / Shapley · Grad×Input / DeepLIFT · Occlusion
How it's scored

The score is the Pearson correlation of the Expected-Gradients attribution with the oracle's exact causal map, reported raw, and the grading is always against the intervention oracle. Expected Gradients averages Integrated Gradients over a distribution of baselines, which makes the attribution provably stable across reference draws, but stability is not accuracy. Each term carries the factor input-minus-baseline, so when the reference pool holds bytes that are constant across states, that factor is zero and the attribution collapses. Even on the redesigned gameplay reference pool, and with the differentiable sampler turned on for the position regime, the method carries almost no true causal signal, and it is the lowest-faithfulness attribution method in the study. On a sprite's position it still vanishes for the usual reason: the naive gradient is zero on a discrete strobe-timed step and averaging baselines does not change that. Its plausibility proxy is high, which places it squarely in the danger zone of high plausibility with low faithfulness. The audit box reports the measured all-regime faithfulness across the 44 scored games, so the low number is an average over the whole scored set, not one unlucky game.

The score is measured against the §1 intervention oracle — never against another interpretability method. F (faithful) is always vs the oracle; see the execution stack. How each of F / S / M is actually computed for this method (and whether it matches the paper) is in the box just below; the numbers are in the In the audit box under it.

How F, S, M are computed here

The exact formula this method uses for each score, read from its runner, and whether it matches the paper's §3 (F ∧ S ∧ M triad) definition. From the committed audit fsm_math_phaseB.json.

AxisFormula (as computed) What it measuresMatches §3?
F
faithfulness
\(F = \rho_{\mathrm{Pearson}}\!\left(\mathrm{attr},\ |\Delta y(u)|\right)\)Raw Pearson correlation between the method's per-cause attribution magnitudes and the oracle's true absolute causal effects |Delta_y(u)|, scored separately for the content and position output regimes.✓ matches expected_gradients.jl: attr = expected-gradients per cause, F = pearson(attr, oracle_abs_delta); triad_extra_dict(f.pearson, attr, f.oracle_abs_delta). Record: out/expected_gradients_air_raid_content.json (metric_name=pearson_corr_with_oracle, value=0.79). Scorer pilot_ig_vs_oracle.jl pearson() (raw Statistics.cor, zero-variance->0); F = pearson(attr, oracle_abs_delta) where oracle_abs_delta = abs.(cmap.delta) (true |Delta_y| per cause). Also reports spearman, precision@k, deletion/insertion AUC (paper's auxiliary F metrics). Per-regime split: separate *_content.json and *_position.json records, each carrying its own extra.triad.{F,S,M}.
how it's measured — call stack:
  1. per-cause expected-gradients attribution — expected_gradients.jl:233
  2. raw Pearson of attribution vs oracle |Δy(u)| — pilot_ig_vs_oracle.jl:173
  3. assemble the F∧S∧M triad record — expected_gradients.jl:859
  4. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
S
sufficiency
\(S = \dfrac{\#\{\,u_{\mathrm{held}}:\ |\hat{y}-y|\le\varepsilon\,\}}{|\mathrm{held\text{-}out}|}\in[0,1]\)Fit Delta_y = a*attr + b on a calibration half of the do(u) causes, predict the disjoint held-out half, and report the fraction of held-out causes whose predicted output lands within an epsilon band of the oracle's bit-exact re-run.✓ matches common/triad_sm.jl sufficiency_score() (interleaved calib/held split by seed, least-squares 1-D fit Delta_y~a*attr+b on calib, epsilon = max(0.5, 0.10*heldout_spread)); assembled in triad_extra_dict(). The new §3 (sec:triad) admits the fraction-within-tolerance [0,1] special case of the held-out predictive test, which this held-out do(u) fit-then-predict estimator satisfies, so it matches. (Detail: epsilon is a self-scaled band 0.10*spread; the [-1,1] correlation form is available but this method reports the [0,1] hit fraction.)
how it's measured — call stack:
  1. sufficiency_score: fit Δy=a·attr+b on a calib half, predict held-out within ε — triad_sm.jl:111
  2. assemble the F∧S∧M triad record (calls sufficiency_score) — triad_sm.jl:173
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
M
minimality
\(M = |U^{\star}| / |\hat{U}| \in (0,1]\quad U^{\star}=\{u:\Delta y(u)>0\},\ \hat{U}=\{u:|\mathrm{attr}(u)|>\tau\}\)Ratio of the number of oracle causal movers (causes with nonzero true Delta_y) to the number of cells the method names above 1e-6 of its own max attribution; null when the oracle finds no mover or the method names nothing.✓ matches common/triad_sm.jl minimality_score() with name_frac=1e-6, mover_floor=0.0; the above-threshold named set is used (topk kept but not passed), see triad_extra_dict(). This is the paper's M = |U*|/|U_hat| in (0,1] (standardized everywhere), so it matches the new §3. (Detail: |U*| is taken as all oracle movers with Delta_y>0, an upper bound on the strictly-smallest reproducing subset, so M can be optimistic.)
how it's measured — call stack:
  1. minimality_score: |U*| oracle movers / |U_hat| named cells — triad_sm.jl:57
  2. assemble the triad record (calls minimality_score) — triad_sm.jl:178
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242

✓ matches = the same quantity as §3; ◐ partial = the same kind of estimator but a differing detail; ✗ does not match = a different quantity (see the note). Definitions: F = agreement with the oracle's true causal effects Δy(u); S = held-out predictive score in [−1, 1]; M = |U*|/|Û| (true-minimal-set size / named-set size).

In the audit

This is the method's entry in the actual cross-method audit — scored on the paper's correctness triad, each axis a mean over 44 of the 44 scored games (88 committed §R records), not the single example shown above. Tradition: gradient. The example figure (Pong) is one of those records.

0.186F — faithfulness vs oracle (mean over 44 games, ±0.069 CI95)
0.548S — sufficiency: held-out predictive (n/a where the paper does not define this axis)
1.000M — minimality: true-minimal-set / named-set (n/a otherwise)
88committed records aggregated
0.00human-plausibility proxy

F faithfulness (scored vs the oracle for every method) · S sufficiency (held-out predictive score in [−1, 1]; a negative value means the explanation predicts held-out interventions worse than the unperturbed baseline; reported for the predictive methods across all three phases where the calibration/held-out split is defined) · M minimality (true-minimal-set / named-set; where the method names a cause set) — n/a otherwise, per the paper's F ∧ S ∧ M triad.

Source: leaderboard.json · the whole leaderboard is on the methods page and the Paper 2 audit.

Results per game

This method's faithfulness on each of the 44 scored games (all-regime F, and the content vs position split). Click a header to sort. Every number is read from site_data.json (methods.expected_gradients.per_game).

M is n/a on 13 of these games. Minimality is M = |U*|/|Û|, the size of the true minimal cause set over the size of the set the method actually names. On a game where the method names nothing (|Û| = 0 — it discovers no circuit, its attribution map is all-zero, or it decodes no cell), that ratio is undefined, so M is left blank rather than scored. The aggregate M is the mean over the 31 games where the method did name a cause set.

GameF (all)content-Fposition-FSMNote
Bowling0.5180.6880.3480.9051.000
Enduro0.5001.0000.0000.5001.000position gradient vanishes
Riverraid0.5001.0000.0000.5221.000position gradient vanishes
Boxing0.4870.8170.1560.5421.000
Ice Hockey0.4770.7670.1880.5451.000
Demon Attack0.4770.9550.0000.8751.000position gradient vanishes
Fishing Derby0.4740.9480.0000.5001.000position gradient vanishes
Phoenix0.4550.9090.0000.5771.000position gradient vanishes
Bank Heist0.4500.9000.0000.8331.000position gradient vanishes
Skiing0.4050.8100.0000.4501.000position gradient vanishes
Double Dunk0.3990.7970.0000.5381.000position gradient vanishes
Freeway0.3980.7470.0490.5001.000
Name This Game0.3940.7880.0000.4171.000position gradient vanishes
Jamesbond0.3880.7470.0280.8931.000
Atlantis0.3860.7730.0000.4501.000position gradient vanishes
Video Pinball0.3850.7700.0000.5001.000position gradient vanishes
Private Eye0.3800.7580.0030.9601.000position gradient vanishes
Pong0.3710.4640.2780.4441.000
Air Raid0.2940.3600.2280.0361.000
Berzerk0.0580.0960.0200.4811.000position gradient vanishes
Alien0.0000.0000.0000.500n/aposition gradient vanishes
Assault0.0000.0000.0000.9051.000position gradient vanishes
Asterix0.0000.0000.0000.1001.000position gradient vanishes
Breakout0.0000.0000.0000.6001.000position gradient vanishes
Carnival0.0000.0000.0000.5261.000position gradient vanishes
Centipede0.0000.0000.0000.5001.000position gradient vanishes
Chopper Command0.0000.0000.0000.452n/aposition gradient vanishes
Frostbite0.0000.0000.0000.125n/aposition gradient vanishes
Gopher0.0000.0000.0000.929n/aposition gradient vanishes
Hero0.0000.0000.0000.417n/aposition gradient vanishes
Kangaroo0.0000.0000.0000.469n/aposition gradient vanishes
Krull0.0000.0000.0000.481n/aposition gradient vanishes
Kung-Fu Master0.0000.0000.0000.800n/aposition gradient vanishes
Montezuma's Revenge0.0000.0000.0000.9061.000position gradient vanishes
Ms. Pac-Man0.0000.0000.0000.475n/aposition gradient vanishes
Pacman0.0000.0000.0000.556n/aposition gradient vanishes
Pitfall0.0000.0000.0000.8821.000position gradient vanishes
Q*bert0.0000.0000.0000.476n/aposition gradient vanishes
Road Runner0.0000.0000.0000.1051.000position gradient vanishes
Seaquest0.0000.0000.0000.479n/aposition gradient vanishes
Space Invaders0.0000.0000.0000.528n/aposition gradient vanishes
Tennis0.0000.0000.0000.5001.000position gradient vanishes
Venture0.0000.0000.0000.4741.000position gradient vanishes
Yars' Revenge0.0000.0000.0000.4641.000position gradient vanishes

Call stack — how it runs on jutari / jaxtari

The path from this method's runner (main) into the bit-exact VCS substrate, and the computation it involves. Every step links to the exact source on main. From callstack_phaseB.json.

Applied on the substrate

  1. env reset + per-frame step of the bit-exact VCS — env_reset! / env_step! jutari
  2. shared gameplay-state testbed — build_shared_testbed jutari
  3. delegates to ig_baseline_sweep.jl (included) for the shared scorer + content read — include(ig_baseline_sweep.jl) runner

The computation (differentiable / gradient path)

  1. CONTENT output EG integrates = forward-exact one-hot RAM read (via ig_baseline_sweep) — content_read -> soft_ram_peek jutari-diff call site tools/xai_study/phaseB_attribution/ig_baseline_sweep.jl:294 (reused via include)
  2. EG background reference pool D drawn from the seeded gameplay stream (each row = RAM tape at a prefix frame, so the causal byte varies) — reference_pool runner
  3. Expected Gradients: Monte-Carlo over (baseline m ~ D, alpha ~ U(0,1)); accumulate (x-x0)*dy/dx at interpolated x_alpha — expected_gradients runner
  4. autodiff at each MC interpolation point x_alpha — Zygote.gradient(readf, xalpha) Zygote
  5. POSITION path restored via bilinear sampler (the redesign keystone) — _st_sampler_position_read runner-diff

Scored against the exact intervention oracle Δy(u): run_intervention.

On jaxtari (JAX / GPU): the same differentiable path has a bit-exact JAX sibling (Theorem 1, forward-exact) for batched GPU runs — JAX-equivalent differentiable path (bit-exact per Theorem 1, for GPU batching): jaxtari/jaxtari/diff/soft_step.py, soft_mem.py, straight_through.py

Implementation
tools/xai_study/phaseB_attribution/expected_gradients.jl
Reference
Erion et al. 2021 (NMI)
Record
expected_gradients_pong_content.json
All records
phaseB_attribution/out

The figure is generated from the committed record by docs/gen_method_figures.py; the game frame and each RAM cell's screen footprint are produced by render_scenes.jl / cell_footprints.jl.