Phase A · neuroscience battery · knock one unit out
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
The oldest question in brain science is: what stops working if this part is gone? In
1848 an iron rod destroyed part of Phineas Gage's frontal lobe. He survived, but his personality
changed. Doctors concluded that this region had something to do with self-control. That is a
lesion study: remove or silence one part, watch which behaviour is lost, and credit the part
with that behaviour.
The appeal is that a lesion is an intervention, not an observation. You do not just
watch a unit fire together with a behaviour; you take the unit away and see whether the behaviour
goes too. That is a causal test. Its weakness is that it tests one unit at a time. If two units do
a job together, or back each other up, removing one may show nothing, or something misleading.
On the Atari we can measure both sides: how well single lesions rank the units, and how much of the
joint behaviour they cannot see.
How it works on a neural network
Neuroscience origin. Lesions come from accidents (Gage), strokes and surgery, and in
animals from deliberate damage, cooling or drugs. Modern tools such as optogenetics can switch a
cell type off for a few milliseconds. Jonas & Kording “lesioned” the transistors of a
simulated 6502 chip one by one (the VCS CPU, the 6507, is a 6502 variant) and found some that broke only one game. They
warned that this does not mean the transistor is a “Donkey Kong transistor”.
Neural-network analogue. An ablation study: set one unit's activation to zero (or
to its mean) and measure the drop in accuracy or in a logit. Dropout does random ablations
during training. Written as an intervention on unit \(u\) with a set of clamp values \(V\):
\[ I(u) \;=\; \max_{v \in V}\; \big|\,y\big(\mathrm{do}(h_u := v)\big) - y\,\big| . \]
Rank the units by \(I(u)\) and you have an importance map. To test it, compare its ranking
with a trusted ranking by Spearman's \(\rho\), the correlation of the two rank lists
(\(+1\) = same order).
Toy example. Let \(y = a\cdot b + c\) at \(a=b=c=1\), so \(y = 2\). Lesion \(a\) to 0:
\(y = 1\), \(I(a) = 1\). Likewise \(I(b) = 1\) and \(I(c) = 1\). The map says all three matter
equally. Now lesion \(a\) and \(b\): \(y = 1\), a drop of 1, not \(1+1 = 2\). The
interaction term
\[ \Delta_{\text{int}}(a,b) = E(a,b) - \big(E(a)+E(b)\big) = 1 - 2 = -1 \]
is non-zero: \(a\) and \(b\) work as a team (a product), \(c\) works alone (a sum). No single-unit
map can tell those two kinds of units apart.
Recipe
- Freeze the system in one state and record a baseline run of the outputs you care about.
- For each unit \(u\): restore the state, clamp \(u\) to a lesion value (zero, or a very different value), re-run, record the outputs.
- Turn the change into one number per unit: the lesion importance \(I(u)\). Take the largest effect over the lesion values tried.
- Rank the units by \(I(u)\). This is the importance map.
- Score the map against a trusted reference ranking with Spearman's \(\rho\).
- Lesion selected pairs too and compare \(E(i,j)\) with \(E(i)+E(j)\) to expose interactions the map hides.
From a neural network to the Atari
| The neuron | One candidate RAM byte: one of the 128 bytes of VCS working memory that published annotations (OCAtari / AtariARI) link to a game concept such as ball x or score. |
|---|
| The lesion | intervene_ram! at frame \(f^*\): overwrite the byte with \(0\) (“silence”) or with base XOR 255 (every bit flipped, a maximally different value). |
|---|
| The behaviour | After 15 frames of re-run: the absolute change of every candidate byte plus the number of screen pixels that differ from the un-lesioned run. |
|---|
| The neurologist's ground truth | The oracle role of each byte: the same measurement with a larger set of interventions \(\{0,\ +17,\ +37,\ \text{XOR }255\}\), each a real re-run of the real ROM (the cartridge program). |
|---|
| Patients with two lesions | Pairs of the most important bytes, both flipped at once, to measure the interaction term. |
|---|
How we apply it to the VCS
The runner A2_lesions.jl works on the same frozen game state as every method in the
study: the cartridge is booted (60 no-op plus 4 reset frames), then 90 frames of seeded random
joystick input are played. That frame is \(f^*\); the horizon is the next 15 frames. Two fresh
replays must agree byte for byte before anything is scored.
- Lesion map (method). For each candidate byte the runner deep-copies the frozen machine,
writes \(0\) or base XOR 255 into it, and re-runs the 15 frames with the recorded joystick
inputs. The footprint is the sum over candidate bytes of \(|\text{value} - \text{baseline}|\) plus the
count of changed screen pixels. The importance is the larger footprint of the two clamps. It also
records whether the machine still produced a valid frame; on the VCS a poked byte never crashes the
CPU, so that flag is almost always true.
- Oracle role (truth). The same footprint, maximised over four interventions: \(0\),
base\(+17\), base\(+37\) and XOR 255. The headline score is Spearman's \(\rho\) between the two
rankings. A positive control ranks the oracle against itself and must give \(\rho = 1\).
- Interactions. The runner takes the top-\(K\) bytes by lesion importance (\(K\) chosen so
that at most 60 pairs are tested), flips both bytes of each pair, and computes
\(\Delta_{\text{int}} = E(i,j) - (E(i)+E(j))\). A pair counts as a missed interaction if
\(|\Delta_{\text{int}}|\) exceeds 5 % of the typical single effect.
- Specificity check. A byte is “specific” to the lesion map if at least 80 %
of its footprint lands on one readout. The runner counts how many of those the oracle calls generic
(touching three or more readouts).
- Triad. F is \(\rho\). S re-ranks against a held-out value (base\(+37\)) the lesion never
used. M compares how many bytes the map names with how many truly move the output.
How this differs from a brain lesion. Our “lesion” is a one-time write at
\(f^*\), not a clamp held for the whole horizon. The game program is free to overwrite the byte on
the next frame, much as a brain can compensate. Also note that the lesion's two clamps are a
subset of the oracle's four interventions, measured with the same footprint. A high rank
correlation is therefore expected by design; the interaction count is the informative part.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
A2_lesions.jl:278 — The lesion primitive: deep-copy, write one or two bytes, step the horizon, snapshot. - XAI
A2_lesions.jl:373 — The two lesion values {0, base XOR 0xFF}, next to the oracle's four and the held-out one. - XAI
A2_lesions.jl:345 — The behavioural readout: per-byte absolute change plus count of changed screen pixels. - XAI
A2_lesions.jl:385 — Per-unit importance map under a given do-set (used for the method, the oracle and the held-out probe). - XAI
A2_lesions.jl:696 — Pair lesions among the top units: the interaction term the single-unit map cannot see. - XAI
A2_lesions.jl:575 — One game: shared state, bit-exact check, lesion vs oracle maps, Spearman, interactions, triad. - substrate
shared_testbed_impl.jl:115 — The shared seeded-gameplay state and its oracle cause-density gate. - substrate
oracle_intervene.jl:242 — The reference oracle: poke a cause, re-run the ROM, snapshot (drives the gate). - substrate
jutari_oracle.jl:176 — Write one byte into the console's RAM (the A2 runner carries an identical local copy). - substrate
StellaEnvironment.jl:259 — One video frame of the bit-exact emulated VCS.
Reading the result
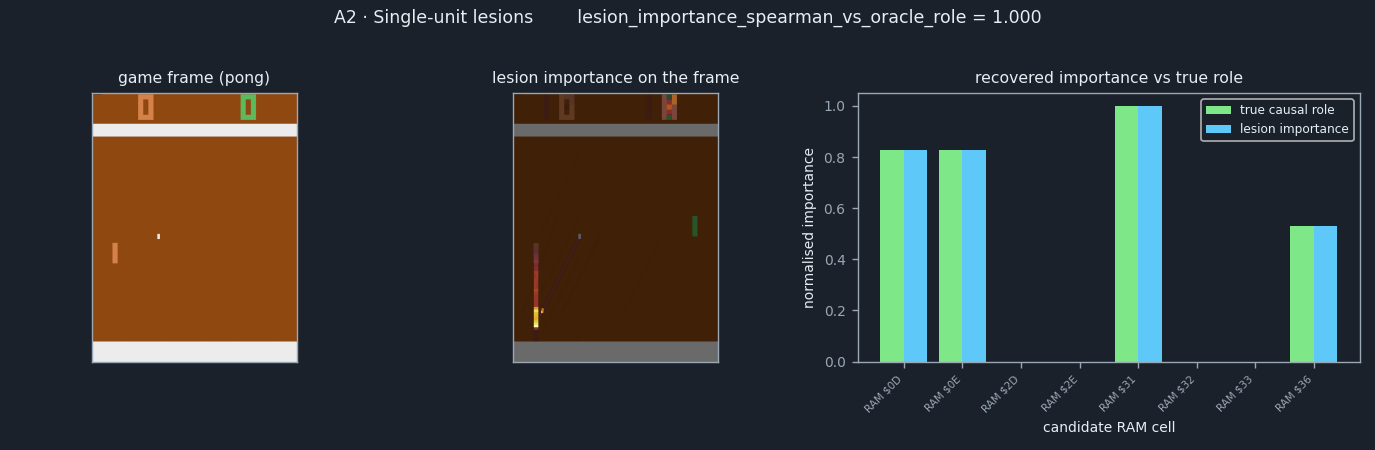
The figure shows the game frame, a heat-map of where on the screen the lesions changed pixels,
and a bar chart with two bars per candidate byte: the oracle's true causal role and the lesion
importance, both scaled so the largest is 1. A faithful map has bars of matching height. In Pong
they match exactly: the score bytes and the ball bytes are tall, the paddle bytes are
zero. That is why this is the one classical method near the top of the battery. What the bars do
not show is how the bytes combine. Look in the record's interaction block for the pairs whose
joint lesion is far from the sum of the singles.
Pitfalls
- Interactions are invisible. Redundant units (either one suffices) look unimportant alone; cooperating units (both needed) are each over-credited. Only pair or group lesions reveal this.
- The lesion value matters. Zero is not “off” for a RAM byte; it is just another number, and may be a perfectly normal game value. That is why two very different clamp values are tried.
- Importance is not function. Knowing a byte matters says nothing about what it does. Jonas & Kording's game-specific transistors were generic circuitry.
- Compensation. A one-time poke can be undone by the program on the next frame, just as networks and brains re-route around a damaged unit.
- Agreement partly by construction. Here the lesion and the oracle share the same machinery, so a high score says the cheap probe ranks units well, not that the explanation is complete.
Try it yourself
julia --project=jutari tools/xai_study/phaseA_kording/A2_lesions.jl --games core
Writes A2_lesions_<game>.{json,npz} per game and a combined A2_lesions.{json,npz} into tools/xai_study/phaseA_kording/out/. --max-pairs K caps the interaction budget (default 60); --shard i --nshards n runs one game per cluster task.
Original papers & further reading
Read next: Occlusion · Activation patching / causal mediation · A1 · Connectomics / data-flow graph · A3 · Tuning curves