Neuroscience battery · causal discovery from timing alone
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
You record two signals over time, say the activity of brain areas A and B. You cannot cut
wires or stimulate anything. Can you still say which one drives the other? Clive Granger's idea
(1969) is a clever proxy: a cause comes before its effect, and it carries information about the
effect. So try to predict B's next value from B's own past. Then add A's past. If the prediction
gets clearly better, A is said to Granger-cause B. Run this for every ordered pair and you get
a directed graph of “who influences whom”, built purely from passive recordings.
The word “causality” is generous. What the test really measures is temporal
precedence plus predictive information. That is not the same as a causal wire. If both A and B are
driven by a hidden third signal C, and A sees C a moment earlier than B, then A's past predicts B
perfectly, with no wire from A to B at all. This hidden common driver is a confounder. A
clock-driven machine like the Atari is full of them. A6 measures how far the Granger graph sits from
the true wiring, which on the VCS we can establish by direct intervention.
How it works on a neural network
Neuroscience origin. Granger causality is a workhorse for “directed functional
connectivity” in EEG, MEG, LFP and fMRI data (Seth et al. 2015). Jonas & Kording applied it
to a simulated 6502 chip and found a graph that bore little resemblance to the real circuit.
Deep-learning analogue. In XAI it is temporal-precedence causal discovery on activation
time series: record hidden units of a recurrent network, the residual stream across tokens, or the
latent state of an RL agent over steps, then infer which units “drive” which.
The test. For an ordered pair \(x\to y\) and a lag \(p\), fit two linear autoregressions by
least squares:
\[ \text{restricted:}\; y_t = a_0 + \sum_{l=1}^{p} a_l\,y_{t-l} + e_t, \qquad
\text{unrestricted:}\; y_t = a_0 + \sum_{l=1}^{p} a_l\,y_{t-l} + \sum_{l=1}^{p} b_l\,x_{t-l} + e'_t . \]
With residual sums of squares \(\mathrm{RSS}_r \ge \mathrm{RSS}_u\) over \(n\) usable steps, the
Granger statistic and its F-test are
\[ G(x\to y) = \ln\frac{\mathrm{RSS}_r}{\mathrm{RSS}_u}, \qquad
F = \frac{(\mathrm{RSS}_r-\mathrm{RSS}_u)/p}{\mathrm{RSS}_u/(n-2p-1)} . \]
An edge \(x\to y\) is declared when the F-test's p-value falls below a significance level
\(\alpha\) (usually 0.05).
Toy example. A hidden driver produces random numbers \(d = (3,1,4,1,5,9,2,6)\). Unit \(x\)
copies it one step late, unit \(y\) two steps late: \(x_t = d_{t-1}\), \(y_t = d_{t-2}\). So
\(x = (\cdot,3,1,4,1,5,9,2)\) and \(y = (\cdot,\cdot,3,1,4,1,5,9)\). Because \(d\) is random, \(y\)'s own
past says little about its next value: \(\mathrm{RSS}_r\) is large. But \(y_t = x_{t-1}\) exactly, so
adding \(x\)'s past drives \(\mathrm{RSS}_u\) to zero. \(G\) is huge, the p-value is tiny, and the
test reports a strong edge \(x\to y\). There is no wire between them: both just read \(d\). Cutting
\(x\) would leave \(y\) unchanged. Only that intervention reveals the truth.
Recipe
- Record the time series you want to connect (unit activations, region activity, RAM bytes).
- Drop constant series: with zero variance the test is undefined.
- For every ordered pair \(x\to y\), fit the restricted and unrestricted autoregressions at lag \(p\).
- Compute \(G=\ln(\mathrm{RSS}_r/\mathrm{RSS}_u)\) and the F-test p-value.
- Declare an edge \(x\to y\) if \(p\le\alpha\) (optionally also \(G\ge\tau\)).
- Read the resulting directed graph as the system's influence structure, and here score it against the intervention-defined true graph.
From a neural network to the Atari
| Recorded brain areas / hidden units | Two scopes: (a) the candidate RAM bytes, bytes the game is known to use for a score, a position, a timer, …; (b) three subsystems: the CPU's working RAM, the TIA (the video/sound chip, 64 registers) and the RIOT (timer and I/O chip). |
|---|
| An activity time series | Cell scope: the byte's value at every frame. Subsystem scope: how many bytes of that subsystem changed since the previous frame (its “firing rate”). |
|---|
| Directed functional connectivity | The Granger graph: an edge \(i\to j\) if byte \(i\)'s past significantly improves the prediction of byte \(j\) (lag 2, \(\alpha = 0.05\)). |
|---|
| The true anatomical wiring (unknown in a brain) | The intervention oracle's data-flow graph: edge \(i\to j\) if setting byte \(i\) to a new value at frame \(f^*\) and re-running the real ROM changes byte \(j\) 15 frames later. |
|---|
| A shared pacemaker / confounder | The frame loop. Every byte is updated in the same fixed order every frame, so many bytes move in lock-step without any data flowing between them. |
|---|
How we apply it to the VCS
The runner A6_granger.jl builds the method's graph and the true graph on the same
nodes, then compares them.
- The recording. From the shared gameplay state (seeded random actions, checkpoint at frame
\(f^*=90\)) it records a trajectory of 150 frames for most games, continuing with NOOP after the
gameplay window.
a6_record_tape calls env_step! each frame and stores the
128 RAM bytes plus the 64 TIA registers.
- Granger, cell scope.
run_cell_granger tests every ordered pair of candidate
bytes with granger: lag \(p=2\), \(\alpha=0.05\), magnitude floor \(\tau=0\) (so
significance alone decides, the textbook rule). The least-squares fits and the F-distribution
p-value are written out by hand, so no statistics package is needed.
- Granger, subsystem scope.
subsystem_activity turns the tape into three
change-count series. The CPU series counts changes in RAM bytes 0x00–0x5F, the RIOT series in
0x60–0x7F, the TIA series in its register file. They are scored against a fixed truth: the CPU
writes the TIA, and the CPU reads the RIOT.
- The true graph.
true_dataflow_graph takes the checkpoint at \(f^*\) and, for each
candidate byte \(i\), pokes three values (0, base+17, base+37) with intervene_ram!. It
re-runs the 15-frame horizon and marks \(i\to j\) for every candidate byte \(j\) that ends up
different. A second graph from base+37 alone serves as a held-out probe.
- Scores.
edge_rates gives the headline false-edge rate (share of Granger
edges that are not real), the missed-edge rate, and a direction disagreement: where both graphs
have one arrow between a pair, how often they point opposite ways. score_triad adds F (edge
F1 against the true graph), S (agreement with the held-out graph) and M (true edges divided by inferred
edges). A positive control scores the true graph against itself and must give F1 = 1.
Differences from the textbook use. The true graph is a 15-frame reachability graph: an
edge means byte \(j\) changed by any route, direct or indirect. It is measured at one state, while
Granger is fitted on the whole trajectory. Both choices favour Granger, not penalise it. The bytes are
also integers that jump in steps, not the smooth, noisy signals the linear model assumes.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
A6_granger.jl:431 — The bivariate Granger test: \(G=\ln(\mathrm{RSS}_r/\mathrm{RSS}_u)\), F statistic and p-value. - XAI
A6_granger.jl:406 — Builds the lagged design matrices for the restricted and unrestricted fits. - XAI
A6_granger.jl:611 — All ordered pairs of candidate bytes → the inferred directed graph. - XAI
A6_granger.jl:559 — CPU / TIA / RIOT “firing rates”: bytes changed per frame. - XAI
A6_granger.jl:646 — The ground-truth graph: poke each byte, re-run the ROM, see which bytes move. - XAI
A6_granger.jl:678 — False-edge rate, missed-edge rate and direction disagreement. - XAI
A6_granger.jl:839 — One game end to end: recording → both Granger scopes → true graph → triad → control. - substrate
jutari_oracle.jl:176 — The intervention: write one value into one RAM byte of a copied machine. - substrate
StellaEnvironment.jl:259 — One video frame of the real, bit-exact machine (recording and re-runs). - substrate
oracle_intervene.jl:242 — The shared oracle that gates the gameplay state used by every Phase-A runner.
Reading the result
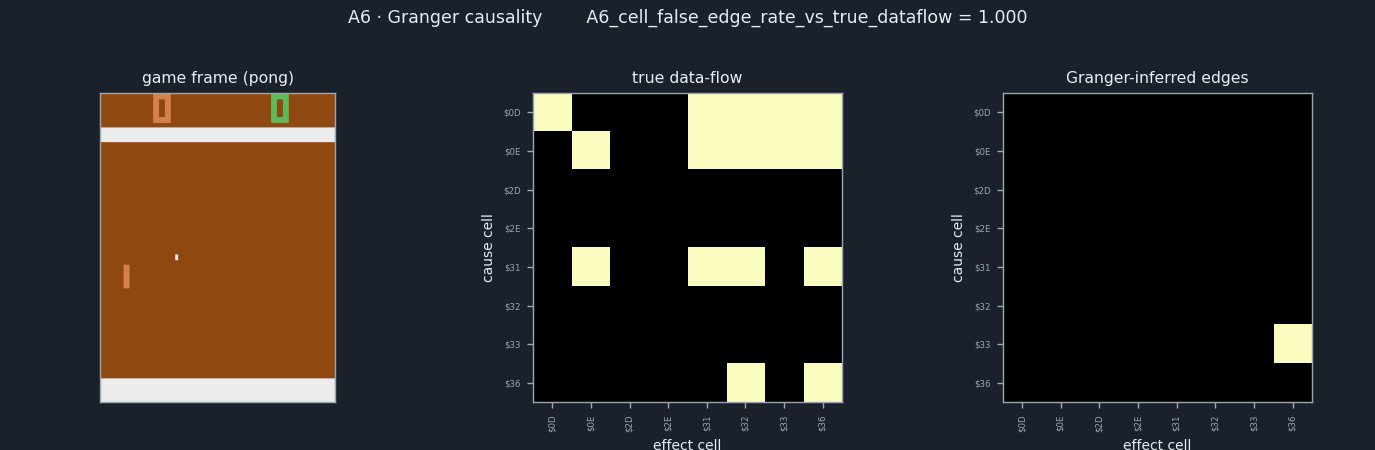
The figure sets the Granger graph beside the true data-flow graph over the same candidate bytes
(Pong). Here the two hardly overlap: the true graph has whole rows of edges (the score and ball bytes
reach many cells within 15 frames), while Granger asserts almost nothing, and what it does assert is
not in the truth. In games with many moving bytes (Ms. Pac-Man, Q*bert) the Granger graph turns
dense instead, with many bytes appearing to drive many others. Either way most Granger edges
have no counterpart in the truth, which is why the false-edge rate sits near its ceiling and the
faithfulness is among the lowest in the battery. The subsystem scope in the record tells the same
story at coarse scale. Changing the lag or the threshold moves edges around but does not fix the
picture, because the shared frame loop creates the predictability.
Pitfalls
- Precedence is not causation. A common driver seen at different delays produces strong, significant, directed edges between units that never interact (the toy example).
- Lock-step systems break the test. When everything is updated by one clock, almost every series predicts almost every other one. Deep networks run by a fixed schedule over time steps or layers share the problem.
- Model mismatch. The test assumes linear, stationary, noisy series. Integer counters that wrap at 256, flags and step jumps violate all three. Stokes & Purdon show that filtering and model order distort results even on well-behaved data.
- Multiple testing. With \(n\) units there are \(n(n-1)\) tests. At \(\alpha=0.05\) some edges appear by chance alone, before any confounding.
- The fix is an intervention, not a better statistic. Only cutting or setting a unit separates “earlier” from “cause”. See lesions and activation patching.
Try it yourself
julia --project=jutari tools/xai_study/phaseA_kording/A6_granger.jl --games core
Writes A6_<game>.json/.npz (Granger statistics, p-values, inferred and true adjacency matrices, edge rates, triad) into tools/xai_study/phaseA_kording/out/. Try --lag 4 or --alpha 0.01 to see that the false edges persist. Minutes per game; the true graph costs three ROM re-runs per candidate byte.
Original papers & further reading
- Granger (1969). Investigating Causal Relations by Econometric Models and Cross-spectral Methods. Econometrica 37(3): 424–438. — doi.org/10.2307/1912791
- Seth, Barrett & Barnett (2015). Granger Causality Analysis in Neuroscience and Neuroimaging. Journal of Neuroscience 35(8): 3293–3297. — doi.org/10.1523/JNEUROSCI.4399-14.2015
- Stokes & Purdon (2017). A study of problems encountered in Granger causality analysis from a neuroscience perspective. PNAS 114(34): E7063–E7072. — doi.org/10.1073/pnas.1704663114
- Jonas & Kording (2017). Could a Neuroscientist Understand a Microprocessor? PLoS Computational Biology 13(1): e1005268. — doi.org/10.1371/journal.pcbi.1005268
Read next: A1 · Connectomics / data-flow graph · A4 · Pairwise correlations · A2 · Single-unit lesions · Activation patching / causal mediation