Phase A · neuroscience battery

A4 · Pairwise correlations

cf. Jonas & Kording 2017

← back to the method catalogue

What it does?

This method studies the correlation structure across the machine's cells. In neuroscience the 'spike-word' or pairwise-correlation analysis looks at which units fire together, and reads coordinated firing as evidence of shared function or coupling. We compute the same statistics over RAM. For every pair of cells we measure how their values co-vary across the trajectory, and we also measure the global, population-level correlation. The familiar finding in neural data is weak pairwise but strong global correlation, and the VCS reproduces that signature. The idea is that cells which move together are functionally linked, so the correlation matrix should approximate the true coupling. The method is purely observational: it never intervenes, it only watches. That is its limit. On a clock-locked machine almost everything co-varies with almost everything else, driven by shared timing signals rather than by direct influence. So the correlation structure is real but mostly reflects common drivers, not causal links. It detects that the machine is active and coordinated, but it does not separate a true dependency from two cells that merely share a clock.

A4 · Pairwise correlations result

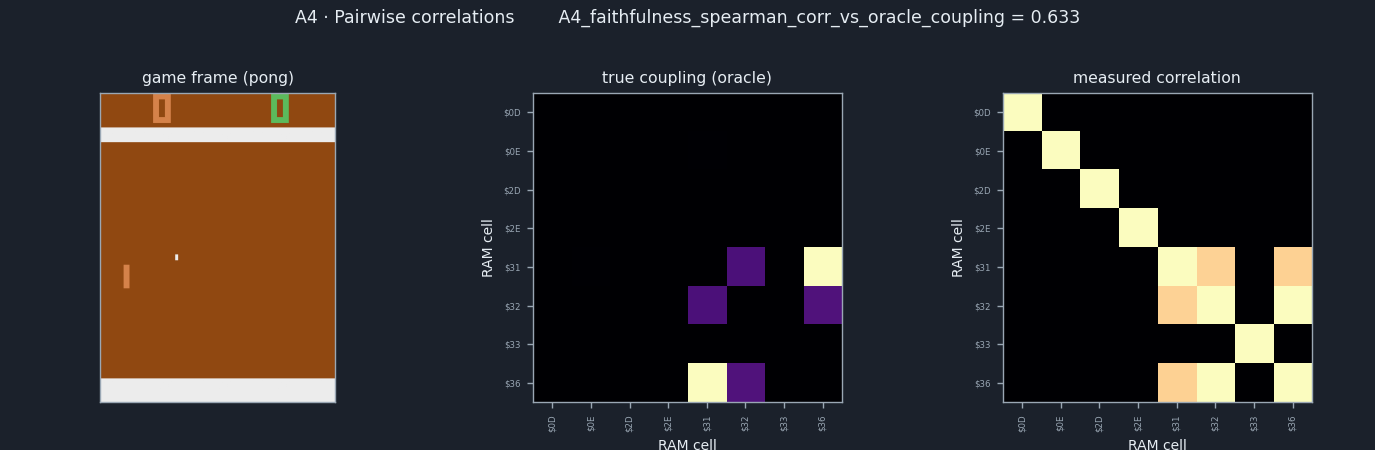
Two adjacency matrices over the candidate RAM cells: the true data-flow graph and the graph this method recovered. A bright cell (row = cause, column = effect) is an edge; the difference between the two panels is the error. A4_faithfulness_spearman_corr_vs_oracle_coupling = 0.633 — this example only (pong, state gameplay(seed=0,prefix=90)+15); the audit aggregate is below.

Phase A · neuroscience battery · who fires together?

Learn the method — a beginner's guide

New to explainable AI? This block explains the method as it is used on neural networks, then how we run the very same method on an Atari 2600, where — unlike for a network — we know the right answer. Every implementation step links to the code. See also the XAI primer for the shared vocabulary.

The idea in plain words

Record many neurons at once and you get a table: one row per moment in time, one column per neuron. A natural first question is which neurons go up and down together? Measure that for every pair and you get a correlation matrix. Groups of units that move together are candidates for working together. In neuroscience the patterns of joint firing are called spike words, and their statistics have been studied in detail.

A famous finding is “weak pairwise, strong global”. Any two neurons are only weakly correlated, yet the whole population sits in a few coordinated states far more often than chance. The tempting reading is that the correlation structure reveals the coupling, the true influence of one unit on another. But correlation is a passive measurement. Two units can move together because one drives the other, or because both are driven by a third thing. On the VCS almost everything is driven by the same clock, and the oracle can tell the two cases apart.

How it works on a neural network

Neuroscience origin. Schneidman et al. recorded about 40 retinal neurons and found pairwise correlations that were small, yet a model built only from them predicted the frequent population-wide patterns. Tkačik et al. extended this to larger populations. Jonas & Kording ran the same statistics on transistors of a 6502 chip and found the same “weak pairwise, strong global” picture, in a system whose real wiring is known and looks nothing like a brain.

Neural-network analogue. Correlating unit activations over a dataset is common: to find redundant units, to match units across two trained networks (Li et al.), or to compare whole layers (SVCCA, CKA). For units \(i,j\) with activations \(x_i(t)\) over inputs \(t\):

\[ C_{ij} = \rho\big(x_i, x_j\big), \qquad \mathrm{PR} = \frac{\big(\sum_k \lambda_k\big)^2}{\sum_k \lambda_k^2}, \]

where \(\lambda_k\) are the eigenvalues of \(C\). The participation ratio PR counts the effective number of independent directions. A PR far below the number of units means a few global modes dominate (the same idea as keeping the top principal components).

Toy example 1 (common driver). Let a clock run \(t = 1,\dots,5\). Unit \(x = t\) and unit \(y = 2t + 1\). Neither reads the other. Still \(\rho(x,y) = 1\). If you overwrite \(x\), \(y\) does not change: the true coupling is \(0\). A correlation of 1, a coupling of 0.

Toy example 2 (weak pairwise, strong global). Three units, every pair correlated \(0.3\). The eigenvalues of \(C\) are \(1.6, 0.7, 0.7\), so \(\mathrm{PR} = 3^2 / (1.6^2 + 0.7^2 + 0.7^2) = 9 / 3.54 \approx 2.5\). With 300 such units, the top eigenvalue is \(1 + 299 \cdot 0.3 \approx 91\), the other 299 are \(0.7\), and PR is about 11, far below 300: many weak pairs add up to one strong collective mode.

Recipe

  1. Record the activity of all units over a long trajectory: a matrix of time × units.
  2. Compute the Pearson correlation \(C_{ij}\) for every pair of units.
  3. Group units whose \(|C_{ij}|\) passes a threshold into clusters (here: single linkage, \(\tau = 0.7\)).
  4. Summarise the global structure: median \(|C_{ij}|\), the share of variance in the top eigenvalues, the participation ratio.
  5. Obtain an independent measure of true coupling (here: the intervention oracle) for every pair.
  6. Score: rank-correlate \(|C_{ij}|\) with the true coupling over all pairs, and compare clusters with the known variable groups.

From a neural network to the Atari

The neuronOne candidate RAM byte of the VCS's 128-byte working memory, named by published annotations (OCAtari / AtariARI); for the population statistics, every RAM byte that varies.
The multi-electrode recordingA RAM tape: all 128 bytes logged after every frame (one 1/60 s picture) while the bit-exact emulator plays the shared input stream, 150 frames for most games.
The spike wordThe joint pattern of byte values at one frame; the pairwise statistic is the Pearson correlation of two bytes' time series.
The true couplingThe oracle: overwrite byte \(i\) at frame \(f^*\) with \(0\) or base\(+17\), re-run the real ROM 15 frames, measure \(|\Delta|\) of byte \(j\). Symmetrised as \(\max(i\to j,\ j\to i)\).
Known cell typesConcept families from the labels: all enemy_* bytes form one true group, all player_* bytes another, and so on.

How we apply it to the VCS

The runner A4_correlations.jl has an observational half (the method) and an interventional half (the truth). Both use the shared game state: boot the cartridge (the ROM), play 90 frames of seeded random joystick input to reach \(f^*\), keep the next 15 frames as the horizon, and confirm that two fresh replays agree byte for byte.

  1. Recording. a4_record_ram steps the emulator along the same input stream (no-ops after the gameplay frames) and stores the 128 RAM bytes after every frame. The length is set per game (150 frames for most, longer for Q*bert and Ms. Pac-Man).
  2. Pairwise correlations. pairwise_corr computes the Pearson matrix over the candidate bytes. A byte that never changes has zero variance and is given correlation 0 with everything.
  3. Clusters versus true groups. Bytes with \(|C_{ij}| \ge 0.7\) are linked, and connected components become clusters. These are compared with the concept families using the Rand index, cluster purity and an over-grouping ratio: the share of within-cluster pairs that belong to different true groups.
  4. Global structure. Over the candidate bytes and over the whole population of varying RAM bytes, the runner reports mean and median \(|C_{ij}|\), the top-1 and top-3 eigenvalue shares and the participation ratio. The “weak pairwise, strong global” flag is set when the population median \(|C_{ij}|\) is below 0.5 and the top three eigenvalues carry at least 60 % of the total.
  5. Oracle coupling. For every candidate byte \(i\), the machine is copied, byte \(i\) is set to \(0\) or base\(+17\), and the real ROM runs 15 frames. The coupling \(i\to j\) is the larger \(|\Delta|\) of byte \(j\). A third value, base\(+37\), is kept back as a held-out test.
  6. Scores. F is the Spearman rank correlation between \(|C_{ij}|\) and the oracle coupling over all off-diagonal pairs. S is the Pearson correlation with the held-out coupling. M compares how many pairs the method calls coupled with how many truly are. A positive control scores the oracle against itself.

How this differs from the neural original. Our units are bytes with up to 256 values, not binary spikes, so we use Pearson correlation rather than a maximum-entropy model of spike words. And the “true coupling” is a measured total effect over 15 frames, which includes indirect paths, not a list of direct synapses.

Read the code

XAI the interpretability method   substrate the bit-exact emulator it runs on (jutari, Julia).

Reading the result

The figure shows two square matrices over the same candidate bytes. Left: the oracle's true coupling; a bright square means overwriting one byte changes the other within 15 frames. Right: the measured correlation. The diagonal of the right matrix is always 1 and is not scored. If the two matrices lit up the same off-diagonal squares, correlation would be a faithful map of coupling. In Pong most candidate bytes are zero in both, and both light up the same small group of ball and paddle bytes, so the ranking is partly right. But inside that group the two disagree: correlation gives every pair a similar, high value, because the bytes all move with the same ball, while the oracle says only one pair is strongly coupled, two weakly, and the player paddle not at all. Correlation found the group, not the wiring inside it. That is the partial score in the audit box.

Pitfalls

Try it yourself

julia --project=jutari tools/xai_study/phaseA_kording/A4_correlations.jl --games core

Writes A4_<game>.{json,npz} per game into tools/xai_study/phaseA_kording/out/. --tau-corr 0.7 sets the clustering threshold, --traj-frames N the recording length, --selftest runs the checks on the first game without writing.

Original papers & further reading

Read next: A6 · Granger causality · A7 · Dimensionality reduction (NMF/PCA) · A3 · Tuning curves · A1 · Connectomics / data-flow graph
How it's scored

The score is a rank correlation between the measured cell-to-cell correlation structure and the oracle's true coupling. We compute how each pair of cells co-varies across the trajectory, assemble that into a coupling matrix, and compare it, by Spearman correlation, to the true coupling the oracle certifies. Faithfulness for this method is that correlation. It is only partial, because the method never intervenes; it only watches. On a clock-locked machine two cells can be strongly correlated because they share a driver, not because one influences the other. So the correlation matrix conflates true coupling with common drivers, and the score reflects that confusion. Sufficiency, whether the recovered structure can predict held-out interventions, is near zero for this method, because a correlation matrix carries no mechanism to re-generate behaviour. The grading is always against the oracle, not against another method. There is no sprite-position hard-case here; the output is a coupling matrix. The audit box reports the measured faithfulness and, where the paper defines it, the sufficiency, each aggregated across the scored games so no single game dominates the number.

The score is measured against the §1 intervention oracle — never against another interpretability method. F (faithful) is always vs the oracle; see the execution stack. How each of F / S / M is actually computed for this method (and whether it matches the paper) is in the box just below; the numbers are in the In the audit box under it.

How F, S, M are computed here

The exact formula this method uses for each score, read from its runner, and whether it matches the paper's §3 (F ∧ S ∧ M triad) definition. From the committed audit fsm_math_phaseA.json.

AxisFormula (as computed) What it measuresMatches §3?
F
faithfulness
\(F = \rho_{\mathrm{Spearman}}\!\left(|\mathrm{corr}|_{\mathrm{pairs}},\ \mathrm{coupling}_{\mathrm{pairs}}\right)\)Spearman correlation between absolute pairwise data correlations and the oracle intervention-based cell-cell coupling over candidate-cell pairs.✓ matches Oracle 'coupling' is a bit-exact intervention effect (not a data correlation); F correlates the method's |corr| map against it. Correlation primitive on pairs. Runner A4_correlations.jl,; record out/A4_pong.json triad.F=0.633.
how it's measured — call stack:
  1. F = Spearman(|corr| pairs, oracle coupling pairs) — A4_correlations.jl:655
  2. score_triad over the candidate-cell pairs — A4_correlations.jl:650
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
S
sufficiency
\(S = \rho_{\mathrm{Pearson}}\!\left(|\mathrm{corr}|_{\mathrm{pairs}},\ \mathrm{coupling}^{\mathrm{held\text{-}out}}_{\mathrm{pairs}}\right) \in [-1,1]\)Pearson correlation of the pairwise-correlation map vs the held-out do(base+37) coupling.✓ matches Held-out predictive correlation in [-1,1] of the pairwise-correlation map vs the held-out do(base+37) coupling: the §3 (sec:triad) form (can be negative). A4_correlations.jl; record S=-0.170.
how it's measured — call stack:
  1. S = Pearson(|corr| pairs, held-out do(base+37) coupling) — A4_correlations.jl:657
  2. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242
M
minimality
\(M = |U^{\star}| / |\hat{U}| \in (0,1]\quad(\text{over candidate-cell pairs})\)Number of oracle-coupled cell pairs over the number of high-correlation pairs the method names.✓ matches Runner now emits M = |U*|/|U_hat| over pairs (M_note '|U*|=4 (oracle movers) / |U_hat|=6'), the paper's set-size ratio at the pair level. Record out/A4_pong.json extra.triad.M=0.667. Replaced the former 1 − correlation-overgrouping rate.
how it's measured — call stack:
  1. minimality_score(|corr| pairs, oracle coupling) — A4_correlations.jl:670
  2. minimality_score: |U*| coupled pairs / |U_hat| named pairs — triad_sm.jl:57
  3. true causal effect Δy(u) by bit-exact re-run — oracle_intervene.jl:242

✓ matches = the same quantity as §3; ◐ partial = the same kind of estimator but a differing detail; ✗ does not match = a different quantity (see the note). Definitions: F = agreement with the oracle's true causal effects Δy(u); S = held-out predictive score in [−1, 1]; M = |U*|/|Û| (true-minimal-set size / named-set size).

In the audit

This is the method's entry in the actual cross-method audit — scored on the paper's correctness triad, each axis a mean over 36 of the 44 scored games (36 committed §R records), not the single example shown above. Tradition: correlational. The example figure (Pong) is one of those records.

0.251F — faithfulness vs oracle (mean over 36 games, ±0.059 CI95)
0.147S — sufficiency: held-out predictive (n/a where the paper does not define this axis)
0.393M — minimality: true-minimal-set / named-set (n/a otherwise)
36committed records aggregated
0.00human-plausibility proxy

F faithfulness (scored vs the oracle for every method) · S sufficiency (held-out predictive score in [−1, 1]; a negative value means the explanation predicts held-out interventions worse than the unperturbed baseline; reported for the predictive methods across all three phases where the calibration/held-out split is defined) · M minimality (true-minimal-set / named-set; where the method names a cause set) — n/a otherwise, per the paper's F ∧ S ∧ M triad.

Source: leaderboard.json · the whole leaderboard is on the methods page and the Paper 2 audit.

Results per game

This method's faithfulness on each of the 36 scored games (all-regime F; this method has no content-vs-position split (see the note below)). Click a header to sort. Every number is read from site_data.json (methods.A4_correlations.per_game).

content-F and position-F are n/a for this method. The content-vs-position split applies only to pixel-attribution methods — those that produce an attribution map over the framebuffer, whose score can be read separately on the smooth content outputs and the discrete position outputs (where the naive gradient is provably zero). This method does not attribute to a pixel output; it is graded by its own fidelity metric (A4_faithfulness_spearman_corr_vs_oracle_coupling), reported as the F column, so there is no content or position regime to separate.

M is n/a on 1 of these games. Minimality is M = |U*|/|Û|, the size of the true minimal cause set over the size of the set the method actually names. On a game where the method names nothing (|Û| = 0 — it discovers no circuit, its attribution map is all-zero, or it decodes no cell), that ratio is undefined, so M is left blank rather than scored. The aggregate M is the mean over the 35 games where the method did name a cause set.

S is negative on 8 of these games. Sufficiency asks whether the explanation can predict the outcome of held-out interventions it was not fit on; for this method S is the held-out predictive correlation between its claim and the true effect, so it lies in [−1, 1]. A value near 0 means the explanation predicts no better than the unperturbed output; a negative value means it predicts worse — its held-out claim is anti-correlated with the truth (named yet causally unused). The aggregate S is the mean over the scored games.

GameF (all)content-Fposition-FSMNote
Pong0.633n/an/a-0.1700.667
Bowling0.609n/an/a0.5270.667
Atlantis0.503n/an/a0.0000.200
Enduro0.500n/an/a-0.0640.667
Boxing0.469n/an/a0.1440.464
Video Pinball0.463n/an/a0.5440.167
Air Raid0.445n/an/a0.3980.250
Chopper Command0.416n/an/a0.1790.256
Yars' Revenge0.401n/an/a0.2500.286
Frostbite0.362n/an/a-0.0390.821
Venture0.354n/an/a0.1410.396
Pitfall0.345n/an/a0.3350.141
Seaquest0.304n/an/a0.0330.429
Double Dunk0.295n/an/a0.0810.111
Montezuma's Revenge0.280n/an/a0.3220.867
Berzerk0.280n/an/a0.2370.317
Demon Attack0.280n/an/a0.0080.197
Jamesbond0.272n/an/a0.3450.107
Carnival0.254n/an/a0.2440.178
Ice Hockey0.230n/an/a0.3290.321
Phoenix0.221n/an/a0.3000.036
Breakout0.219n/an/a-0.0461.000
Riverraid0.136n/an/a-0.0270.110
Centipede0.129n/an/a0.1430.143
Krull0.124n/an/a0.0050.500
Space Invaders0.117n/an/a0.0450.400
Asterix0.109n/an/a0.1370.700
Assault0.107n/an/a0.2470.222
Road Runner0.082n/an/a-0.0570.077
Q*bert0.049n/an/a0.0810.009no true-cause signal
Tennis0.023n/an/a0.1000.393no true-cause signal
Private Eye0.011n/an/a0.1200.321no true-cause signal
Alien0.000n/an/a0.0001.000no true-cause signal
Hero0.000n/an/a-0.0081.000no true-cause signal
Kangaroo0.000n/an/a0.000n/ano true-cause signal
Skiing0.000n/an/a-0.1330.333no true-cause signal

Call stack — how it runs on jutari / jaxtari

The path from this method's runner (compute_game) into the bit-exact VCS substrate, and the computation it involves. Every step links to the exact source on main. From callstack_phaseA.json.

Applied on the substrate

  1. assemble the shared gameplay-state testbed + cause-density gate — build_a4_shared_state(game) -> build_shared_testbed(game; ...) runner
  2. build_shared_testbed definition: booted checkpoint + shared output + gate — function build_shared_testbed(game; ...) runner
  3. cause-density gate counts causes with |Delta_y|>floor via the oracle — cause_density = count(>(floor), deltas) runner
  4. record a (frames x 128) RAM tape by stepping the ROM with A4's per-game settings — a4_record_ram(game, frames, actions) runner
  5. step the real emulator one frame per action while recording — env_step!(env, Int(actions[t])) jutari
  6. read RAM into the tape each frame — get_ram(env) jutari

The computation

  1. compute the pairwise correlation matrix over candidate-cell time series (method under test) — pairwise_corr(tape, cands) runner
  2. extract global structure from the correlation matrix (clustering/summary over varying cells) — global_structure(C, varying, tape) runner

Scored against the exact intervention oracle Δy(u): run_intervention(checkpoint, actions, target_frame, horizon, cause).

Implementation
tools/xai_study/phaseA_kording/A4_correlations.jl
Reference
cf. Jonas & Kording 2017
Record
A4_pong.json
All records
phaseA_kording/out

The figure is generated from the committed record by docs/gen_method_figures.py; the game frame and each RAM cell's screen footprint are produced by render_scenes.jl / cell_footprints.jl.