Gradient family · a modified backward pass
Learn the method — a beginner's guide
New to explainable AI? This block explains the method as it is used on neural
networks, then how we run the very same method on an Atari 2600, where — unlike for a
network — we know the right answer. Every implementation step links to the code. See also the
XAI primer for the shared vocabulary.
The idea in plain words
Vanilla saliency maps of image classifiers look grainy. Positive and negative gradient signals
mix as they flow back through the network. Guided backpropagation changes one rule in the
backward pass to clean this up. At every ReLU (rectified linear unit, \(\max(0, z)\), the
standard on/off nonlinearity of deep nets) it lets a gradient through only if the unit was
active in the forward pass and the gradient arriving from above is positive.
Negative signals (“this feature argues against the class”) are thrown away.
The result looks spectacular: crisp, edge-like pictures of the object. That is why the method
became popular. But it is no longer the gradient of anything. It is a hand-modified signal.
Adebayo et al. (2018) asked a simple question: does the map change if we destroy the model?
For guided backprop it barely does. The map behaves more like an edge detector applied to the
input than an explanation of the network. This test, the model-randomisation sanity check,
is part of our experiment, run on the machine itself.
How it works on a neural network
Take one ReLU unit \(h = \max(0, z)\) and let \(g = \partial y/\partial h\) be the gradient arriving
from above. The three backward rules differ only in what they send down to \(z\):
\[ \text{backprop: } \mathbb{1}[z>0]\,g, \qquad
\text{deconvnet: } \mathbb{1}[g>0]\,g, \qquad
\text{guided: } \mathbb{1}[z>0]\,\mathbb{1}[g>0]\,g . \]
Guided backprop combines the two masks. Applied at every ReLU of the network it yields a map
\(G(x)\) that, unlike saliency, is not the derivative \(\nabla f(x)\).
Toy example. Two inputs, two hidden ReLUs, one output:
\(h_1 = \max(0, 2x_1 + x_2)\), \(h_2 = \max(0, x_1 - x_2 + 1)\), \(y = h_1 - h_2\).
At \(x = (1, 1)\): \(h_1 = 3\), \(h_2 = 1\), \(y = 2\). Both units are active. From above,
\(\partial y/\partial h = (1, -1)\).
- Vanilla gradient: \(1\cdot(2, 1) + (-1)\cdot(1, -1) = (1, 2)\). It says \(x_2\) matters
most.
- Guided: the \(-1\) arriving at \(h_2\) is negative, so it is zeroed. Only
\(1\cdot(2,1) = (2, 1)\) survives. It says \(x_1\) matters most.
The ranking flipped. \(h_2\) inhibits the output and \(x_2\) acts partly by reducing that
inhibition. Guided backprop discards inhibition, so it cannot see this. Check the truth directly:
raising \(x_2\) by 0.1 raises \(y\) by 0.2, raising \(x_1\) by 0.1 raises it by only 0.1. Here the
vanilla gradient was right and the “cleaner” map was wrong.
Recipe
- Run the forward pass and record which ReLUs are active (\(z > 0\)).
- Start the backward pass from the scalar output \(y\), as in vanilla saliency.
- At every ReLU, pass the gradient down only where \(z > 0\) and the incoming gradient is \(> 0\); set everything else to 0.
- Continue to the input. Display the (usually absolute) result as a heat-map.
- Sanity check (Adebayo): randomise the model's weights, recompute the map, and verify it changes. A map that stays the same cannot be explaining the model.
From a neural network to the Atari
| The network \(f\) | The Atari 2600 VCS running the ROM, emulated bit-exactly by jutari; its differentiable twin is JuTari.Diff. |
|---|
| The ReLUs | There are none. The soft VCS's nonlinearities are straight-through round/clamp (identity backward), the stop-gradient branch estimator, and the distance-softmax read used only in the relaxation study. So the guided rule is applied once, to the assembled gradient over RAM. |
|---|
| The input \(x\) | The 128 RAM bytes at the intervention frame \(f^*\). |
|---|
| The output \(y\) | A content output (one RAM byte read one-hot) and a position output (screen pixels changed versus the un-intervened frame, made differentiable by the bilinear sampler). |
|---|
| Randomising the weights | Randomising the program: every ROM byte is replaced by a random byte, except the CPU's reset/interrupt vectors so the console still boots. |
|---|
| “Is the map right?” | The intervention oracle: poke each cause, re-run the real ROM, measure \(|\Delta y|\). |
|---|
How we apply it to the VCS
Our substrate has no deep stack of ReLUs. The runner says so plainly, and implements guided
backprop as the rectification rule \(g \mapsto g\odot\mathbb{1}[g>0]\) applied to the gradient
\(\partial y/\partial u\) over the RAM vector \(u\), followed by an absolute value. It returns
the guided map and the vanilla \(|\partial y/\partial u|\), so the effect of the rule can
be measured directly.
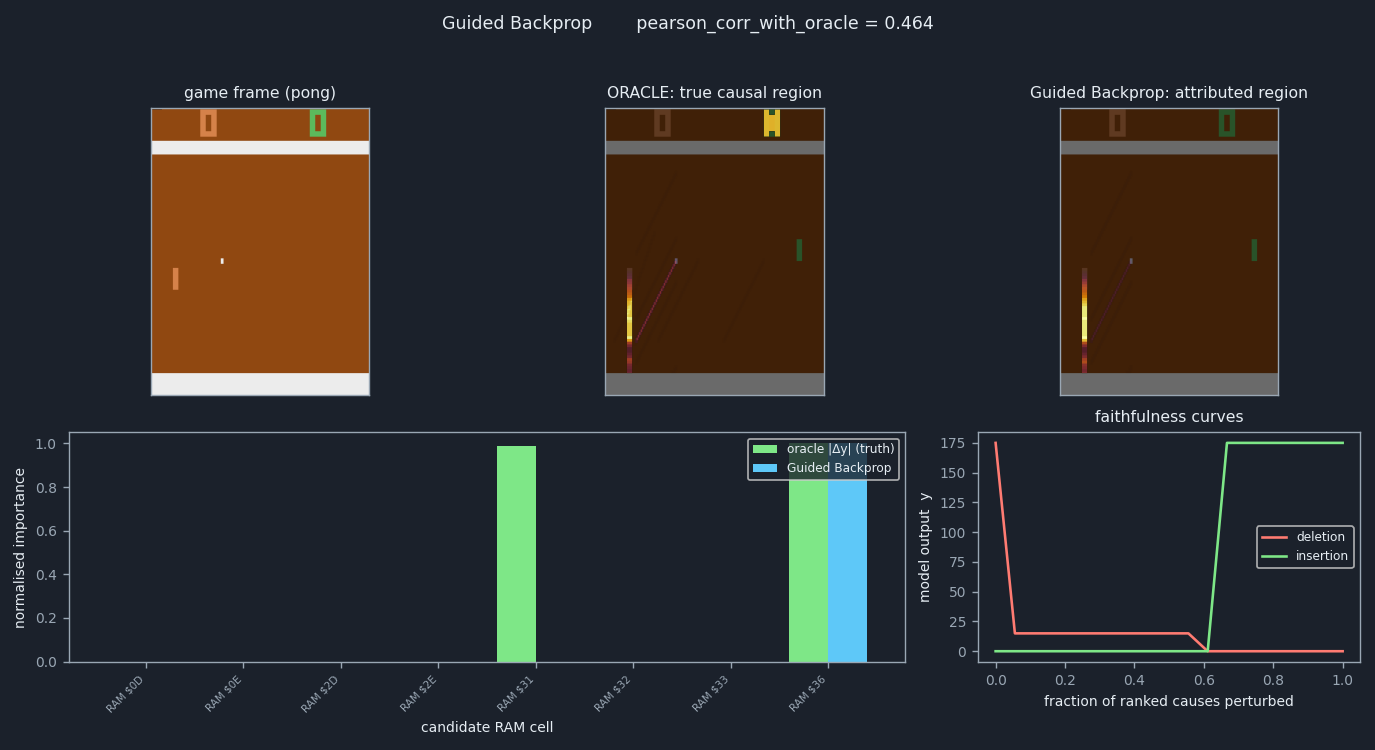
- Content output. \(y = \)
soft_ram_peek(ram, idx), whose gradient is the one-hot
vector \(e_{\text{idx}}\). It has no negative entries, so there is nothing to suppress: the guided
map equals vanilla saliency exactly. The runner records this as guided_equals_vanilla.
The byte idx is the candidate the oracle shows to be most causally active, the same
choice as the SmoothGrad runner, so only the backward rule differs.
- Is the rule real? To show it is not a no-op stub,
guided_demo_rectifies applies it
to a small linear surrogate with mixed-sign weights and asserts that every negative entry is
zeroed.
- Position output. The naive gradient is zero (sprite position is set by strobe timing). The
bilinear sampler restores one, but its sign depends on which side of the screen cell the sprite
edge sits: moving the sprite can reduce the cell's occupancy. A negative slope is exactly
what the guided rule deletes. So guided backprop can throw away the very gradient the sampler
restored. The runner reports the raw sampler gradient next to the rectified one.
- The Adebayo check.
randomize_rom fills the cartridge with random bytes but keeps the
last 6 bytes of each 4 KB bank (the 6502 reset/IRQ/NMI vectors). Three randomised programs are
booted and replayed to \(f^*\). The runner counts how many RAM bytes differ from the real game,
recomputes the guided map, and measures its cosine similarity to the real map. The scrambled programs
reach very different RAM states. Yet the content map is identical, because the one-hot Jacobian
does not depend on what the program computed. The runner classifies this as a genuine failure
(“model-invariant saliency, constant Jacobian”), not as a harness error.
- Scoring is shared with the other gradient methods: correlation and precision@3 against the
oracle, and deletion/insertion curves re-run on the real ROM, plus an oracle-vs-itself control.
Read the code
XAI the interpretability method
substrate the bit-exact emulator it runs on (jutari, Julia).
- XAI
guided_backprop.jl:336 — The guided rule: keep positive gradient entries, zero the negative ones. - XAI
guided_backprop.jl:347 — One Zygote gradient over RAM, then the rule; returns guided and vanilla maps side by side. - XAI
guided_backprop.jl:368 — Proof the rule is wired: a mixed-sign surrogate whose negative gradients must be suppressed. - XAI
guided_backprop.jl:443 — Model randomisation for the VCS: random ROM bytes, CPU vectors preserved. - XAI
guided_backprop.jl:479 — The Adebayo sanity check: cosine/Spearman of the map under program randomisation, with a failure-mode diagnosis. - XAI
guided_backprop.jl:564 — One output: oracle → guided map → scores → deletion/insertion → control → sanity check. - substrate
SoftStep.jl:106 — The one-hot RAM read: a linear unit with a non-negative gradient, so the guided rule has nothing to remove. - substrate
StraightThrough.jl:28 — The straight-through round: one of the soft VCS's actual nonlinearities (exact forward, identity backward). Not a ReLU. - substrate
shared_testbed_impl.jl:357 — The bilinear sampler; its triangular kernel has slopes of both signs. - substrate
oracle_intervene.jl:242 — The ground truth: poke a cause, re-run the real ROM, read the output.
Reading the result
On the content output the guided bars are the vanilla saliency bars, exactly. Any
agreement with the oracle is saliency's agreement. On the position output the map is often
empty, either because the naive gradient is zero or because the rule removed a negative sampler
slope. Then look at the sanity-check box. A cosine similarity near 1 between the real and the
scrambled-program maps means the map does not depend on the program. A faithful map must change
when the model is destroyed; this one stays the same. The oracle, by
contrast, re-runs the program and would see the difference at once.
Pitfalls
- Not a gradient. Guided backprop is a modified signal. It has no completeness property and no clear causal meaning.
- Discards inhibition. Inputs that matter by suppressing a unit are invisible to it, as the toy example shows.
- Model-insensitive. Adebayo et al. and Nie et al. showed that guided maps largely reconstruct the input image and change little when weights are randomised. On the VCS content read the map does not change at all.
- Substrate mismatch. The VCS has no ReLU layers, so here the method collapses to rectified vanilla saliency. That is an honest limit of transferring a network-specific rule to a different system.
- Looks are misleading. Sharper is not truer. Only the intervention oracle decides.
Try it yourself
julia --project=jutari tools/xai_study/phaseB_attribution/guided_backprop.jl --games core --sanity
Writes guided_backprop_<game>_{content,ball_pixel}.json/.npz and guided_backprop_core_summary.json into tools/xai_study/phaseB_attribution/out/. The sanity check boots three randomised ROMs per output; pass --no-sanity for a faster smoke run.
Original papers & further reading
- Springenberg, Dosovitskiy, Brox & Riedmiller (2015). Striving for Simplicity: The All Convolutional Net. ICLR workshop (introduces guided backpropagation). — arxiv.org/abs/1412.6806
- Adebayo et al. (2018). Sanity Checks for Saliency Maps. NeurIPS. — arxiv.org/abs/1810.03292
- Nie, Zhang & Patel (2018). A Theoretical Explanation for Perplexing Behaviors of Backpropagation-based Visualizations. ICML. — arxiv.org/abs/1805.07039
Read next: Vanilla gradient (saliency) · SmoothGrad · Grad×Input / DeepLIFT · Occlusion