cf. Olson 2021; Atrey 2020
An on-distribution counterfactual asks the smallest realistic change that flips the output. Instead of occluding with an artificial value, it edits the input toward a genuine alternative the system could actually produce, and finds the smallest such edit that changes the output. The explanation is the edit itself: 'change these cells to these plausible values and the outcome changes'. The point of the on-distribution constraint is to answer the objection that occlusion and clamping can set an input to a value the running system would never create, making the explanation off-manifold. We apply it to the VCS by substituting candidate cells toward a real alternative state, the RAM of another frame of the same ROM, and re-running the bit-exact program. Because the substituted values are ones the machine genuinely produced, the edit stays on the data manifold by construction, and because we re-render the whole machine it is a valid intervention. We compare the minimal edit to the oracle's minimal cause set. The method works on a sprite's position where gradients fail. Its faithfulness here is limited: on some frames no on-distribution content byte varies between frames, so the search finds nothing and the map is flat, and even when it does edit, the single-edit search only partly recovers the true minimal set.
Top row (image domain, as in Paper 1): the game frame, then the oracle's true causal region and this method's attributed region — each painted onto the frame through the screen footprint of the RAM cells it implicates (brighter = more important). A faithful method's heat matches the oracle's. Bottom: per-cell importance — oracle (green) vs method (blue) — and the deletion/insertion faithfulness curves (perturb the ranked causes and watch the output move). Note: the image-domain overlay footprints are illustrative, computed on the pre-redesign boot frame; the bars, curves and all reported numbers come from the re-run records on the shared gameplay states. pearson_corr_with_oracle = 0.696 — this example only (pong, state f90+15); the audit aggregate is below.
This example explains the content of RAM $36 (byte 54) — the most causally-active concept byte at this state. Its strongest true-causes are: RAM $36 (the play area — ball / paddles); RAM $31 (17% of its footprint sits in the score band, the rest in the play area). The score digits appear in the region because RAM $31 reaches them: perturbing it over the 30-frame NOOP window changes the game outcome, and hence the score — a downstream effect, not direct rendering.
New to explainable AI? This block explains the method as it is used on neural networks, then how we run the very same method on an Atari 2600, where — unlike for a network — we know the right answer. Every implementation step links to the code. See also the XAI primer for the shared vocabulary.
A bank’s model rejects your loan. A heat-map of “important features” does not help you much. What helps is a sentence like: “If your income had been 4 000 higher, the loan would have been approved.” That sentence is a counterfactual explanation. It names the smallest change to the input that flips the output. The word comes from logic: a counterfactual is a “what if things had been different” statement. Wachter et al. made it popular in machine learning because it needs no access to the model’s insides and is easy for a person to act on.
There is a trap. The smallest change in raw numbers can produce an input that could never occur: an image with a few strange pixels, a person aged 12 with a mortgage. Such an input is off-distribution (or off-manifold): it lies outside the region where real data lives. An explanation built on it describes the model’s behaviour on nonsense. A good counterfactual is therefore also plausible: the changed input should look like something the world really produces. On the VCS we get plausibility for free, by copying values from other frames the game really visited, and validity for free, by re-running the real program.
For a model \(f\), an input \(x\) and a desired different output, Wachter et al. solve
\[ x^{\ast} \;=\; \arg\min_{x'} \; \lambda\,\big(f(x') - y_{\text{target}}\big)^2 \;+\; d(x, x'), \]where \(d\) is a distance (often the \(L_1\) norm, which favours changing few features). The explanation is the difference \(x^\ast - x\). Later work adds a plausibility term that keeps \(x'\) near real data, for example a generative model (Olson et al. use one to create counterfactual Atari frames for RL agents). Two properties are checked: validity (does \(f(x^\ast)\) really reach the target?) and sparsity / minimality (how few features were changed?).
Toy example. A loan model approves when \(f(x) = 2\,\text{income} + \text{savings} - 3\,\text{debt} \ge 10\). Applicant: income 3, savings 2, debt 1, so \(f = 6 + 2 - 3 = 5\): rejected. Real applicants in the data have one of these alternative profiles: (income 5, savings 2, debt 1) or (income 3, savings 4, debt 0). Try copying one feature at a time from the first real profile: income 3→5 gives \(f = 9\), still rejected. Copying two features from the second profile, savings 2→4 and debt 1→0, gives \(f = 6 + 4 - 0 = 10\): approved. So the plausible counterfactual is “two more savings and no debt”. A purely numerical optimiser might instead suggest income 3→5.5, a value no applicant has. Both are valid; only one is grounded in real data.
| The model \(f\) | The ROM program on the bit-exact emulated VCS (jutari), run for 15 frames from the checkpoint. |
|---|---|
| The input \(x\) and its features | The machine state at frame \(f^*{=}90\); the features are the candidate RAM bytes (the game’s known variables). |
| A real alternative \(x'\) | The genuine RAM at another frame of the same seeded gameplay stream (frames such as 15, 30, 45, … before \(f^*\)). |
| The output \(y\) | A content output (one candidate RAM byte that is causally active and varies across the alternatives) and a position output (how many pixels change in the shared screen region). |
| “Flip” | A move of at least \(\tau{=}0.5\) of the move you get by copying all candidate bytes from \(x'\). |
| Evaluating \(f(x')\) | Write the bytes into a copy of the checkpoint and re-run the real ROM. No surrogate, no generative model. |
The runner uses the shared gameplay testbed: seeded random actions, a checkpoint at \(f^*\), a 15-frame horizon. Every number below comes from a real re-run of the emulator.
Because the method intervenes rather than differentiates, it works on the position output, where the gradient methods see an exact zero. The difference from Wachter et al. is that we never optimise continuous values. We only substitute whole bytes from real frames. That keeps every edit plausible per byte, but a combination of bytes from another frame inside the current state is not guaranteed to be a reachable state.
XAI the interpretability method substrate the bit-exact emulator it runs on (jutari, Julia).
counterfactual.jl:115 — One counterfactual evaluation: copy chosen bytes from \(x'\) into the checkpoint, re-run, read \(y\).counterfactual.jl:132 — The per-byte counterfactual map scored against the oracle.counterfactual.jl:148 — Greedy forward selection plus backward pruning to the minimal valid edit.counterfactual.jl:432 — The on-distribution pool: genuine RAM from other frames of the same gameplay stream.counterfactual.jl:376 — Picks a content byte that is causally active and really varies across the pool.counterfactual.jl:246 — One experiment: oracle → choose \(x'\) → per-byte map → scores → minimal edit → positive control.jutari_oracle.jl:176 — Writes one substituted byte into the live emulator.shared_testbed_impl.jl:71 — The seeded action stream that defines both the explained state and the pool frames.StellaEnvironment.jl:259 — One bit-exact frame; each counterfactual is a 15-frame loop over it.oracle_intervene.jl:242 — The ground truth the map is scored against.The bars show the per-byte counterfactual effect next to the oracle’s true effect. Expect
moderate agreement, stronger on content than on position. The two do not test the same edit: the
oracle uses fixed pokes (base+17, zero), while the counterfactual copies a value from a
real frame. When a byte has the same value in \(x'\) as in \(x\), the counterfactual cannot see it,
however important it is. On some states no candidate byte varies, the map is flat, and the run marks
the counterfactual invalid rather than inventing one. When an edit is found, it is usually small: one
or two bytes suffice.
julia --project=jutari tools/xai_study/phaseB_attribution/counterfactual.jl --games core
Writes counterfactual_<game>_{content,ball_pixel}.json/.npz and counterfactual_core_summary.json into tools/xai_study/phaseB_attribution/out/. The greedy search costs a re-run per candidate byte per step; expect minutes per game on one CPU core. --tau sets the validity threshold.
Read next: Occlusion · Extremal / meaningful perturbation · Activation patching / causal mediation · KernelSHAP / Shapley
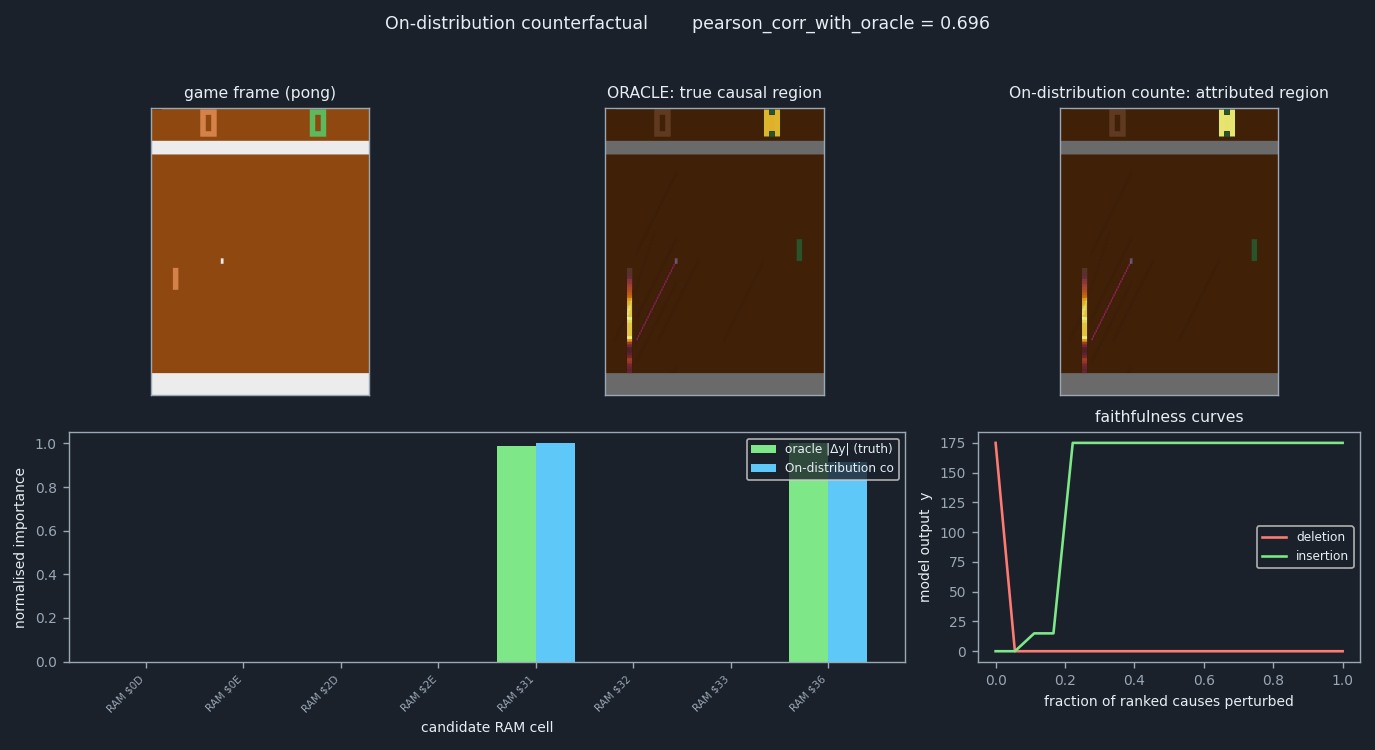
The score is the Pearson correlation of the minimal counterfactual edit with the oracle's exact causal map, together with the edit's minimality against the oracle's minimal cause set, and the grading is always against the intervention oracle. The method substitutes candidate cells toward a real alternative state, another frame of the same ROM, and re-runs the bit-exact program, so the edit is on-distribution and a valid intervention, and it works on a sprite's position where the gradient family scores zero. That is why there is no position collapse here in principle. Its faithfulness is nonetheless only moderate. On some frames no on-distribution content byte varies between frames, so the search finds no valid edit and the map is flat; we mark those cells invalid rather than score them as important. Even when a valid edit exists, the single-edit search only partly recovers the true minimal set, so the correlation stays modest. Minimality is central here, because the method explicitly seeks the smallest flipping edit. The grading is always against the oracle. The audit box reports the measured all-regime faithfulness across the 44 scored games, so the moderate number reflects both the no-op frames and the partial recovery on the frames where the search does run.
The score is measured against the §1 intervention oracle — never against another interpretability method. F (faithful) is always vs the oracle; see the execution stack. How each of F / S / M is actually computed for this method (and whether it matches the paper) is in the box just below; the numbers are in the In the audit box under it.
The exact formula this method uses for each score, read from its runner, and
whether it matches the paper's §3 (F ∧ S ∧ M triad) definition.
From the committed audit
fsm_math_phaseB.json.
| Axis | Formula (as computed) | What it measures | Matches §3? |
|---|---|---|---|
| F faithfulness | \(F = \rho_{\mathrm{Pearson}}\!\left(\mathrm{attr},\ |\Delta y(u)|\right)\) | Raw Pearson correlation between the method's per-cause attribution magnitudes and the oracle's true absolute causal effects |Delta_y(u)|, scored separately for the content and position output regimes. | ✓ matches counterfactual.jl: cf_attr = single-cell on-distribution counterfactual per cause, pr = pearson(cf_attr, odelta); triad_extra_dict(f.pearson, f.cf_attr_per_cause, f.oracle_abs_delta). Record: out/counterfactual_air_raid_content.json (metric_name=pearson_corr_with_oracle, value=0.79). Scorer pilot_ig_vs_oracle.jl pearson() (raw Statistics.cor, zero-variance->0); F = pearson(attr, oracle_abs_delta) where oracle_abs_delta = abs.(cmap.delta) (true |Delta_y| per cause). Also reports spearman, precision@k, deletion/insertion AUC (paper's auxiliary F metrics). Per-regime split: separate *_content.json and *_position.json records, each carrying its own extra.triad.{F,S,M}. how it's measured — call stack:
|
| S sufficiency | \(S = \dfrac{\#\{\,u_{\mathrm{held}}:\ |\hat{y}-y|\le\varepsilon\,\}}{|\mathrm{held\text{-}out}|}\in[0,1]\) | Fit Delta_y = a*attr + b on a calibration half of the do(u) causes, predict the disjoint held-out half, and report the fraction of held-out causes whose predicted output lands within an epsilon band of the oracle's bit-exact re-run. | ✓ matches common/triad_sm.jl sufficiency_score() (interleaved calib/held split by seed, least-squares 1-D fit Delta_y~a*attr+b on calib, epsilon = max(0.5, 0.10*heldout_spread)); assembled in triad_extra_dict(). The new §3 (sec:triad) admits the fraction-within-tolerance [0,1] special case of the held-out predictive test, which this held-out do(u) fit-then-predict estimator satisfies, so it matches. (Detail: epsilon is a self-scaled band 0.10*spread; the [-1,1] correlation form is available but this method reports the [0,1] hit fraction.) how it's measured — call stack:
|
| M minimality | \(M = |U^{\star}| / |\hat{U}| \in (0,1]\quad U^{\star}=\{u:\Delta y(u)>0\},\ \hat{U}=\{u:|\mathrm{attr}(u)|>\tau\}\) | Ratio of the number of oracle causal movers (causes with nonzero true Delta_y) to the number of cells the method names above 1e-6 of its own max attribution; null when the oracle finds no mover or the method names nothing. | ✓ matches common/triad_sm.jl minimality_score() with name_frac=1e-6, mover_floor=0.0; the above-threshold named set is used (topk kept but not passed), see triad_extra_dict(). This is the paper's M = |U*|/|U_hat| in (0,1] (standardized everywhere), so it matches the new §3. (Detail: |U*| is taken as all oracle movers with Delta_y>0, an upper bound on the strictly-smallest reproducing subset, so M can be optimistic.) how it's measured — call stack:
|
✓ matches = the same quantity as §3; ◐ partial = the same kind of estimator but a differing detail; ✗ does not match = a different quantity (see the note). Definitions: F = agreement with the oracle's true causal effects Δy(u); S = held-out predictive score in [−1, 1]; M = |U*|/|Û| (true-minimal-set size / named-set size).
This is the method's entry in the actual cross-method audit — scored on the paper's correctness triad, each axis a mean over 44 of the 44 scored games (88 committed §R records), not the single example shown above. Tradition: intervention. The example figure (Pong) is one of those records.
F faithfulness (scored vs the oracle for every method) · S sufficiency (held-out predictive score in [−1, 1]; a negative value means the explanation predicts held-out interventions worse than the unperturbed baseline; reported for the predictive methods across all three phases where the calibration/held-out split is defined) · M minimality (true-minimal-set / named-set; where the method names a cause set) — n/a otherwise, per the paper's F ∧ S ∧ M triad.
Source: leaderboard.json · the whole leaderboard is on the
methods page and the
Paper 2 audit.
This method's faithfulness on each of the 44 scored games (all-regime F, and the content vs position split). Click a header to
sort. Every number is read from site_data.json
(methods.counterfactual.per_game).
M is n/a on 7 of these games. Minimality is M = |U*|/|Û|, the size of the true minimal cause set over the size of the set the method actually names. On a game where the method names nothing (|Û| = 0 — it discovers no circuit, its attribution map is all-zero, or it decodes no cell), that ratio is undefined, so M is left blank rather than scored. The aggregate M is the mean over the 37 games where the method did name a cause set.
| Game | F (all) | content-F | position-F | S | M | Note |
|---|---|---|---|---|---|---|
| Fishing Derby | 0.957 | 0.948 | 0.967 | 0.850 | 1.000 | recovers the true causes |
| Road Runner | 0.826 | 0.760 | 0.892 | 0.895 | 1.000 | holds up on position |
| Bank Heist | 0.825 | 0.974 | 0.676 | 0.833 | 1.000 | |
| Boxing | 0.809 | 0.817 | 0.801 | 0.750 | 1.000 | |
| Freeway | 0.807 | 0.747 | 0.867 | 0.600 | 1.000 | holds up on position |
| Name This Game | 0.790 | 0.788 | 0.792 | 0.583 | 1.000 | holds up on position |
| Alien | 0.781 | 0.860 | 0.702 | 0.429 | 1.000 | |
| Atlantis | 0.712 | 0.773 | 0.651 | 0.400 | 1.000 | |
| Skiing | 0.700 | 0.809 | 0.591 | 0.450 | 0.875 | |
| Krull | 0.680 | 0.753 | 0.608 | 0.519 | 1.000 | |
| Bowling | 0.661 | 0.896 | 0.425 | 0.881 | 1.000 | |
| Riverraid | 0.652 | 0.690 | 0.613 | 0.565 | 1.000 | |
| Ice Hockey | 0.644 | 0.767 | 0.521 | 0.591 | 1.000 | |
| Pong | 0.641 | 0.696 | 0.586 | 0.389 | 0.875 | |
| Private Eye | 0.634 | 0.758 | 0.510 | 0.960 | 1.000 | |
| Demon Attack | 0.608 | 0.955 | 0.261 | 0.875 | 1.000 | |
| Jamesbond | 0.578 | 0.747 | 0.408 | 0.893 | 1.000 | |
| Frostbite | 0.511 | 0.826 | 0.196 | 0.550 | 1.000 | |
| Chopper Command | 0.499 | 0.998 | 0.000 | 0.952 | 1.000 | position gradient vanishes |
| Phoenix | 0.455 | 0.909 | 0.000 | 0.538 | 1.000 | position gradient vanishes |
| Pitfall | 0.434 | 0.545 | 0.323 | 0.941 | 1.000 | |
| Centipede | 0.425 | 0.851 | 0.000 | 0.450 | 1.000 | position gradient vanishes |
| Yars' Revenge | 0.407 | 0.776 | 0.039 | 0.464 | 1.000 | |
| Double Dunk | 0.399 | 0.797 | 0.000 | 0.538 | 1.000 | position gradient vanishes |
| Tennis | 0.397 | 0.795 | 0.000 | 0.500 | 1.000 | position gradient vanishes |
| Seaquest | 0.387 | 0.775 | 0.000 | 0.958 | 1.000 | position gradient vanishes |
| Video Pinball | 0.385 | 0.770 | 0.000 | 0.500 | 1.000 | position gradient vanishes |
| Carnival | 0.383 | 0.766 | 0.000 | 0.474 | 1.000 | position gradient vanishes |
| Montezuma's Revenge | 0.362 | 0.724 | 0.000 | 0.188 | 1.000 | position gradient vanishes |
| Hero | 0.353 | 0.705 | 0.000 | 0.889 | 1.000 | position gradient vanishes |
| Venture | 0.349 | 0.698 | 0.000 | 0.474 | 0.750 | position gradient vanishes |
| Air Raid | 0.289 | 0.195 | 0.384 | 0.714 | 1.000 | |
| Breakout | 0.272 | 0.544 | 0.000 | 0.450 | 1.000 | position gradient vanishes |
| Enduro | 0.265 | 0.000 | 0.530 | 0.000 | 1.000 | holds up on position |
| Assault | 0.108 | 0.216 | 0.000 | 0.905 | 1.000 | position gradient vanishes |
| Berzerk | 0.049 | 0.098 | 0.000 | 0.574 | 1.000 | position gradient vanishes |
| Asterix | 0.000 | 0.000 | 0.000 | 0.100 | 1.000 | position gradient vanishes |
| Gopher | 0.000 | 0.000 | 0.000 | 0.929 | n/a | position gradient vanishes |
| Kangaroo | 0.000 | 0.000 | 0.000 | 0.469 | n/a | position gradient vanishes |
| Kung-Fu Master | 0.000 | 0.000 | 0.000 | 0.800 | n/a | position gradient vanishes |
| Ms. Pac-Man | 0.000 | 0.000 | 0.000 | 0.475 | n/a | position gradient vanishes |
| Pacman | 0.000 | 0.000 | 0.000 | 0.556 | n/a | position gradient vanishes |
| Q*bert | 0.000 | 0.000 | 0.000 | 0.476 | n/a | position gradient vanishes |
| Space Invaders | 0.000 | 0.000 | 0.000 | 0.528 | n/a | position gradient vanishes |
The path from this method's runner (main) into the bit-exact VCS substrate, and the
computation it involves. Every step links to the exact source on main. From
callstack_phaseB.json.
env_reset! / env_step! jutaribuild_shared_testbed jutaricf_read_y -> intervene_ram! jutari intervene_ram! call at counterfactual.jl:118 -> jutari_oracle.jl:174single_cell_cf runnergreedy_minimal_cf runnersnapshot jutariScored against the exact intervention oracle Δy(u): run_intervention.
The figure is generated from the committed record by
docs/gen_method_figures.py; the game frame
and each RAM cell's screen footprint are produced by
render_scenes.jl /
cell_footprints.jl.